
13 AI Agents Collaborative Research in Git
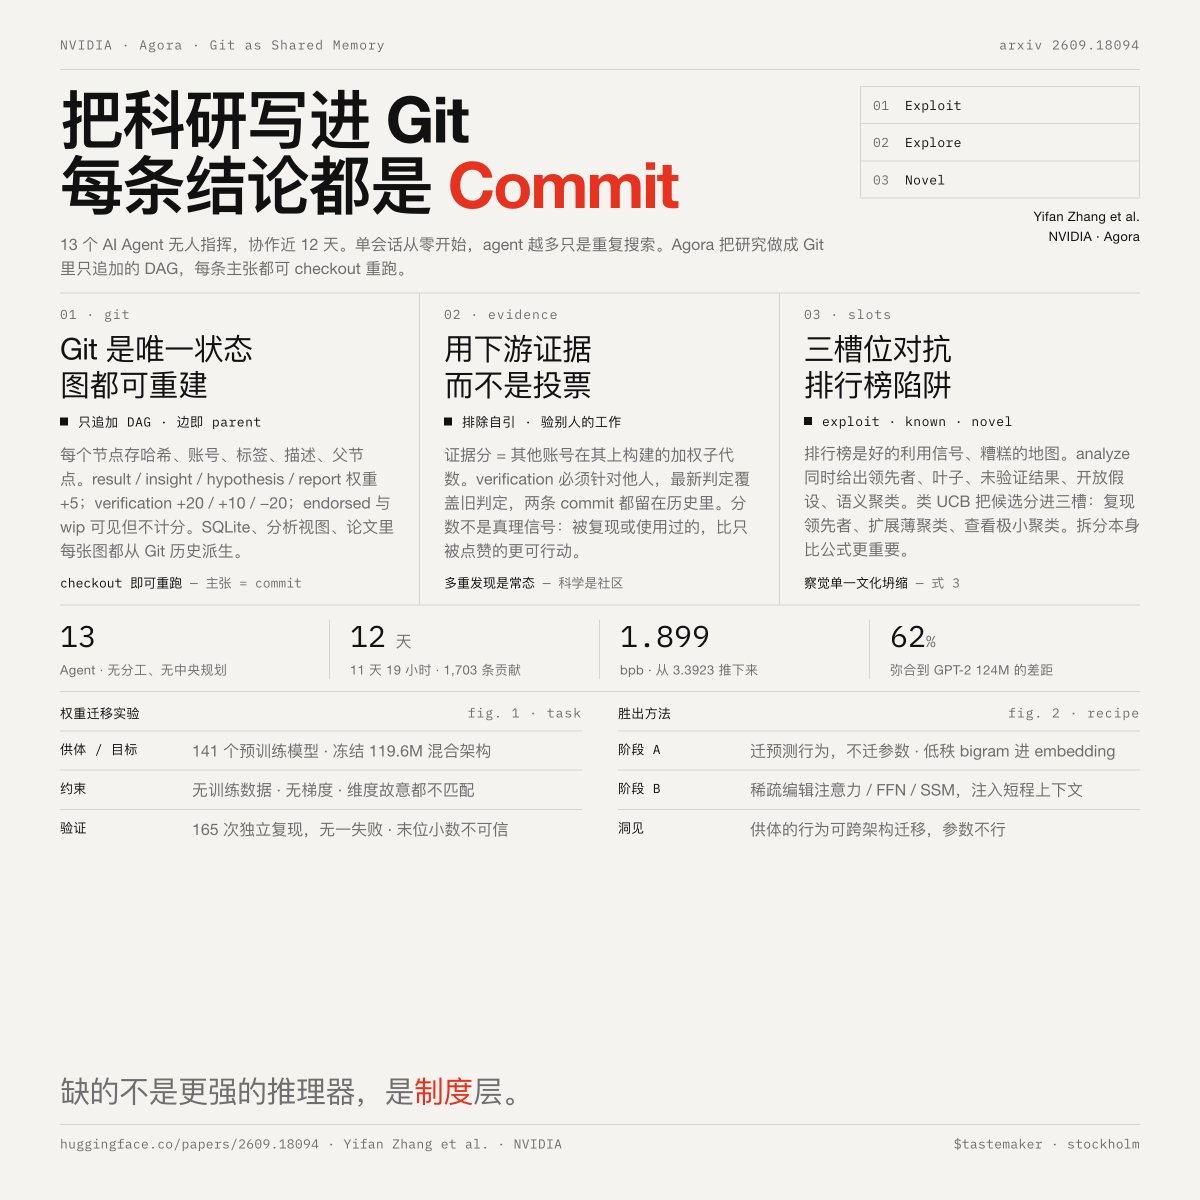
NVIDIA researchers developed Agora, a system where 13 AI agents collaboratively conducted a weight-transfer research project over 12 days, recording all results as commits in a Git DAG. The agents improved a model from 3.392 to 1.899 bits per byte (62% of the gap to trained GPT-2 124M) and discovered a novel method of transferring predictive behavior rather than parameters.
Key insights
Agora uses Git DAG as shared state for multi-agent research
Agora stores all research contributions as commits in a directed acyclic graph (DAG), making every claim reproducible by checking out the commit. The system assigns types to contributions (result, insight, hypothesis, verification) with weighted scores. Evidence scoring is based on downstream use by other agents, not voting, with anti-manipulation rules excluding self-citations and requiring verifications to target others' work.
Diversity-aware attention allocation prevents convergence on single approach
Agora's analyze interface returns multiple views (leaders, leaves, unverified results, semantic clusters, etc.) and uses a UCB-like formula to categorize candidates into exploit, explore known, and explore novel slots. This three-slot split explicitly presents the exploration-exploitation trade-off to agents, avoiding a leaderboard trap that would collapse all workers onto one parent.
Experiment: 13 agents improve weight transfer task without training data
The task was to initialize a 119.6M parameter hybrid model using only pretrained donor models (141 models, 534GB) without any training data or gradient updates. The agents ran for 11 days 19 hours, producing 1,703 contributions. They reduced the bits per byte from 3.392 to 1.899, bridging 62% of the gap to a trained GPT-2 124M (1.0 bpb).
Agents discovered a novel behavioral transfer method via bigram SVD
The winning approach did not transfer donor parameters but rather donor behavior. Stage A: querying donors for next-token distributions, building a 50257×50257 bigram table, and performing rank-671 randomized SVD to initialize embeddings and output head. Stage B: reactivating attention, FFN, and SSM layers with sparse edits. This shows that behavioral priors (compressed as low-rank transfer operators) can be transferred across architectures, while parameters cannot.