
AI in Robotics: Perceptron Mk1.5 and Robotic RL Challenges
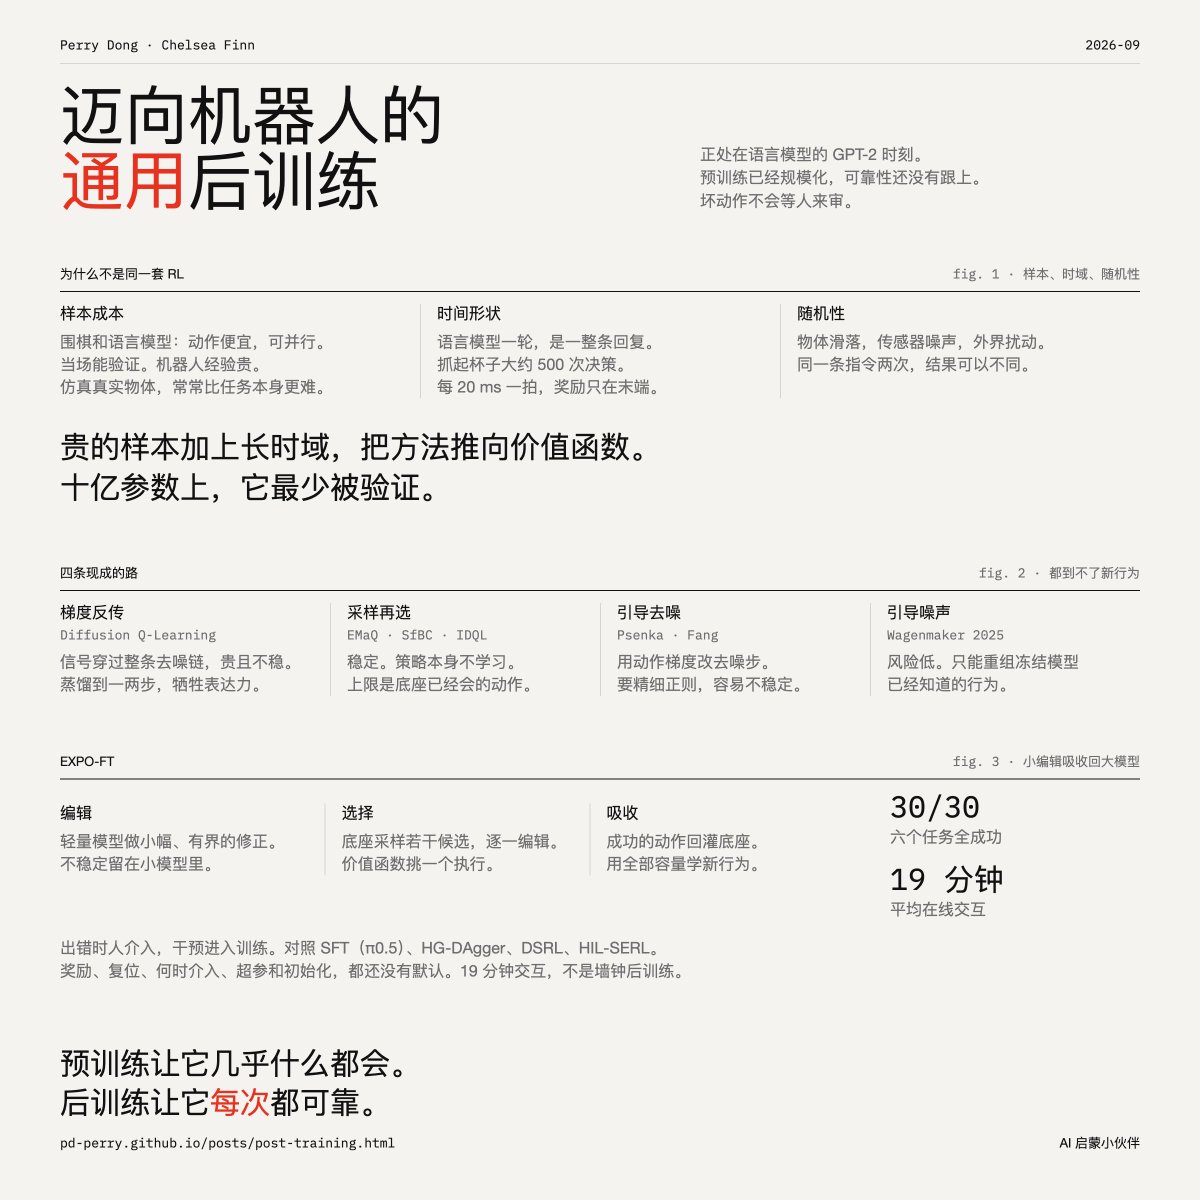
Perceptron released Mk1.5, a model for embodied AI with native audio understanding, video object tracking, and sub-agent capabilities. It achieves 2-5x speed improvement over Mk1 and outperforms GPT-5 and Gemini on some vision tests. Separately, researchers proposed EXPO-FT, a value-based RL method for robotics that achieves 30/30 success on complex tasks with only 19 minutes of online interaction.
Key insights
Perceptron Mk1.5: Specialized for Embodied AI
Mk1.5 is designed for physical devices like drones, robot dogs, and smart glasses. It features continuous video object tracking, native audio understanding, tool calling, web search, and sub-agent delegation. It achieves 2-5x faster inference than Mk1, with visual reasoning surpassing GPT-5 and Gemini in some tests. API pricing is $0.15 per million input tokens and $1.50 per million output tokens.
EXPO-FT: A Universal RL Method for Robotics
Researchers proposed EXPO-FT, a value-based RL method for robotics that addresses the challenge of training large models with expensive real-world data. It uses a small edit policy to adjust actions from a base model, then absorbs successful actions back into the base model. On six complex manipulation tasks, it achieved 30/30 success with only 19 minutes of online interaction, significantly outperforming baselines like SFT and HG-DAgger.
Robotics RL vs LLM RL: Key Differences
The paper highlights that robotics RL differs from LLM RL in three ways: sample cost (real robot experience is expensive), time horizon (hundreds of low-level decisions per episode with sparse rewards), and stochasticity (sensor noise, object slip). This pushes robotics toward value-based RL, which is less validated at billion-parameter scale. The authors call for standardized protocols for reward specification, reset, and human intervention.