
AI self-improvement level frameworks and Anthropic internal dashboard
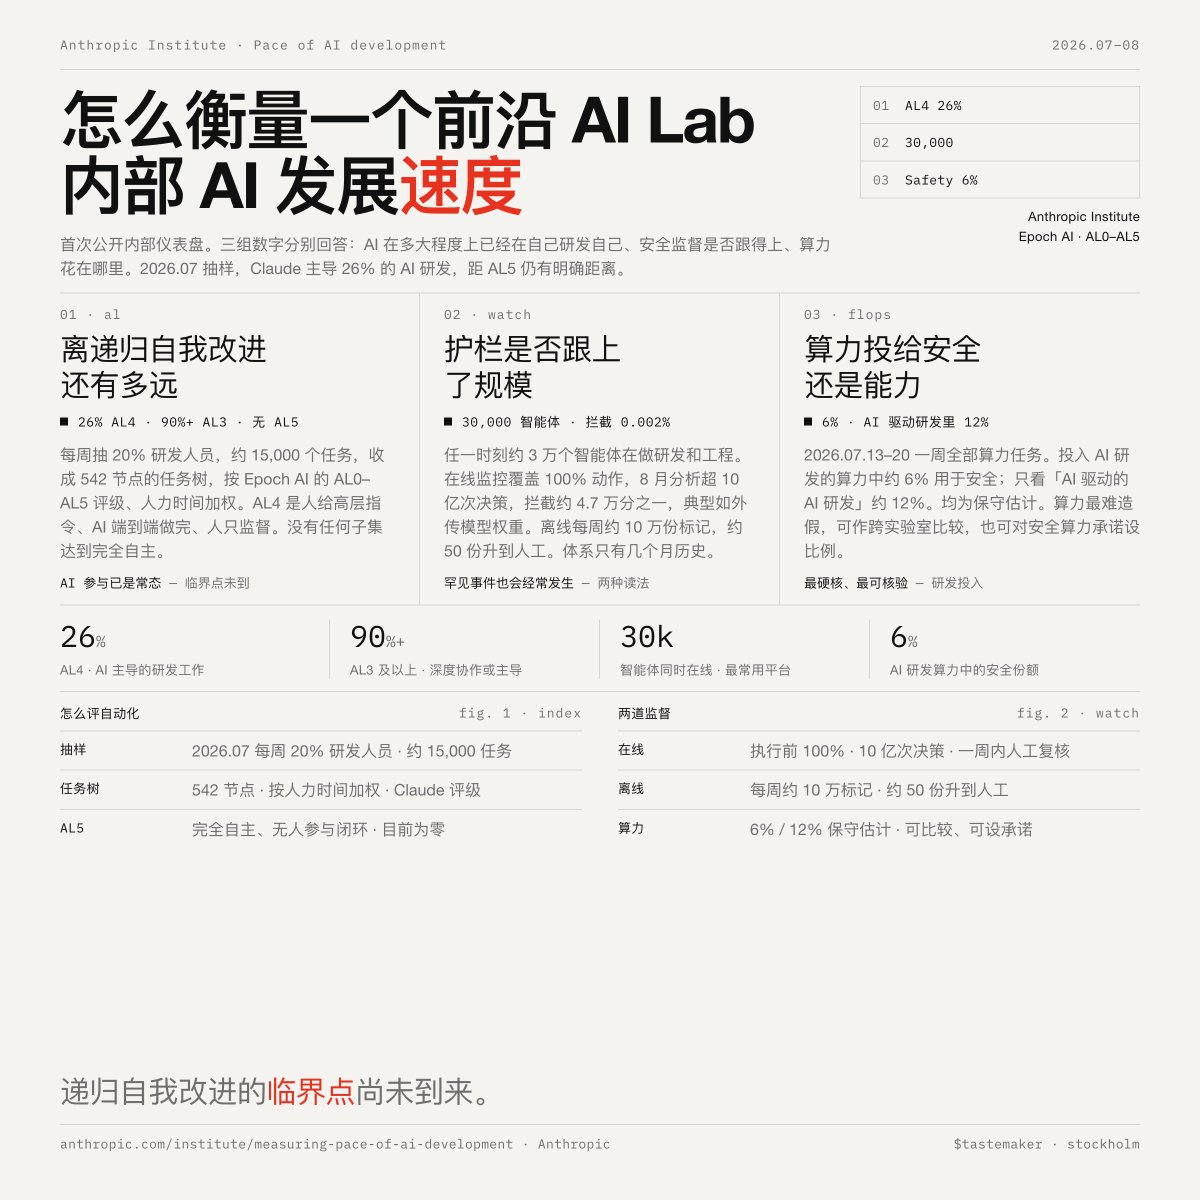
Anthropic publicly shared an internal dashboard on September 17, 2026 with three metrics: R&D automation index, agent oversight, and compute allocation. As of July 2026, 26% of AI R&D work reached AL4 (AI-led, human oversight), over 90% reached AL3+. No work subset reached AL5 (fully autonomous). Over 30,000 simultaneous agents were running, with only 0.002% of actions intercepted and 6% of R&D compute allocated to safety.
Key insights
R&D automation index: AL4 status as a baseline
Anthropic sampled 20% of R&D staff work weekly, producing ~15,000 tasks organized into a 542-node task tree. Each task was rated on the AL0-AL5 scale by Claude. As of July 2026, 26% of R&D work reached AL4 (AI-led, human oversight only), and over 90% reached AL3+ (deep AI collaboration or leadership). No subset reached AL5 (fully autonomous, closed-loop). This provides a baseline for measuring acceleration in future periods.
Agent oversight: low interception rate with ongoing validation
At peak, ~30,000 agents run simultaneously. Online monitoring intercepts 100% of actions in seconds, with only 0.002% (1 in 47,000) intercepted in August 2026 (analyzing over 1 billion decisions). Typical intercepts involve exporting model weights. Offline monitoring flags ~100,000 conversation records weekly (0.1-0.2%), with ~50 escalated to human review. Anthropic notes that rare events become frequent at this scale, and the system has only been operational for a few months.
Compute allocation: 6% for safety
Analysis of all ~10,000 compute tasks in the week of July 13-20, 2026 showed that approximately 6% of compute used for AI R&D was allocated to safety work. When considering only AI-driven AI R&D, the safety share was approximately 12%. Anthropic described these as conservative estimates. This is the most verifiable metric, setting a benchmark for future cross-lab comparisons.
Five-level self-improvement framework from 30+ researchers
A separate 75-page paper by 30+ researchers proposed a five-level taxonomy for AI self-improvement. Level 1: humans decide what to improve. Level 5: AI rewrites the process of creating the next AI. The authors reviewed 491 papers and found 75% still at Levels 1-2, with fewer than 6% reaching Level 5. This taxonomy provides an external academic framework consistent with Anthropic's AL0-AL5 scale.