
Alibaba/Qwen releases open-source Qwen-Image-2.1 model
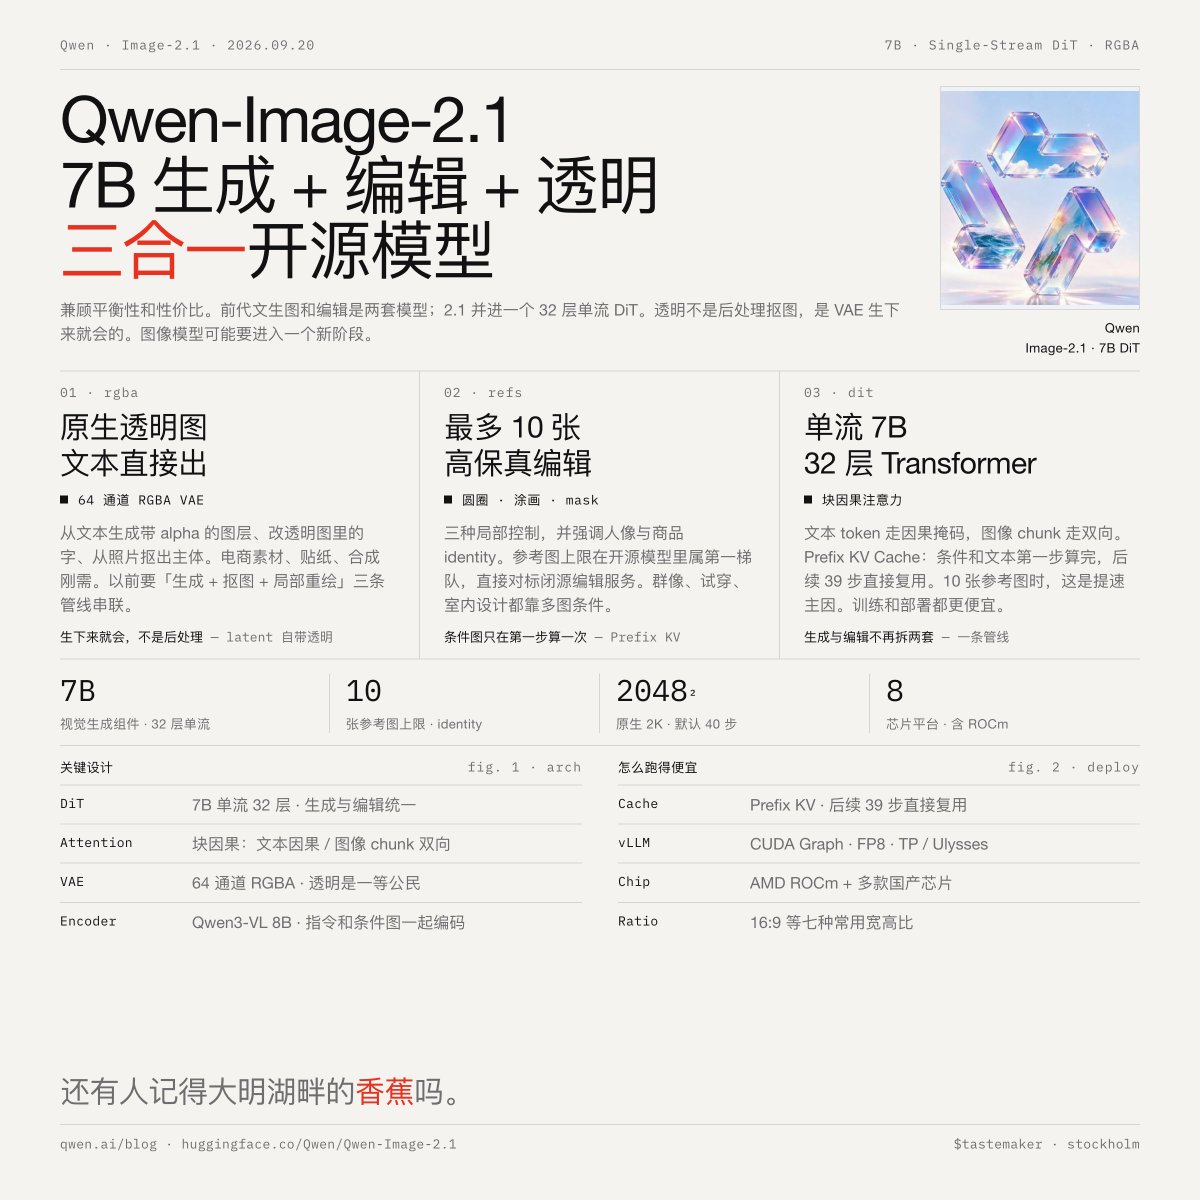
Alibaba Qwen open-sourced Qwen-Image-2.1, a 7B model combining generation, editing, and transparent image output. It supports up to 10 reference edits, 2K resolution, and native RGBA. With GGUF quantization, it runs on consumer GPUs with 12GB VRAM.
Key insights
Single-stream DiT model merges generation and editing tasks
Qwen-Image-2.1 uses a 32-layer single-stream DiT with block-causal attention, unifying text-to-image and editing capabilities that previously required separate models. This reduces training and deployment costs. The prefix KV cache reuses condition embeddings across denoising steps, speeding inference.
RGBA output via 64-channel VAE for true transparent generation
The model uses a 64-channel RGBA autoencoder to produce images with alpha channel directly, without post-processing. This is essential for e-commerce assets, stickers, and compositing workflows. It can also edit transparent text and extract subjects from photos.
Multi-reference editing with identity preservation
The model supports up to 10 reference images with local control via circle annotation, paint marks, or independent masks. It emphasizes identity preservation for portraits and merchandise, competing with closed-source editing services like GPT-Image.
Available in quantized versions for consumer GPUs with 12GB VRAM
UnslothAI released GGUF quantized versions that run on 12-16GB VRAM (Q4_K_M) or even 6GB VRAM with offloading. The model also supports CUDA Graph, FP8 quantization, and TP/Ulysses parallelism for vLLM deployment. It is compatible with 8 chip platforms including AMD ROCm and domestic accelerators.
7B parameters with Qwen3-VL text encoder and 2K native resolution
The model uses Qwen3-VL 8B as a text encoder for better instruction following. Default resolution is 2048x2048, with 7 aspect ratios supported. Qualitatively improved text rendering, portrait lighting, and texture realism.