
Artificial Analysis Coding Agent Index v2.1: Claude Fable 5.2 and Opus 5.5 Tie at 58
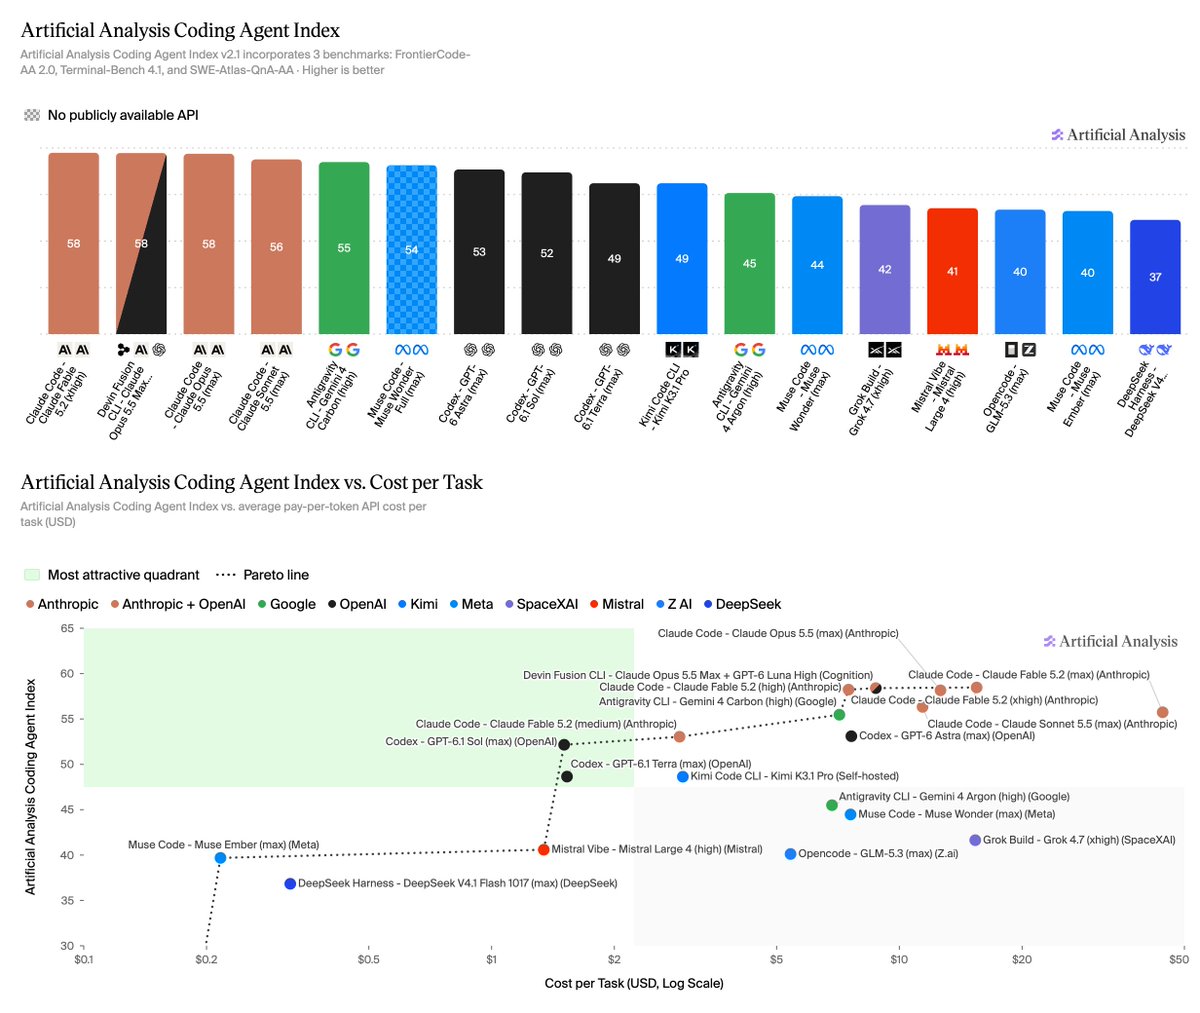
Artificial Analysis released Coding Agent Index v2.1, upgrading FrontierCode to 2.0 and Terminal-Bench to 4.1. Claude Fable 5.2 and Claude Opus 5.5 share the lead at 58, while index scores fell by 5 points on average due to the FrontierCode-AA 2.0 upgrade. Cost per task among configurations scoring 48 or higher ranges from $1.51 to $44.22.
Event version 1.
Key insights
Shared top score
Claude Fable 5.2 scores 58 at both xhigh and high effort in Claude Code. Claude Opus 5.5 (max) scores 58 in Claude Code and, paired with GPT-6 Luna High, in Cognition's Devin Fusion CLI.
Index components upgraded
FrontierCode-AA 2.0 replaces FrontierCode v1.1 with 132 real-world coding tasks graded on whether a repository maintainer would merge the change. Terminal-Bench 4.1 keeps the same 66 tasks but uses updated verifiers for reliability and resistance to reward hacking.
Scores decline in v2.1
Index scores are lower in v2.1, driven by the FrontierCode-AA 2.0 upgrade, with models scoring 5 points lower on average. Codex with GPT-6.1 Terra (max) is the only configuration that did not fall between versions, staying within 1 point of its prior score.
Cost spread among top configurations
Cost per task varies roughly 30x among configurations scoring 48 or higher, from $1.51 for Codex with GPT-6.1 Sol (max, 52) to $44.22 for Claude Code with Claude Fable 5.2 (max, 56).
Other leading configurations
Claude Fable 5.2 (max) scores 56 as more attempts hit task time limits. Claude Sonnet 5.5 (max, 56) in Claude Code and Gemini 4 Carbon (high, 55) in Antigravity CLI follow.