
Artificial Analysis Launches Coding Agent Index v2.0, Claude Opus 5.5 Leads at 61.7
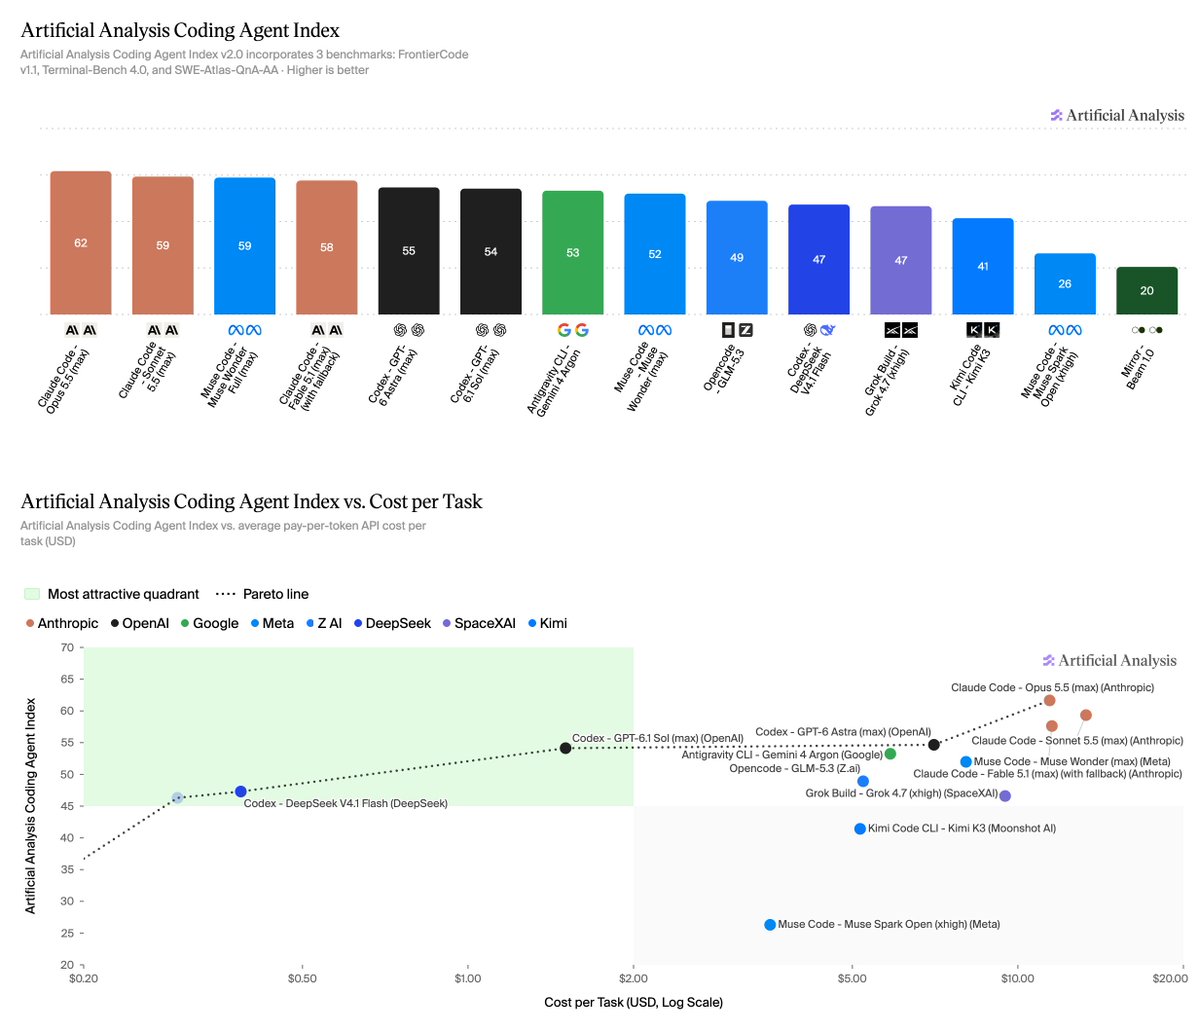
Artificial Analysis released Coding Agent Index v2.0, replacing DeepSWE with Cognition's FrontierCode v1.1 and revising SWE-Atlas-QnA grading. The index now covers 290 tasks across three equally weighted benchmarks, with Claude Code running Claude Opus 5.5 leading at 61.7.
Event version 1.
Key insights
Claude Opus 5.5 tops the index
Claude Code with Claude Opus 5.5 (max) scores 61.7, followed by Claude Code with Claude Sonnet 5.5 (max) at 59.3 and Muse Code with Muse Wonder Full (max) at 58.9. Three of the top four configurations use Claude Code.
FrontierCode v1.1 replaces DeepSWE
FrontierCode v1.1 from Cognition contains 100 software engineering tasks on real open-source repositories with a private test set, graded on whether a maintainer would merge the change. Attempts flagged for accessing solution material score zero.
SWE-Atlas-QnA grading revised
SWE-Atlas-QnA-AA keeps Scale AI's 124 repository Q&A tasks but rewords 127 of 1,306 rubric criteria and uses GPT-6 Luna (xhigh) as judge with five votes per criterion. Mean score across 21 configurations falls 1.7 points, from 58.8% to 57.1%.
Index scores drop versus v1.5
Across 21 configurations evaluated on both versions, the mean Index score moves from 54.8 to 47.4, with 20 of 21 moving down. The shift comes mainly from FrontierCode v1.1, where configurations average 45.1% against 65.6% on DeepSWE v1.1.
Four configurations on cost frontier
Codex with DeepSeek V4.1 Flash (max) scores 47.3 at $0.39 per task, Codex with GPT-6.1 Sol (max) 54.1 at $1.50, Codex with GPT-6 Astra (max) 54.7 at $7.04 and Claude Code with Claude Opus 5.5 (max) 61.7 at $11.42. Costs are pay-per-token API costs.