
Artificial Analysis Launches Intelligence Index v5 With Private Datasets
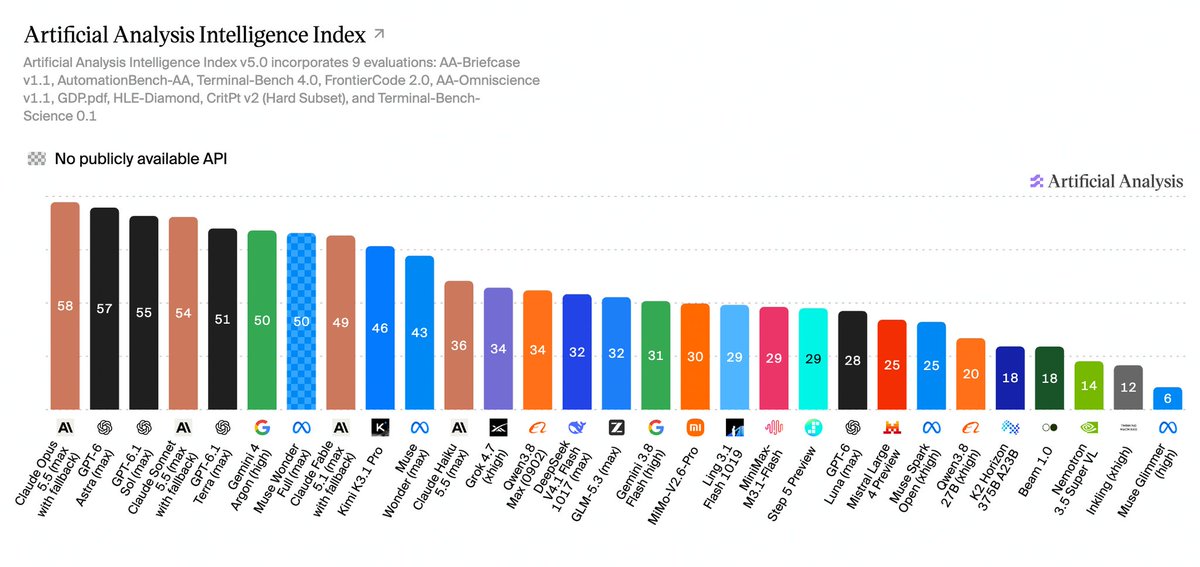
Artificial Analysis announced Intelligence Index v5, its largest upgrade since v4, with 60% of the Index now based on private test sets or held-out answers. The release adds FrontierCode 2.0 and Terminal-Bench-Science, upgrades HLE-Diamond, AA-Omniscience v1.1 and CritPt v2, and introduces the Progress Index v1. Claude Opus 5.5 leads at 58, while the open weights gap widens from 3 to 12 points.
Event version 1.
Key insights
Majority private datasets
With v5, 60% of the Intelligence Index is based on evaluations with private test sets or held-out answers, the first time the majority of the Index is built on private datasets.
New and upgraded benchmarks
FrontierCode 2.0 and Terminal-Bench-Science join the Index, while HLE-Diamond replaces Humanity's Last Exam, AA-Omniscience v1.1 is updated, and CritPt v2 becomes a private 40-question subset run with a code-execution tool.
Top model rankings
Claude Opus 5.5 (max) leads at 58, ahead of GPT-6 Astra (max, 57) and GPT-6.1 Sol (max, 55), with Anthropic and OpenAI holding the top five models and Gemini 4 Argon (high) next at 50.
Open weights gap widens
The open weights gap widens from 3 points to 12, with Kimi K3.1 Pro (weights not yet released) the top open weights model at 46 and released-weights leaders DeepSeek V4.1 Flash 1017 (max) and GLM-5.3 (max) at 32.
Cost per task spread
Cost per task varies by more than 13x among leading models, from GPT-6.1 Terra (max) at $0.96 per Intelligence Index task to Claude Fable 5.1 (max) at $13.04.