
Block-causal attention and prefix KV cache speed up multi-image editing
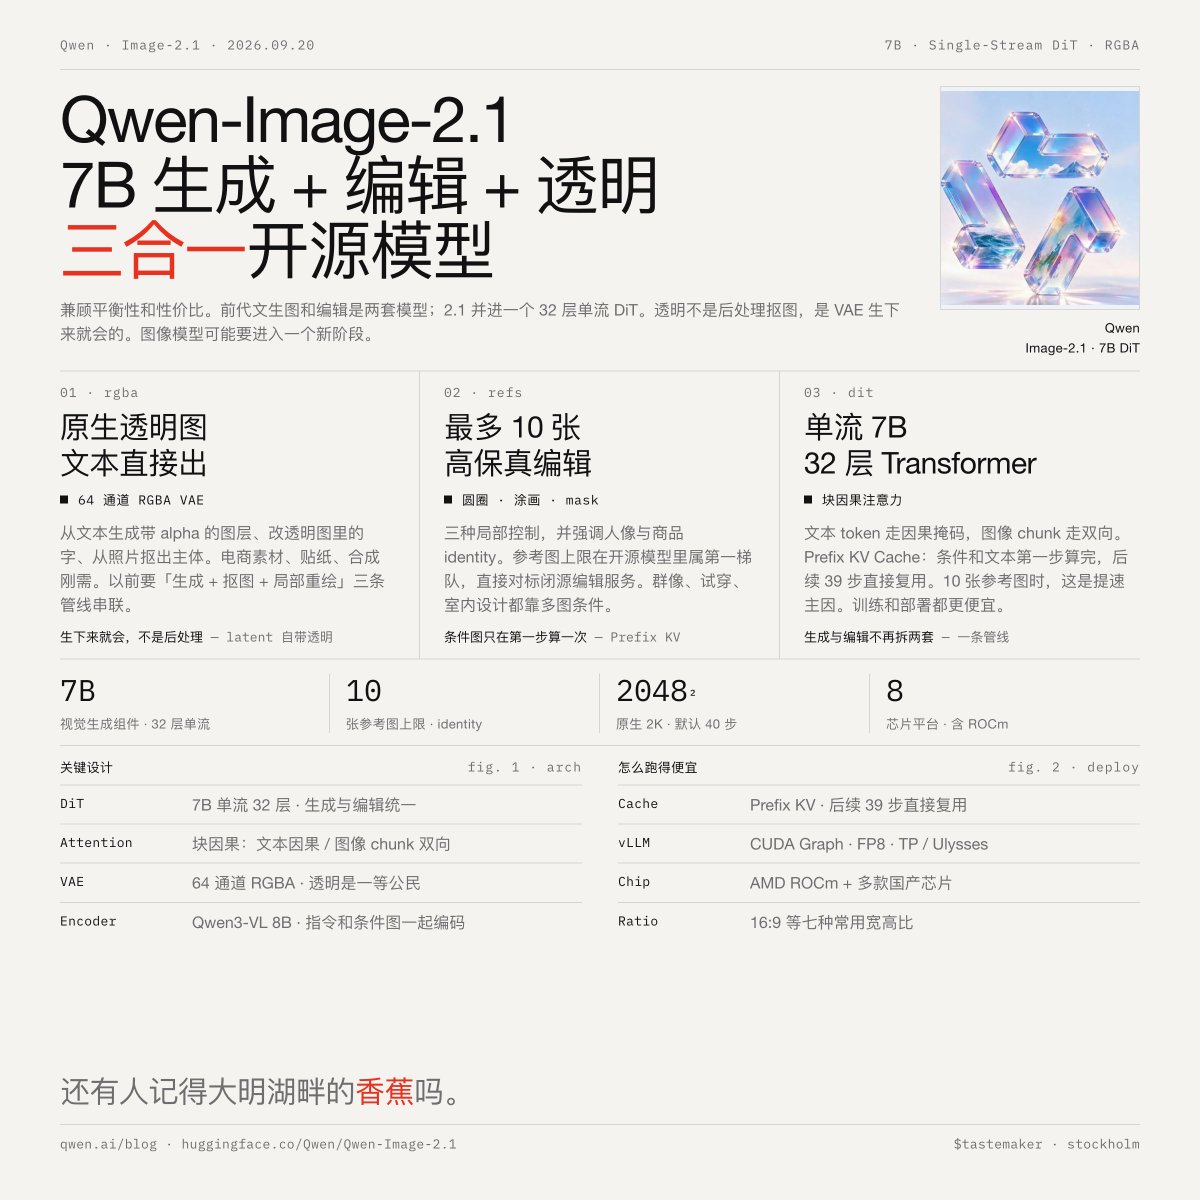
The post describes a mixed-granularity attention design: text tokens use causal masking, image chunks use bidirectional masking. This enables prefix KV cache where conditional graphs and text are computed once in the first denoising step, reused for the remaining 39 steps, significantly speeding up multi-image editing with up to 10 reference images.