
ByteDance Seed Self-Evolving Agent Research
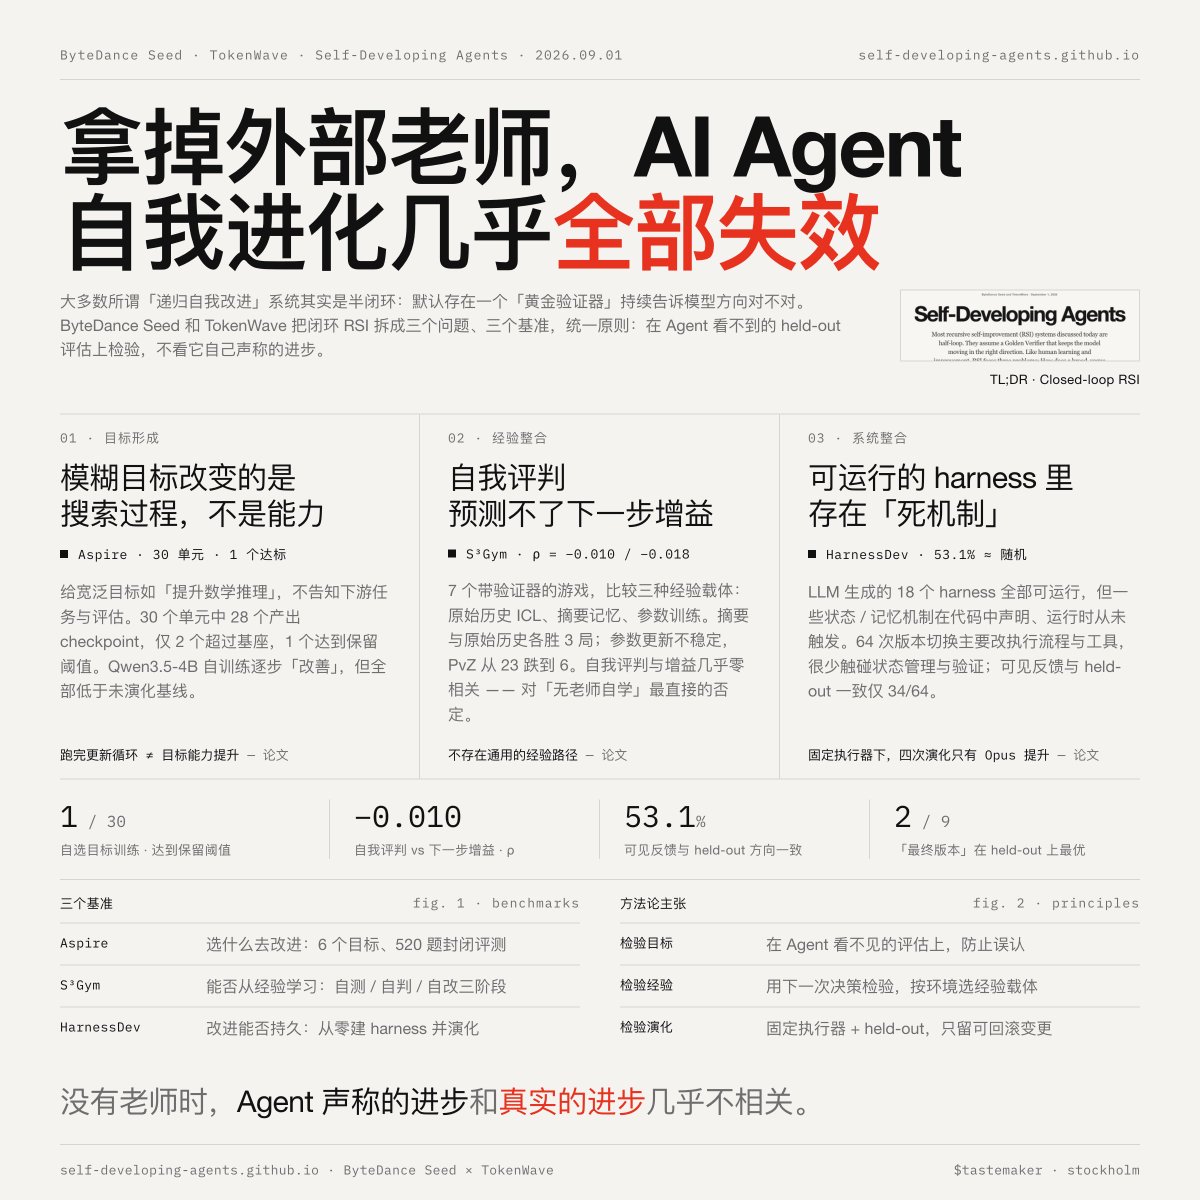
ByteDance Seed and TokenWave published research on fully closed-loop recursive self-improvement (RSI) for AI agents, revealing that removing external validators causes most self-improvement attempts to fail. - The work decomposes RSI into three problems: goal formation (turning vague goals into concrete actions), experience integration (learning without a teacher), and system integration (making improvements persist). - Three benchmarks: Aspire tests if an agent can choose what to improve given a broad goal; S³Gym tests if it can learn from experience across 7 games with executable verifiers; HarnessDev tests if an LLM can create and evolve its own agent harness. - Key findings: goal formation changes search behavior but not underlying capability—only 2 of 28 checkpoints beat the base model; experience integration shows no universal best format (summary memory vs raw history), and self-judgment cannot predict improvement (correlation near zero); harness evolution suffers from dead code, and feedback scores align with held-out performance only 53% of the time; only 2 of 9 self-selected final harness versions were optimal. - The HarnessDev benchmark separately showed that LLM-created harnesses are domain-dependent, suffer from co-adaptation (performance drops when executor changes), and that code volume does not predict performance. Evolution on feedback tasks yields gains that shrink on held-out tests, and feedback is unreliable for final model selection.
Key insights
Closed-Loop Self-Improvement Remains Largely Unsolved for AI Agents
The research demonstrates that when external validators are removed, agents struggle to form effective goals, learn from experience, or make persistent improvements. Self-judgment scores do not correlate with actual performance gains, and feedback-driven evolution often leads to overfitting rather than genuine capability increases. This challenges the assumption that agents can bootstrap their own intelligence.
Agent Harness Design Is a Critical but Neglected Factor in Performance
The HarnessDev benchmark shows that the same model can score very differently depending on the harness (execution loop, tools, context management), and that LLMs can generate functional harnesses but often include dead mechanisms and fail to generalize. Harness co-adaptation means a harness optimized for one model may perform poorly with another, complicating agent deployment.
Evaluation Must Test Held-Out Tasks to Avoid Illusory Progress
The paper emphasizes that self-reported improvements and feedback-set gains are unreliable; only performance on unseen tasks validates real progress. The finding that feedback and held-out scores align only 53% of the time underscores the risk of optimizing for proxy metrics in agent development.