
Claude Opus 5.5 Released with Improved Performance and Cost
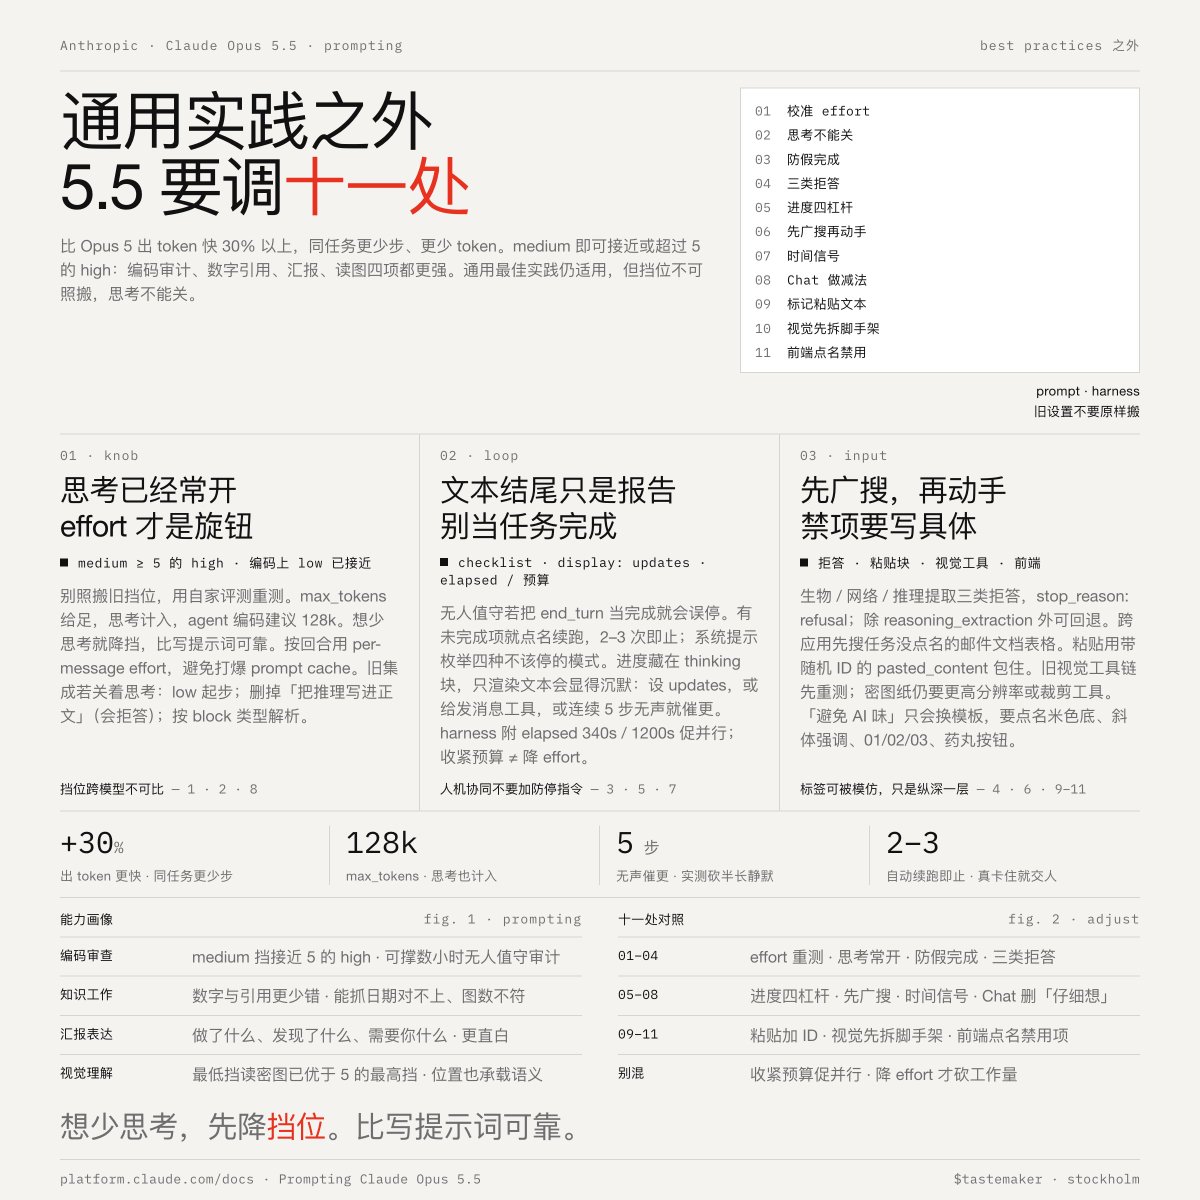
Anthropic launched Claude Opus 5.5, matching the performance of flagship Fable 5.1 on most tasks while costing 40% less than Opus 5. Input/output pricing is $4/$20 per million tokens, with cache read reduced to $0.2. Output speed is 30% faster. Early testers reported completing a 200k-line code audit in under 3 hours versus 20+ hours for Opus 5.
Key insights
Performance and Cost Improvements
Opus 5.5 achieves performance parity with Fable 5.1 on most work tasks, while reducing cost by 40% compared to Opus 5. Input/output prices are $4/$20 per million tokens (20% cheaper than Opus 5), and cache read drops from $0.5 to $0.2. Output speed is 30% faster. In a head-to-head comparison with GPT-6 Astra on Terminal-Bench 4.0, Opus 5.5 scored equally at about 40% of the cost.
Real-World Capability Examples
An early tester used Opus 5.5 to audit and fix a 200,000-line codebase in under 3 hours, compared to 20+ hours for Opus 5 (2.5x fewer tokens). In an internal HAProxy rewrite from C to Rust, both Opus 5.5 and Fable 5.1 passed almost all regression tests; Opus 5.5 took 9.5 hours vs 12 hours for Fable 5.1, with 51% lower cost. In financial report writing from web data, Opus 5.5 produced 16 of 18 hallucination-free reports, while Fable 5.1 and Opus 5 had zero passing.
Safety Restrictions and Security Measures
Opus 5.5's capabilities in cybersecurity and biology are close to Mythos 5.1, so it inherits Fable 5.1's safety guardrails: fixing its own code is allowed, but most cybersecurity tasks are automatically handed to Opus 4.8; biology work is restricted. Universities and pharmaceutical labs can apply for the Life Sciences Verification Program to unblock restrictions. A verification program for security practitioners will open in coming weeks.
Developer Workflow Adjustments Required
Key changes for developers: (1) Effort calibration is crucial – medium effort in Opus 5.5 matches or exceeds high effort in Opus 5; (2) Reasoning mode cannot be disabled; (3) Anti-distillation measures as of August 31 prevent modifying historical context to extract reasoning traces; (4) For unattended tasks, prevent false completion by using checklists and system prompts; (5) Vision understanding improved, especially with low effort.
Improvements in Clarity and Instruction Following
Opus 5.5's writing style has been updated to put the most important conclusion first and better follow user instructions. The model is less verbose and avoids jargon compared to Opus 5. These improvements are significant for chat interactions and report generation.