
Cohere Open Sources Megakernel Inference System Outperforming vLLM
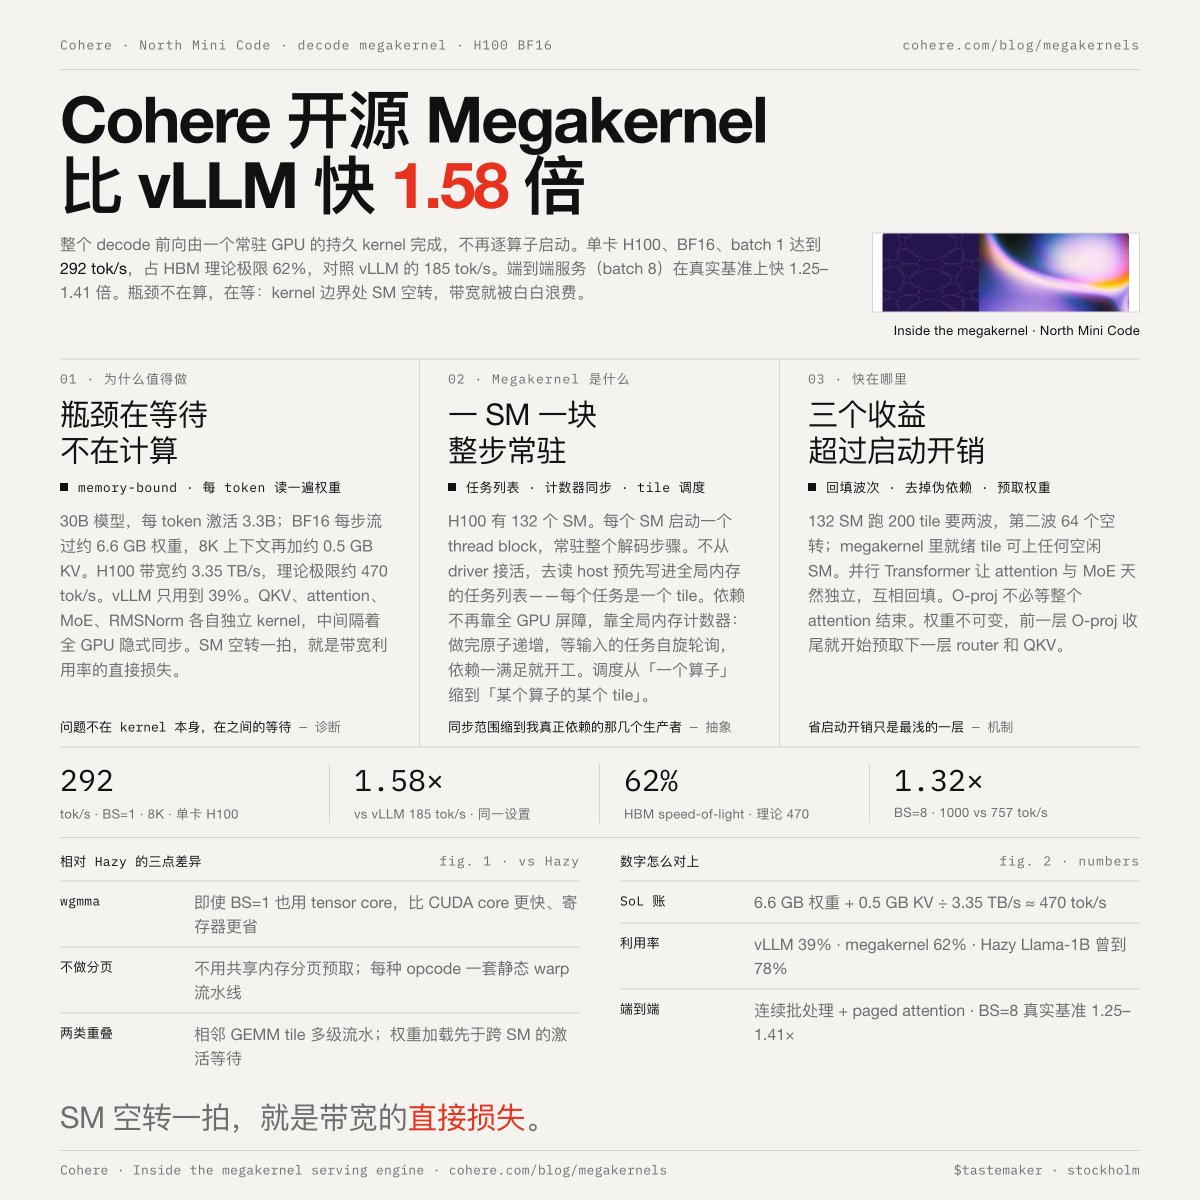
Cohere open-sourced a decode megakernel serving system for LLM inference. On a single H100 with BF16, batch size 1 achieves 292 tok/s (62% of H100 bandwidth limit), 1.58x faster than vLLM (185 tok/s). End-to-end service at batch size 8 is 1.25-1.41x faster on real benchmarks. The system uses a persistent kernel per SM that reads tasks from a global memory queue, eliminating kernel launch overhead and coarse synchronization. Key improvements: filling wave quantization gaps, removing false dependencies via fine-grained counters, and aggressive weight prefetching. Cohere built for their 30B North Mini Code model.
Key insights
Megakernel Design Dramatically Improves Decode Throughput
Cohere's open-source megakernel system keeps a persistent thread block per SM for the entire decode step. Tasks are fetched from a host-written global memory queue. Synchronization uses atomic counters instead of full-GPU barriers. This eliminates kernel launch overhead, reduces underutilization from wave quantization, and removes false dependencies. On H100, batch 1 decode reaches 292 tok/s, 1.58x faster than vLLM's 185 tok/s.
Performance Gain Goes Beyond Kernel Launch Savings
Three deeper mechanisms contribute: (1) Filling unused SM cycles when kernel tile counts don't evenly divide SM count; (2) Eliminating false dependencies where one output waited for an entire kernel to finish; (3) Prefetching immutable weights before activations are ready. Cohere's system also uses tensor cores (wgmma) even at batch 1, avoids shared memory paging bugs, and implements multi-level pipeline overlapping.
Built for Cohere's 30B North Mini Code Model
The system is designed for Cohere's North Mini Code, a 30B parameter model. Each token activates 3.3B parameters, requiring ~6.6 GB of weights in BF16 plus ~0.5 GB KV cache for 8K context. The H100 HBM bandwidth is ~3.35 TB/s giving a theoretical limit of ~470 tok/s. vLLM achieved only 39% of that (185 tok/s); Cohere's megakernel reaches 62% (292 tok/s).