
DeepSeek V4.1 Flash: Agent scaffold benchmark comparison
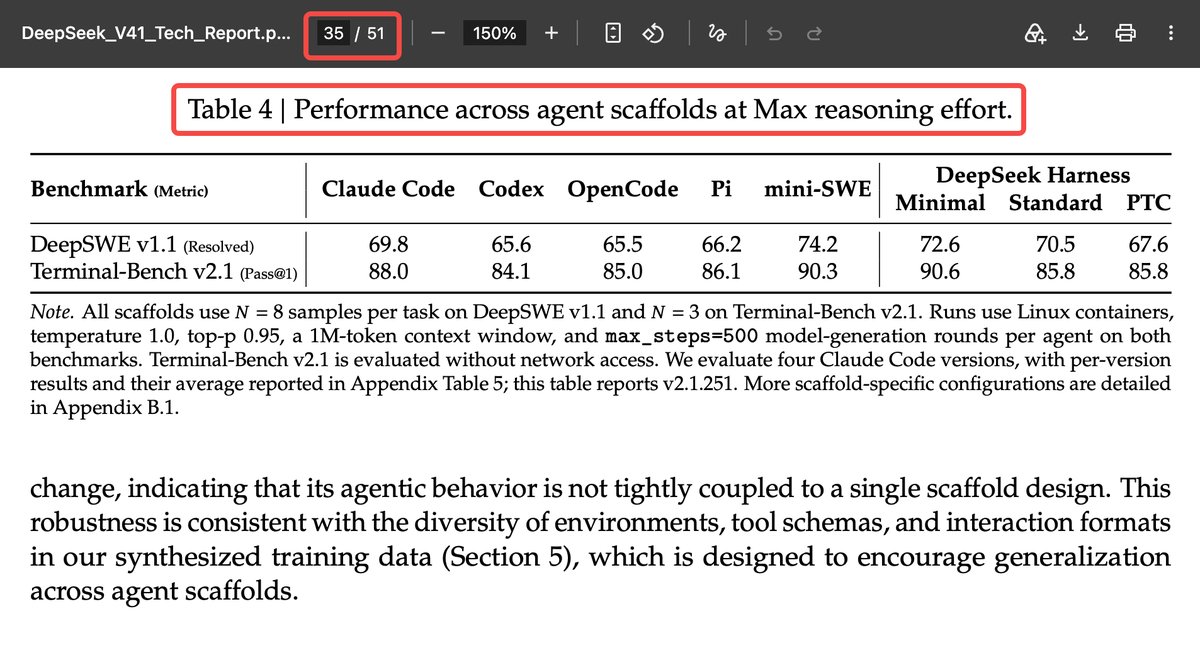
DeepSeek V4.1 Flash's technical report section 5.3.4 compares performance across different coding agent scaffolds to show the model is not dependent on any specific harness. Benchmarks: DeepSWE v1.1 and Terminal-Bench v2.1. Results: third-party frameworks performed well (Claude Code 69.8 on DeepSWE, mini-SWE 74.2 highest). DSH internal modes showed tools don't always help (Minimal 72.6, Standard 70.5, PTC 67.6). Terminal-Bench scores clustered tightly (84.1–90.6). Claude Code was tested across 4 versions with stable results (mean 68.9 on DeepSWE, mean 87.8 on Terminal-Bench).