
DeepSeek V4-Flash Official Release and Codex Integration
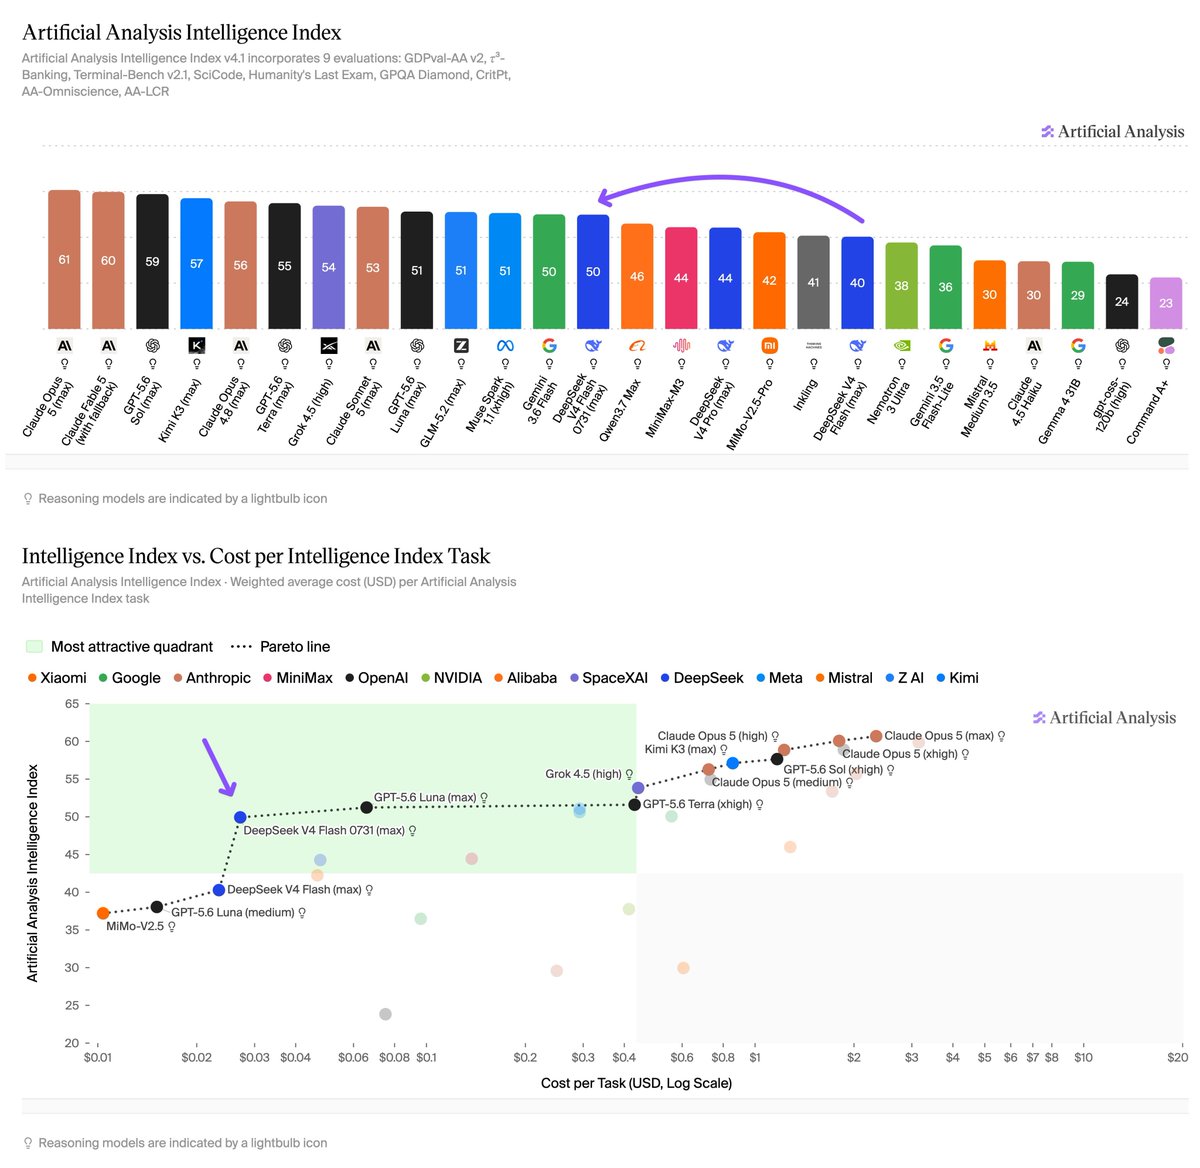
DeepSeek released the official V4-Flash API (version 0731), a 284B total parameter Mixture-of-Experts model with 13B activated parameters. Architecture unchanged from the preview; improvements come from post-training focused on agent capabilities. It surpasses the larger V4-Pro preview on all nine agent benchmarks and ranks among the top three open-source models. The API natively supports OpenAI's Responses API format for Codex, with a one-click setup script that switches all Codex clients to DeepSeek. Pricing is $0.14/$0.28 per million input/output tokens—89 times cheaper than Opus 4.8—with a 1-million-token context window. The app and web versions remain unchanged. The V4-Pro official version is not yet released, with only a 'coming soon' timeline.
Key insights
Post-Training Alone Drives Significant Agent Performance Gains
Without changing the 284B MoE architecture, post-training improvements enabled V4-Flash to surpass the larger V4-Pro preview on nine agent benchmarks. This demonstrates that agent-specific post-training can yield larger gains than scaling parameters, and that the cheaper Flash model can outperform the more expensive Pro preview in agent tasks.
Native Codex Integration Removes Friction for Developers
V4-Flash now natively supports the Responses API format, eliminating the need for proxy translation layers to connect with Codex. DeepSeek provides a one-click configuration script and pre-configured system prompts, making adoption seamless across Codex CLI, ChatGPT desktop, and VS Code extension.
Extreme Cost Differential Reshapes AI Coding Economics
At $0.14/$0.28 per million tokens, V4-Flash is 89 times cheaper than Opus 4.8. For high-volume agent loops, this changes the cost structure from a significant expense to a negligible one, enabling use cases that were previously economically unviable.