
Gemini 3.0 Pro, AUI Research and LLM Benchmark
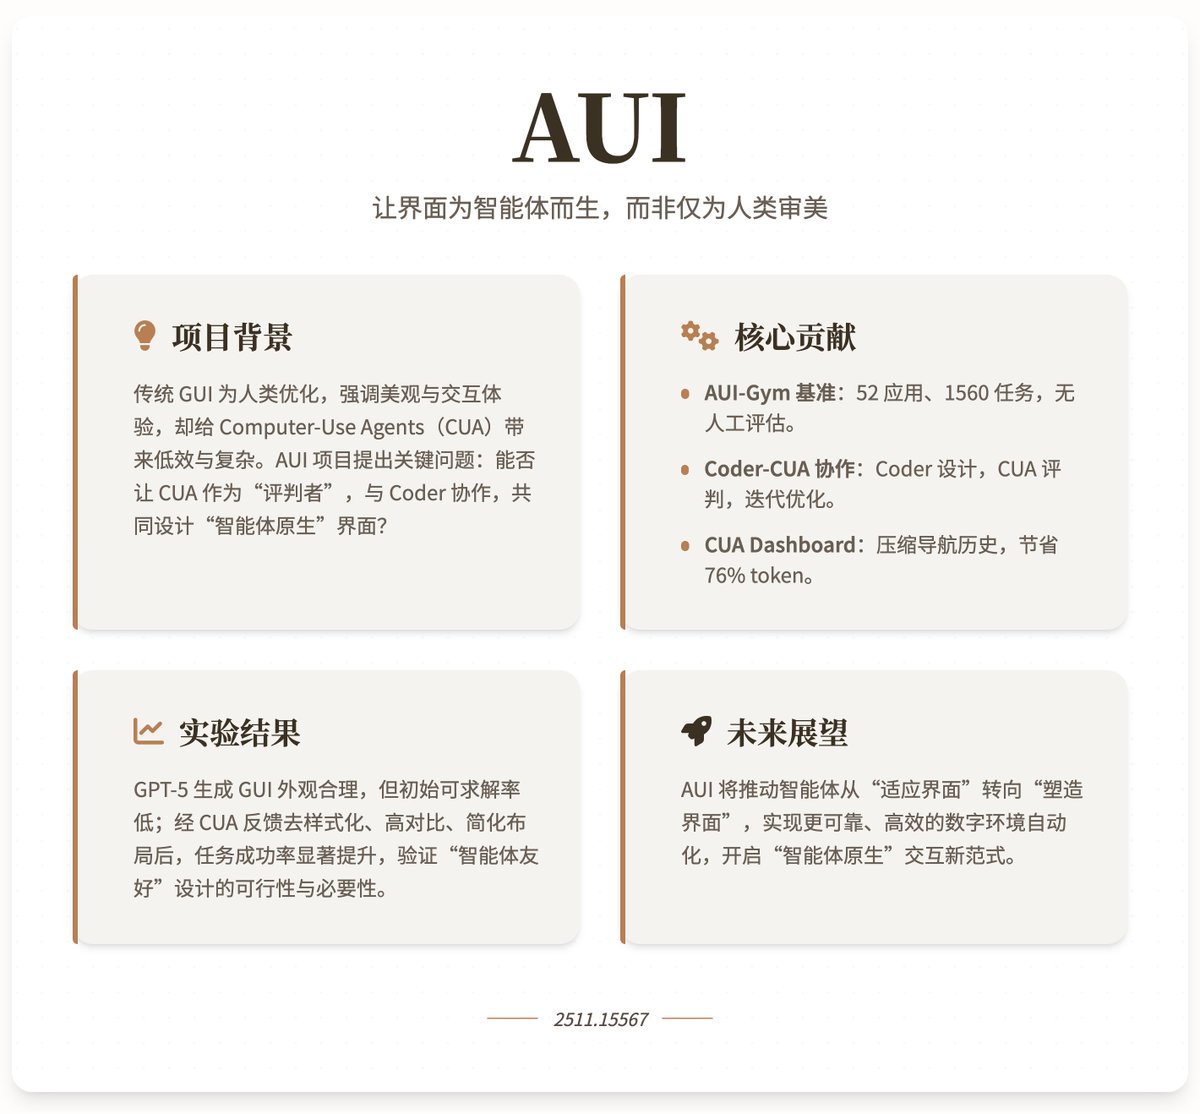
Research and market dynamics surrounding Google Gemini 3.0 Pro and Agent-native UI (AUI): - The AUI (Agent-native UI) research introduces the Coder-CUA collaboration framework and AUI-Gym benchmark, which includes 52 applications, 1560 tasks, and rule-based validators. - CUA (Computer-Use Agents) serves as evaluators to test GUI solvability and provide navigation trajectory feedback. The CUA Dashboard condenses multi-step interactions into a single interpretable image to reduce visual tokens. - AUI results indicate that simple, function-oriented interfaces are better suited for agent navigation, with significant increases in success rates after iterations. - Gemini 3.0 Pro scored 130 in offline IQ tests and 142 in Mensa tests, reported as one of the highest scores among historical LLMs. - Market trends show movements in computing power procurement: Anthropic and Google have reached large-scale TPU procurement agreements, while Meta is also negotiating substantial TPU purchases with Google. - Various LLMs have distinct advantages across different tasks, with collaboration and generation towards cooperation being the focus of the next phase.
Key insights
AUI: GUI Benchmark and Collaboration Framework Designed for Agents
The AUI project, a collaboration between Oxford, the National University of Singapore, and Microsoft, introduces the AUI-Gym benchmark (52 applications, 1560 tasks) and the Coder-CUA collaboration framework: Coder generates the initial GUI, CUA performs task validation and returns failure and navigation feedback. This feedback loop helps Coder make targeted improvements to the interface, with results indicating that simple, de-stylized interfaces enhance agent navigation success rates.
CUA Dashboard: Compressing and Visualizing Agent Interaction Trajectories
The CUA Dashboard proposed by AUI condenses multi-step navigation history into a 1920×1080 image, reducing visual tokens by an average of 76.2% through adaptive cropping and visual cues, making agent feedback easier for Coder to interpret and use for interface optimization.
IQ Test Scores of Gemini 3.0 Pro
Reports indicate that Gemini 3.0 Pro scored 130 in offline IQ tests (with entirely new confidential questions) and 142 in Mensa tests, becoming one of the highest-scoring LLMs in offline assessments; researchers also note that IQ is just one metric among many for multidimensional evaluation.
Market Dynamics and Computing Power Procurement
Following the large-scale TPU procurement agreement between Anthropic and Google, Meta is also engaging in negotiations for billions of dollars in TPU purchases with Google, indicating that major players are intensifying competition and investment in TPU and computing resources in the short term.
LLM Performance Comparison and Application Orientation
Various tests show that different LLMs have their strengths—there are differences in performance in insight and reasoning scenarios. Research and industry perspectives suggest that the next phase should shift from automatic generation to 'collaborative cooperation,' meaning the joint creation and iteration of AI and humans in production scenarios.