
Google DeepMind demonstrates Dream-RSI recursive self-improvement
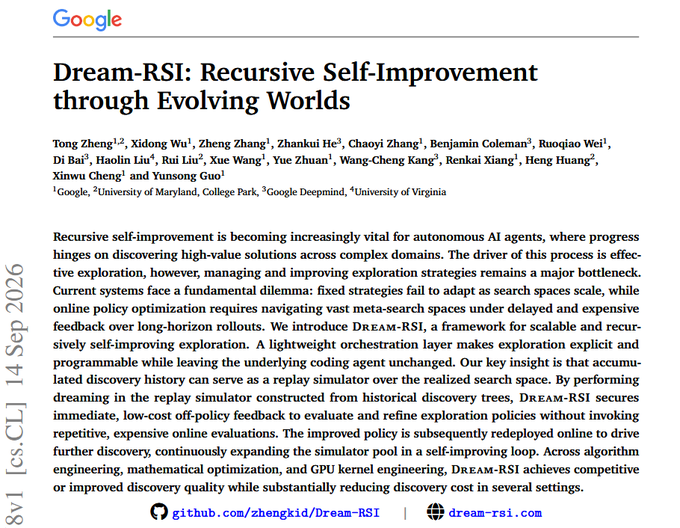
Google DeepMind showed Dream-RSI, a recursive self-improvement loop that replays past discoveries to test thousands of exploration strategies at low cost. It improved agent call efficiency by up to 162x in algorithm design, math optimization, and GPU kernel engineering while maintaining or improving result quality.
Key insights
Dream-RSI replays past discoveries to cheaply test new strategies
Dream-RSI replays past discovery processes, allowing the system to test thousands of exploration strategies at low cost. The best strategies are then used in the next round of real discovery. This creates a closed loop where the system improves its own exploration methodology.
Up to 162x reduction in agent calls while maintaining quality
In algorithm design, math optimization, and GPU kernel engineering tasks, Dream-RSI maintained or improved result quality while reducing agent calls by up to 162x. This demonstrates significant efficiency gains in the self-improvement loop.