
Google launches Android Bench 2.0 for coding agents
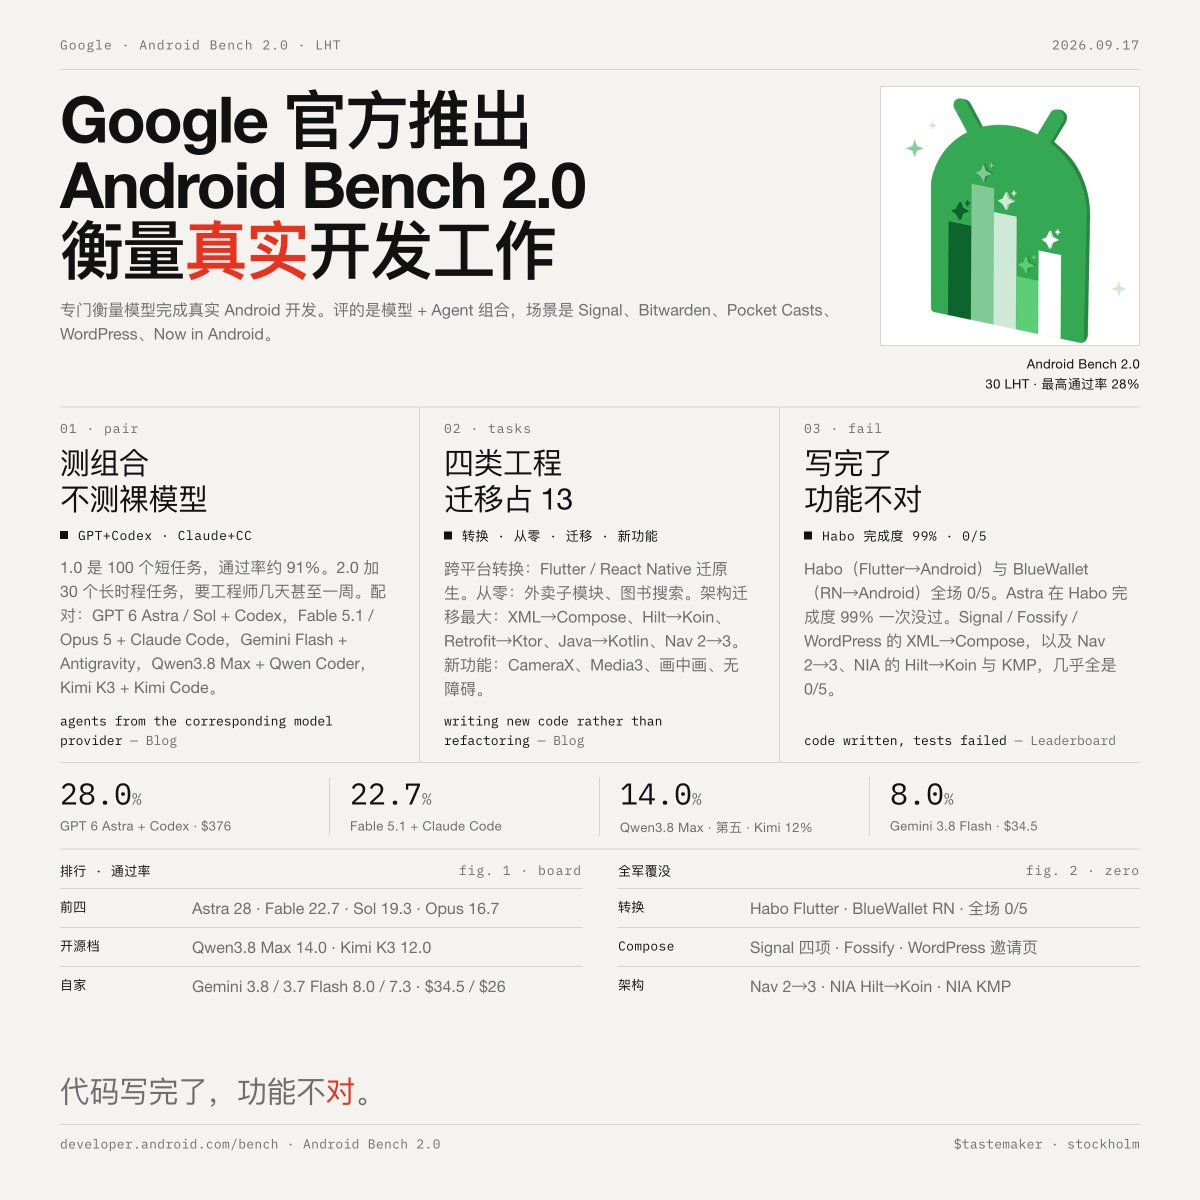
Google released Android Bench 2.0, a benchmark evaluating model+agent combinations on real Android development tasks. It includes 30 tasks across app conversion, build from scratch, architecture migration, and new feature development. Top scores reached 28%, with GPT-6 Astra+Codex leading, and many tasks had zero passes.
Key insights
Android Bench 2.0 tests real-world Android development with production apps
The benchmark uses tasks derived from Google Android best practices documents, applied to real production apps like Signal, Bitwarden, Pocket Casts, WordPress, and Now in Android. It evaluates model+agent combinations such as GPT+Codex, Claude+Claude Code, Gemini+Antigravity, Kimi K3, and Qwen 3.8 Max.
Top scores are low: 28% pass rate, many tasks have zero passes
GPT-6 Astra+Codex and Claude Fable 5.1+Claude Code took the top two spots. Qwen3.8 Max+Qwen Coder and Kimi K3+Kimi Code followed. Google's own Gemini models placed lower but with cost advantages. Several tasks had 0/5 passes, including all Flutter→Android and React Native→Android conversions, and most XML→Compose migrations.
Architecture migration tasks are the largest category and most challenging
13 of the 30 tasks involve architecture migrations: XML View to Compose, Hilt to Koin, Retrofit to Ktor, Java to Kotlin. These proved particularly difficult, with many models scoring 0/5. The results highlight that while AI can write code, understanding and refactoring existing architectures remains a significant challenge.