
Google's Android Bench 2.0 Shows AI Agents Fail at Real-World Android Tasks
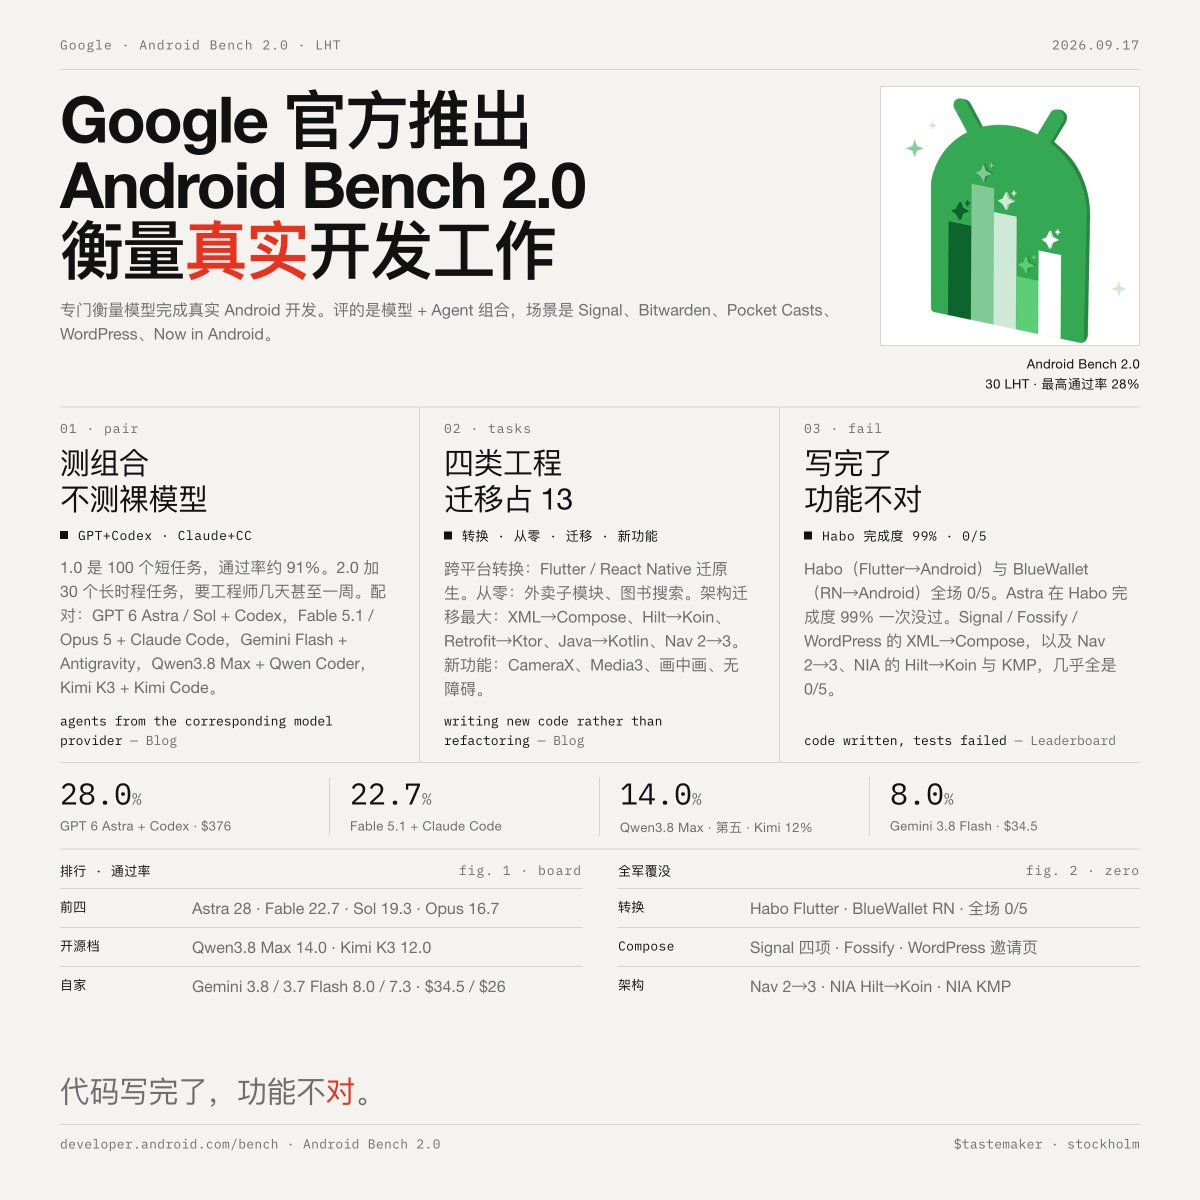
Google released Android Bench 2.0, a benchmark for measuring AI models' ability to perform real Android development tasks using production apps like Signal and Bitwarden. The best model-agent combination achieved only a 28% pass rate, with GPT-6 Astra + Codex and Claude Fable 5.1 + Claude Code leading. All models failed cross-platform conversion tasks and many XML-to-Compose migrations, scoring 0/5.