
High-Performance Retrieval and Caching System Designed for Intelligent Agents
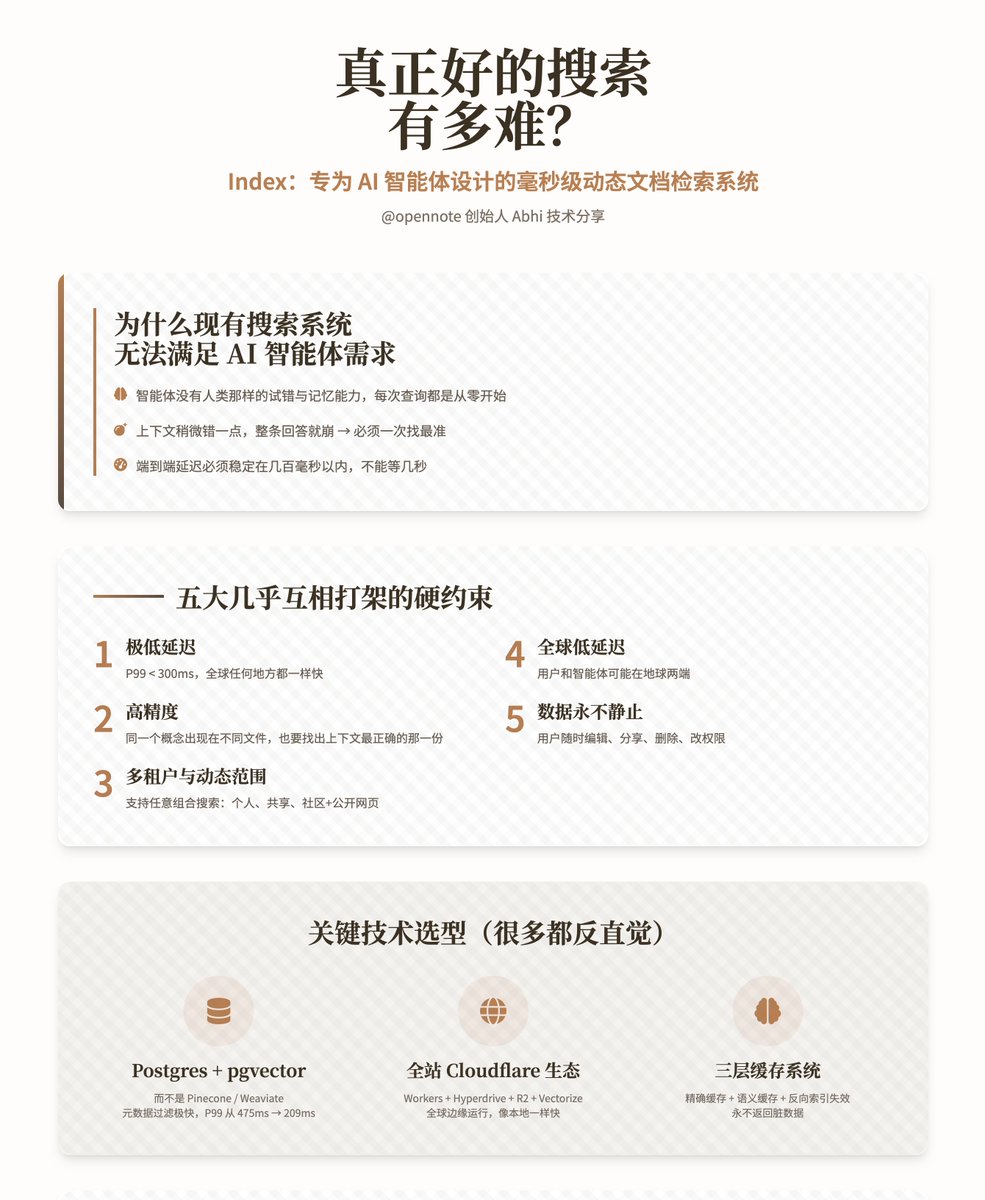
Progress on several retrieval and caching systems aimed at intelligent agents: - Opennote's Index is a millisecond-level dynamic document retrieval system designed for AI agents, targeting P99 < 300ms. - Index uses Postgres (pgvector + pg_trgm + tsvector) instead of mainstream vector libraries to filter candidates in advance using metadata, reducing P99 from 475ms to 209ms in practical tests. - Index operates at the global edge (Cloudflare Workers + Hyperdrive, etc.), employing a stateless ingestion pipeline and change hashing to recompute only the changed chunks and trigger cache invalidation. - A three-layer caching mechanism: precise caching, semantic caching, and reverse index invalidation, achieves high hit rates while ensuring data timeliness. - Memori is an open-source SQL-native memory engine that supports single-line activation, intelligent entity extraction, multiple memory modes, and periodic awareness for intelligent agent background refinement. - Redis for AI provides a vector library, long-term/short-term memory, semantic caching, and semantic routing, claiming advantages in speed, cost, and real-time performance, and integrates with ML feature storage. - Acontext offers a context data platform for agents: task observation, self-learning mechanisms, and SOP extraction, facilitating long-term stable improvements in agent behavior.
Key insights
Index: Retrieval Engine Optimized for Intelligent Agents
The Index, introduced by the founder of Opennote, is specifically designed for ultra-low latency and high-precision retrieval for AI agents in personal knowledge bases. It utilizes Postgres with pgvector/pg_trgm/tsvector for strong filtering within the database, allowing for parallel full-text and vector searches. The Index operates on the Cloudflare edge, employing a stateless ingestion process and change hashing to recompute embeddings only for changed chunks, achieving the target of P99 < 300ms with a measured P99 of 209ms.
Index's Three-Layer Caching Strategy Ensures Timeliness and High Hit Rates
Index employs a three-layer mechanism consisting of precise caching (for identical query + filtering hits), semantic caching (based on query embedding), and reverse index invalidation (which records related caches for chunks and actively invalidates them upon document changes). This approach reduces database pressure and avoids returning outdated content, making it suitable for dynamic editing and multi-tenant filtering scenarios.
Memori: One-Line Integration of SQL Native Memory Engine
Memori offers an open-source SQL-native memory engine that allows users to store memory in a controllable SQL database through memori.enable(). It automatically extracts entities and supports various memory modes such as awareness, automatic, and combined. The architecture uses interceptors to inject relevant memories during pre-calls and extract new information during post-calls, with periodic optimization run by awareness agents in the background.
Redis for AI Emphasizes End-to-End Performance with Semantic Caching
Redis has launched Redis for AI, integrating high-speed vector retrieval, long-term/short-term memory, semantic caching, and semantic routing. It is compatible with ecosystems like LangChain, making it suitable for real-time, multi-agent, and personalized scenarios. Additionally, Redis has partnered with DeepLearningAI to offer the course 'Semantic Caching for AI Agents.'
Acontext: Context Platform from Task Observation to SOP Extraction
Acontext centralizes agent interactions, task execution, and outputs, with a background task observer extracting SOPs to serve as a skill library for subsequent retrieval and reuse. It supports multimodal conversations and integration with multiple providers such as OpenAI and Anthropic, aiming to enhance the long-term reliability and reusability of agents.