
howie_serious Explains Why Nano Banana Pro Improves Text Rendering via Token-based Multimodal Models
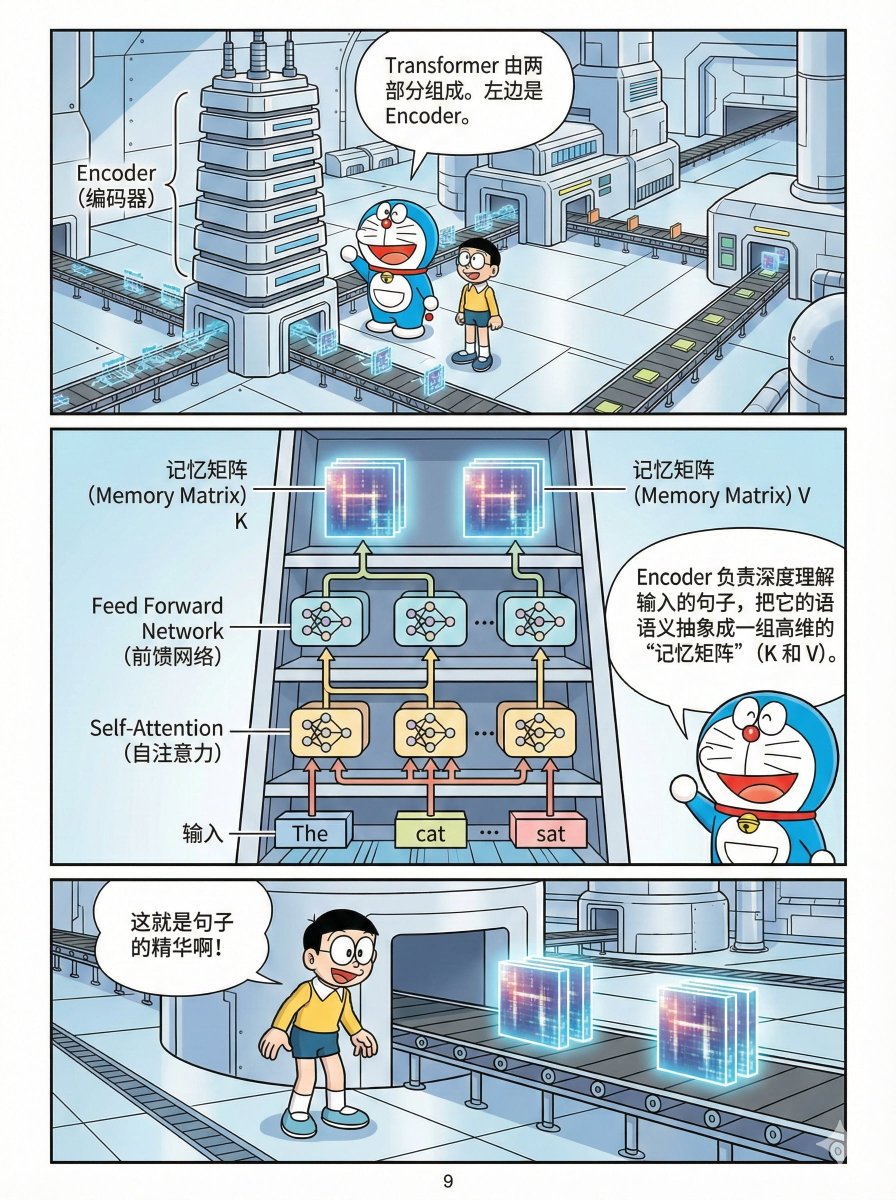
The post contrasts diffusion image models (pixel-level denoising) with native token-based multimodal transformers like Nano Banana Pro and GPT-Image-1. Diffusion models treat characters as pixels and produce messy Chinese text; token-in/token-out multimodal transformers represent text and images as unified vectors, enabling them to 'write' characters with writing logic and thus achieve far lower character spelling error rates in generated images.