
Hugging Face tokenizers v1: 3-30x faster encoding with SIMD and caching
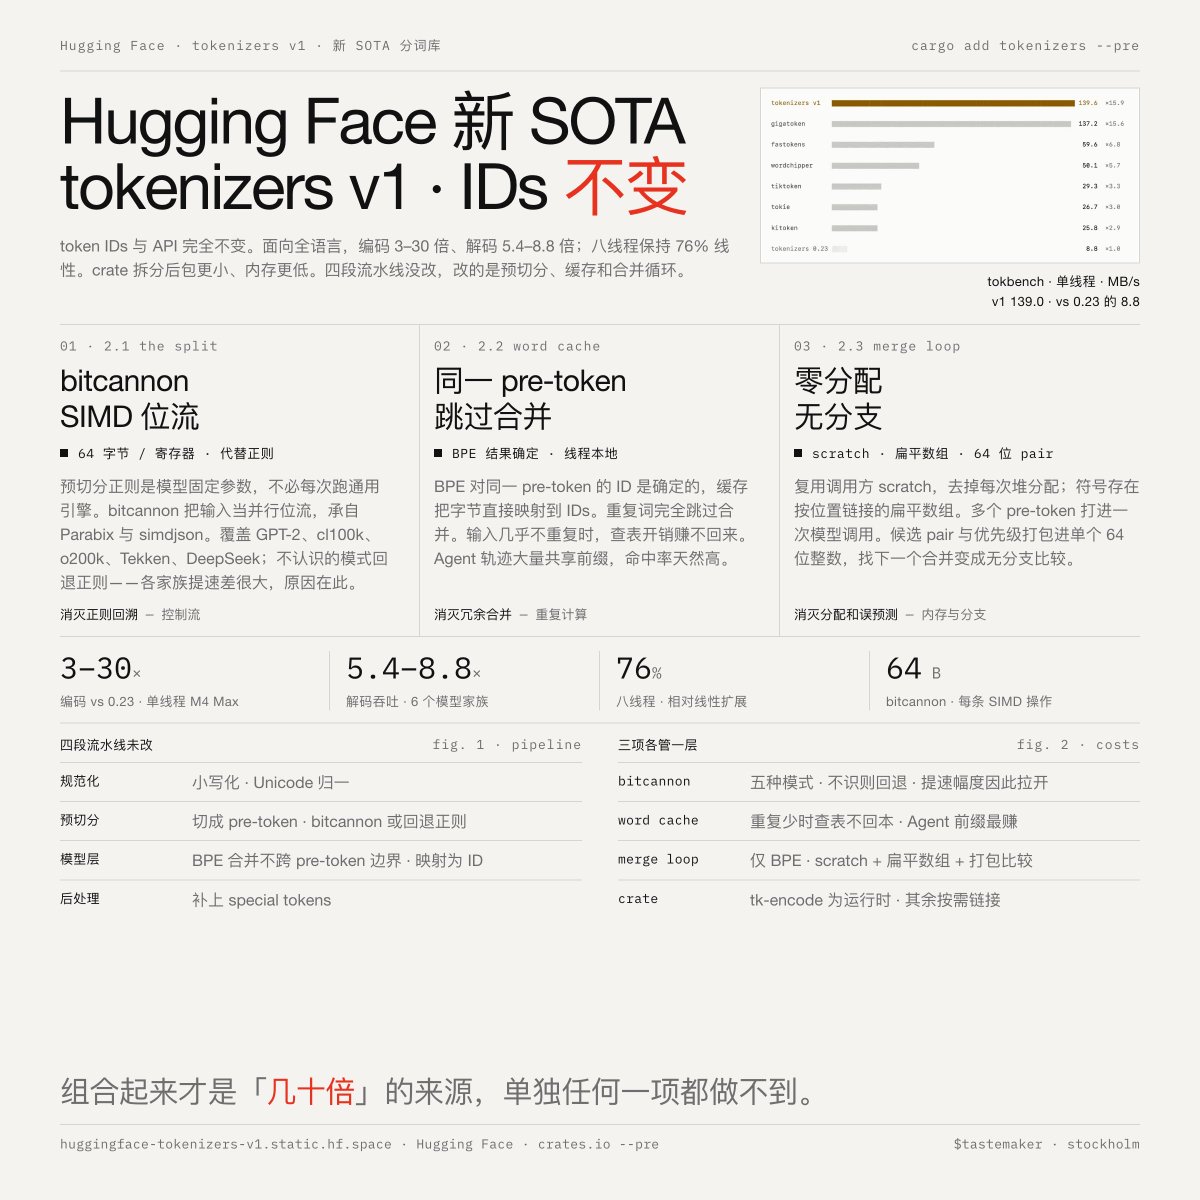
Hugging Face released tokenizers v1, a new SOTA tokenization library achieving 3-30x encoding and 5.4-8.8x decoding speed improvements across all languages via three core technologies: bitcannon SIMD-based pre-tokenization replacing regex, a word cache for deterministic BPE results, and a zero-allocation merge loop. The API and token IDs remain unchanged.