
HunyuanOCR Open Source and OCR Comparison Platform
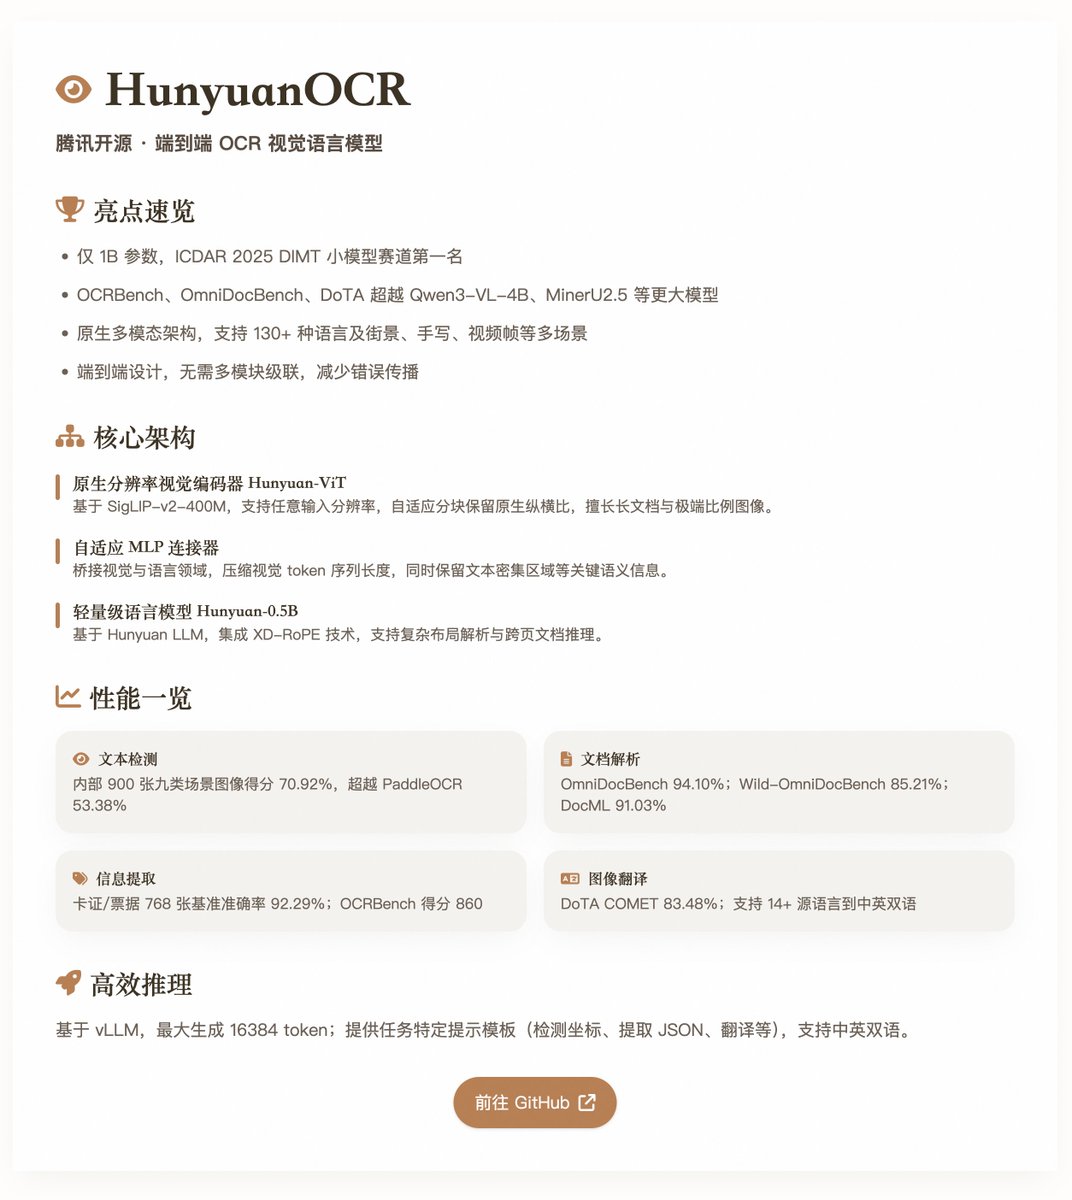
Tencent has open-sourced HunyuanOCR, an end-to-end OCR visual language model with approximately 1 billion parameters, achieving leading results across multiple benchmarks. The model consists of a native resolution visual encoder Hunyuan-ViT (about 0.4B), an adaptive MLP connector, and a lightweight language model Hunyuan-0.5B. The end-to-end design avoids module cascading and is suitable for text detection, document parsing, information extraction, visual question answering, and image translation scenarios. Training data and processes include pre-training with a total of 454 billion tokens and around 200 million high-quality samples, followed by fine-tuning using the online reinforcement learning algorithm GRPO with task-specific rewards. HunyuanOCR ranked first in the ICDAR 2025 DIMT (small model track) and surpassed larger models in benchmarks like OCRBench, OmniDocBench, and DoTA, providing specific scoring and accuracy metrics. The open-source model runs parallel to the OCR Arena platform, which offers real document comparison testing and visualization tools, supporting competition with multiple mainstream models.
Key insights
HunyuanOCR Achieves Leading Performance with 1B Parameters in End-to-End OCR
Tencent has released HunyuanOCR, which features approximately 1 billion parameters and employs an end-to-end visual language model design to avoid the issues associated with traditional multi-module cascades. The core architecture includes Hunyuan-ViT (about 0.4B, native resolution encoding), an adaptive MLP connector, and the lightweight Hunyuan-0.5B language module, supporting unified modeling for multiple tasks. It can complete processes such as detection, recognition, parsing, and translation through natural language instructions.
Training and Optimization Strategy: Large-Scale Token Pre-training and GRPO Reinforcement Fine-tuning
The model's pre-training is conducted in four steps, totaling approximately 454 billion tokens, with around 200 million training samples covering multiple scenarios and languages. The post-training phase utilizes the online reinforcement learning algorithm GRPO, combined with task-specific rewards (rule-based and LLM-as-a-judge) to enhance robustness in complex scenarios. This data and optimization pipeline is aimed at improving long-context, cross-page reasoning, and actual document parsing capabilities.
Benchmark Results and Real-World Performance Surpassing Larger Models
HunyuanOCR achieved first place in the ICDAR 2025 DIMT (small model track) and demonstrated excellent performance in internal document parsing, text detection, and information extraction across multiple benchmarks such as OmniDocBench, OCRBench, DoTA, and DocML, listing specific scores and accuracy rates. It has outperformed larger models like Qwen3-VL-4B and MinerU2.5 in real-world scenario benchmarks.
OCR Arena Provides Real Document Comparison and Visualization Testing Platform
OCR Arena is an interactive playground designed specifically for real documents, allowing real-time document uploads and generating visual difference maps, comparison tables for completeness, and extraction accuracy. It is suitable for testing structured documents, handwriting, and scanned images in real-world scenarios. The platform can compare with over ten models, including Gemini 3, DeepSeek-OCR, and GPT-5, and provides a transparent leaderboard based on user testing.