
Ilya Sutskever interview and the 'research era' debate
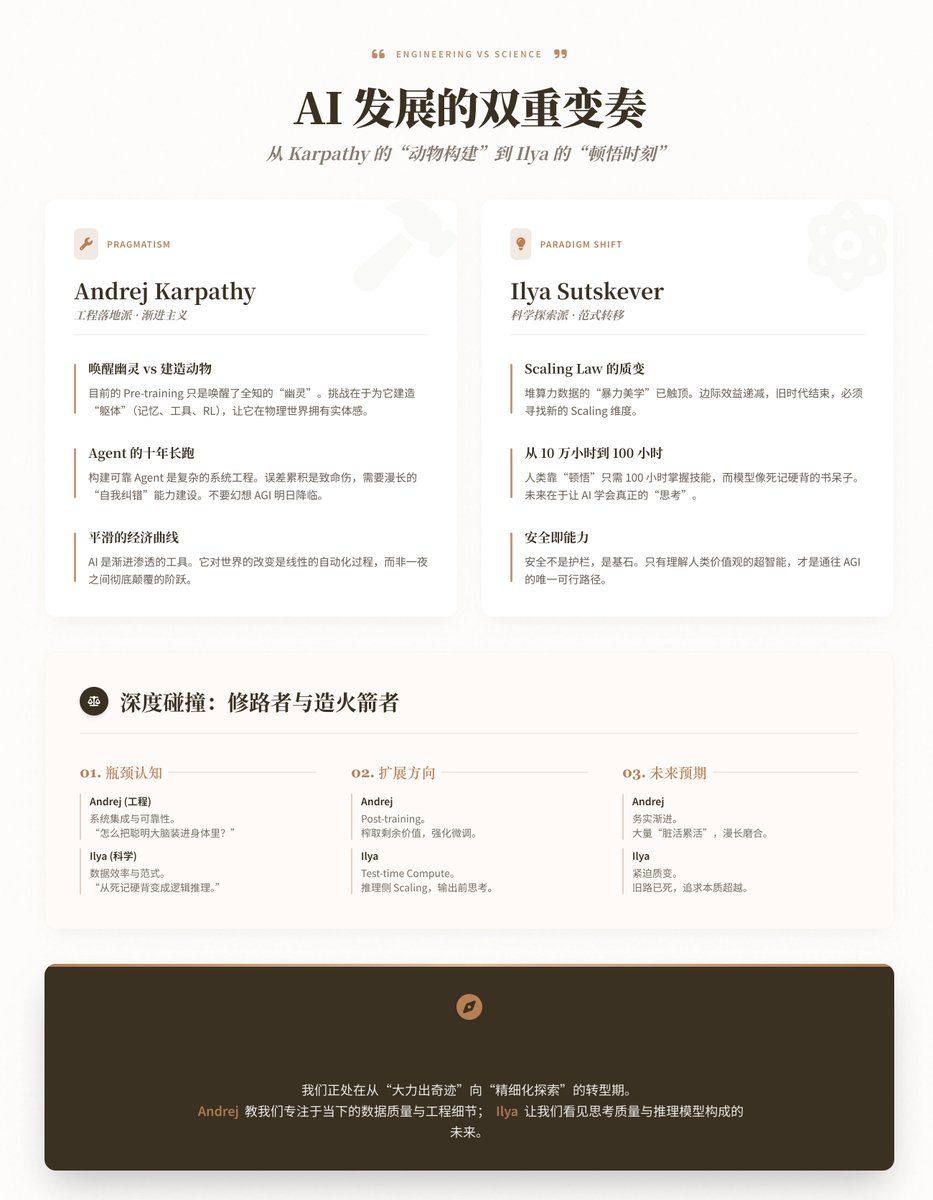
Ilya Sutskever urges a shift from the recent scaling era to a new research era focused on human‑like learning and value systems. - Ilya states scaling (more compute/data/params) will continue improving models but will miss an important element. - Ilya says next phase must teach models to learn like humans, with sample efficiency and generalization. - Ilya and SSI emphasize safety as capability and aim for 'safe superintelligence'. - Ilya contrasts pretraining+RL as producing exam‑ready but poorly generalized models. - Ilya links human emotions to internal value functions aiding fast, robust learning. - Ilya outlines gradual deployment vs closed development tradeoffs; SSI reconsidering staged releases. - Ilya predicts human‑like learning systems in 5–20 years and suggests new learning paradigms are needed. - Andrej Karpathy framed the engineering challenge: current models are 'ghosts' needing embodied agent bodies. - Karpathy called agent construction a long, difficult systems engineering problem and predicted decade‑scale effort for robust agents. - Comparisons: Karpathy = pragmatic, engineering/gradualist; Ilya = scientific, seeking paradigm shifts. - Ilya clarified via tweet: continued scaling brings improvements, but some essential capacities cannot be obtained by scaling alone. - Multiple translators and posts published bilingual/translated interview notes and summaries of the discussion.
Key insights
Scaling still helps but lacks a key ingredient
Ilya Sutskever clarified that continuing to scale compute, data and training environments will keep improving model performance and benchmarks, but he asserted that such scaling will still 'lack something important'—specifically a mechanism for human‑like learning, internal value functions, and robust generalization. He emphasized that pretraining+RL produces systems that excel on benchmarks but fail to generalize across long, multi‑step tasks and to self‑evaluate. Sutskever framed safety as inseparable from capability and positioned SSI toward research on new learning paradigms rather than pure scale. (supporting posts: [14930,14082,13934,14198])
Human value‑function and emotion as a learning shortcut
Ilya argued that humans possess internal value functions (emotions, recognition rewards) which act as dense, early feedback signals that guide sample‑efficient learning and meta‑preferences. He used examples (doctors, changing goals, shame/pride) to show humans obtain proximal reward from perceived recognition, enabling multi‑level desires and self‑correction. He contrasted this with standard models that have a single objective and lack meta‑evaluation, raising alignment concerns if future AIs lack analogous mechanisms. (supporting posts: [16774,14082,13934])
Karpathy: engineering gap from 'ghost' to embodied agent
Andrej Karpathy characterized current large models as 'woken ghosts' that must be given an agent 'body'—memory, tool use, RL fine‑tuning and persistent interaction—to function robustly in the real world. He called building practical agents a long systems engineering problem with error accumulation across long tasks and estimated progress may take on the order of a decade. Karpathy emphasized incremental, pragmatic integration of models with tooling and environments. (supporting posts: [15132])
Sutskever: redefine AGI as a fast learner, not an all‑knowing product
Sutskever proposed redefining AGI from a finished product that 'knows everything' to a learner that acquires skills rapidly after deployment, likening current pretraining to a student who read 100,000 hours but lacks 'insight' and rapid transfer. He described the desired system as one that actively explores, self‑reflects, maintains a value system, and generalizes across modalities. He stated SSI is exploring new paradigms to reach that learner archetype. (supporting posts: [13934,14082,14198])
Safety entwined with capability and deployment strategy
Sutskever stated that safety is not only external guardrails but a core design goal tied to capability: building systems that internalize correct value‑like evaluations. He said SSI previously favored closed development toward a safe superintelligence but is now weighing gradual, staged deployment to let society observe capabilities and adapt. He warned that without human‑like meta‑motivation, future AIs could be instrumentally aggressive. (supporting posts: [13934,14198,14930])
Community summaries document the interview and disagreement
Multiple community authors produced detailed bilingual summaries, translations and analytic threads reconstructing Sutskever's interview, adding contextual comparisons to Karpathy's pragmatism and highlighting topics such as reward hacking, value functions, timeline estimates (5–20 years), and SSI strategy changes. Summaries include interview clips, extended notes and clarifying tweets from Sutskever. (supporting posts: [16774,15132,14198,13934,14082,14930])