
Inference Providers Trade Speed Against Cost on Shared GPU Capacity
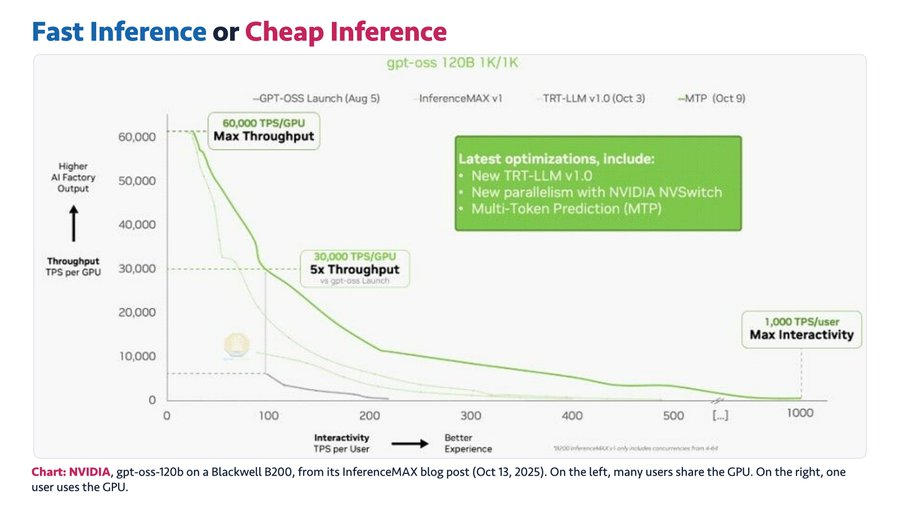
Inference providers face a trade-off between speed and cost because both depend on how users are allocated across GPUs. Groq and Cerebras prioritize speed, while CoreWeave, Novita and Crusoe lean toward lower prices. A single Blackwell GPU serving one user delivers about 1,000 tokens per second, while sharing it across users raises total throughput to 60,000 tokens per second but cuts each user to roughly 20–100 tokens per second.
Event version 1.
Key insights
Speed requires idle capacity
Pursuing speed means reducing the number of users per GPU, which leaves more idle compute and raises token costs.
Providers split by priority
Groq and Cerebras chose speed, while CoreWeave, Novita and Crusoe lean toward lower prices.
Single-user throughput is limited
A Blackwell GPU serving one user provides about 1,000 tokens per second, and the whole card produces only that same 1,000 tokens per second.
Sharing raises total but cuts per-user speed
With multiple users sharing a GPU, total throughput can rise to 60,000 tokens per second, but each user receives only about 20–100 tokens per second.
Trade-off is resource allocation
Speed and cost are fundamentally a question of resource allocation on the same GPU.