
Jev AI agent API redesign and early access
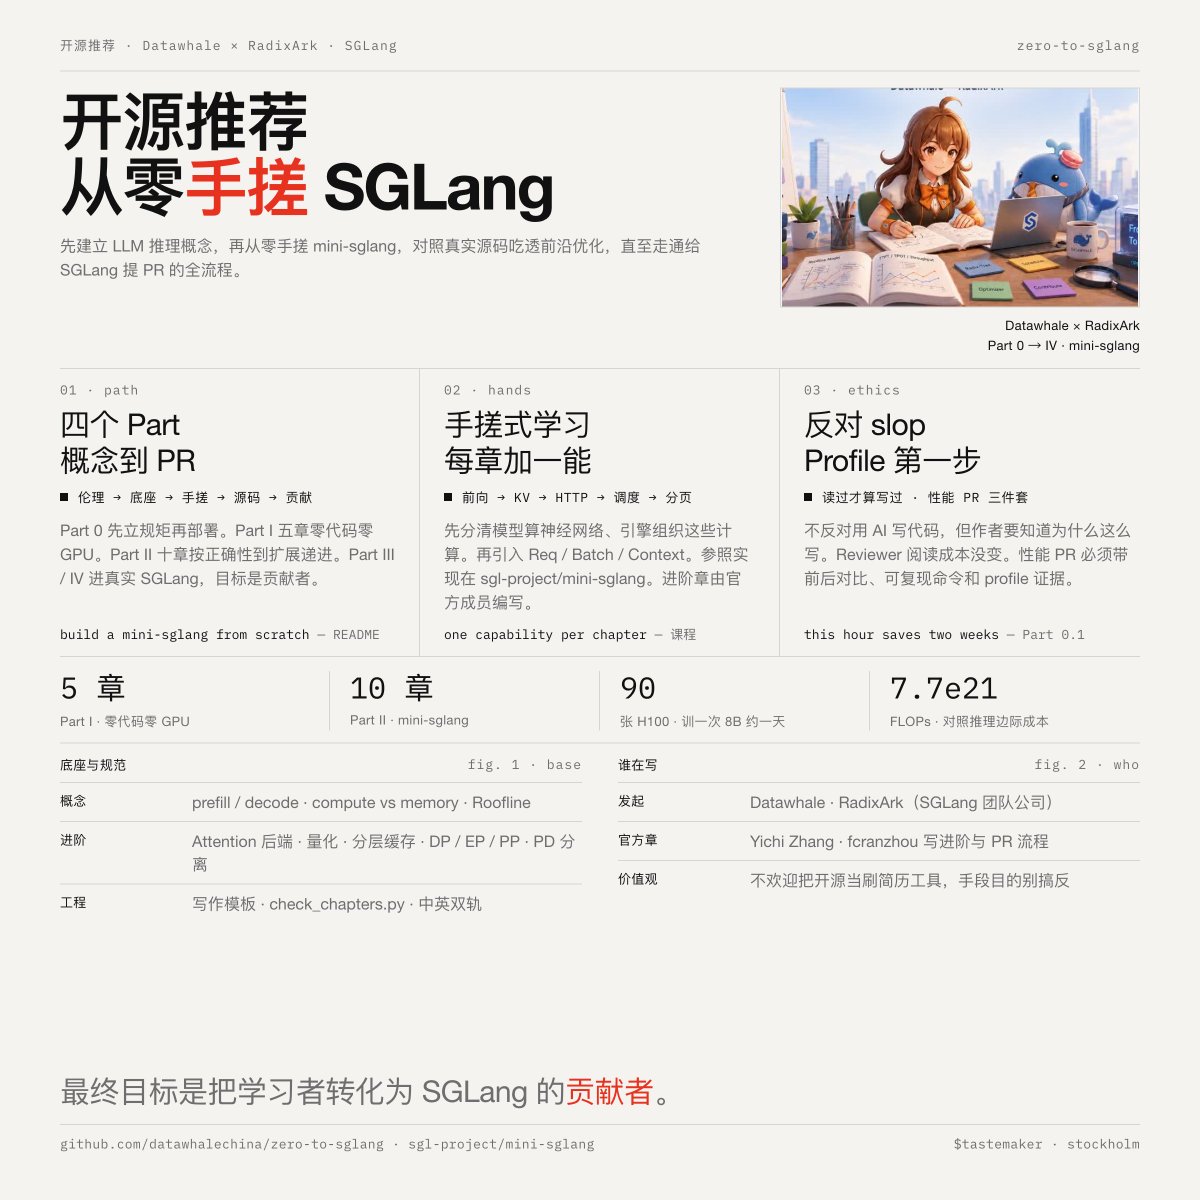
TypeSafe AI launched Jev, a 'System One' model for software decision-making, offering 70–500ms latency at $0.042 per million tokens. It outputs calibrated probabilities instead of text, designed for classification, routing, and extraction. Separately, Datawhale and RadixArk released an open-source course teaching SGLang inference engine development from scratch.
Key insights
Jev: new model category for fast, structured decisions
Jev abandons text generation entirely, focusing on producing type-safe structured outputs with calibrated confidence scores from unstructured data. Response latency is 70–500 ms, compared to 3–329 seconds for large frontier models. Input token price is $0.042 per million tokens (output free). TypeSafe claims 20–200x speedup and 40–400x cost reduction compared to equivalent intelligence.
RLCD training method for calibrated decisions
Founder Diogo Almeida, previously at OpenAI working on InstructGPT and RLHF, developed RLCD (Reinforcement Learning for Calibrated Decisions) to make models reliable for automation rather than human-pleasing. Jev uses parallel sampling instead of autoregressive generation, enabling all outputs to be computed simultaneously at the cost of not generating text. Type error rate is mathematically zero due to architectural constraints.
Key use cases: smart if-statements, guardrails, real-time applications
Jev is designed for embedding in code as an 'intelligent if-statement' – classification, scoring, routing, extraction. Scenarios include smart branching in customer service, large-scale data processing, real-time applications (DOOM AI at $7/hour), and as a guardrail to check LLM outputs for safety and format. It is not a replacement for conversational models.
SGLang open-source course teaches inference engine from scratch
Datawhale and RadixArk (SGLang team) released a four-part course: Part 0 (ethics, deployment), Part I (concepts like prefill/decode, compute-bound vs memory-bound, Roofline model), Part II (10 chapters hand-building mini-sglang), Part III (advanced optimizations by SGLang core developers), Part IV (profiling, PR workflow). The goal is to turn learners into SGLang contributors.
Course emphasizes coding ethics and engineering practice
The course includes a unique ethics chapter discouraging AI slop contributions and resume-driven open-source work. It requires performance PRs to include profiling evidence. The technical content is rare – most tutorials skip the 'code it yourself' step. The project provides a reference implementation in sgl-project/mini-sglang.