
LlamaIndex releases ParseBench for document parsing
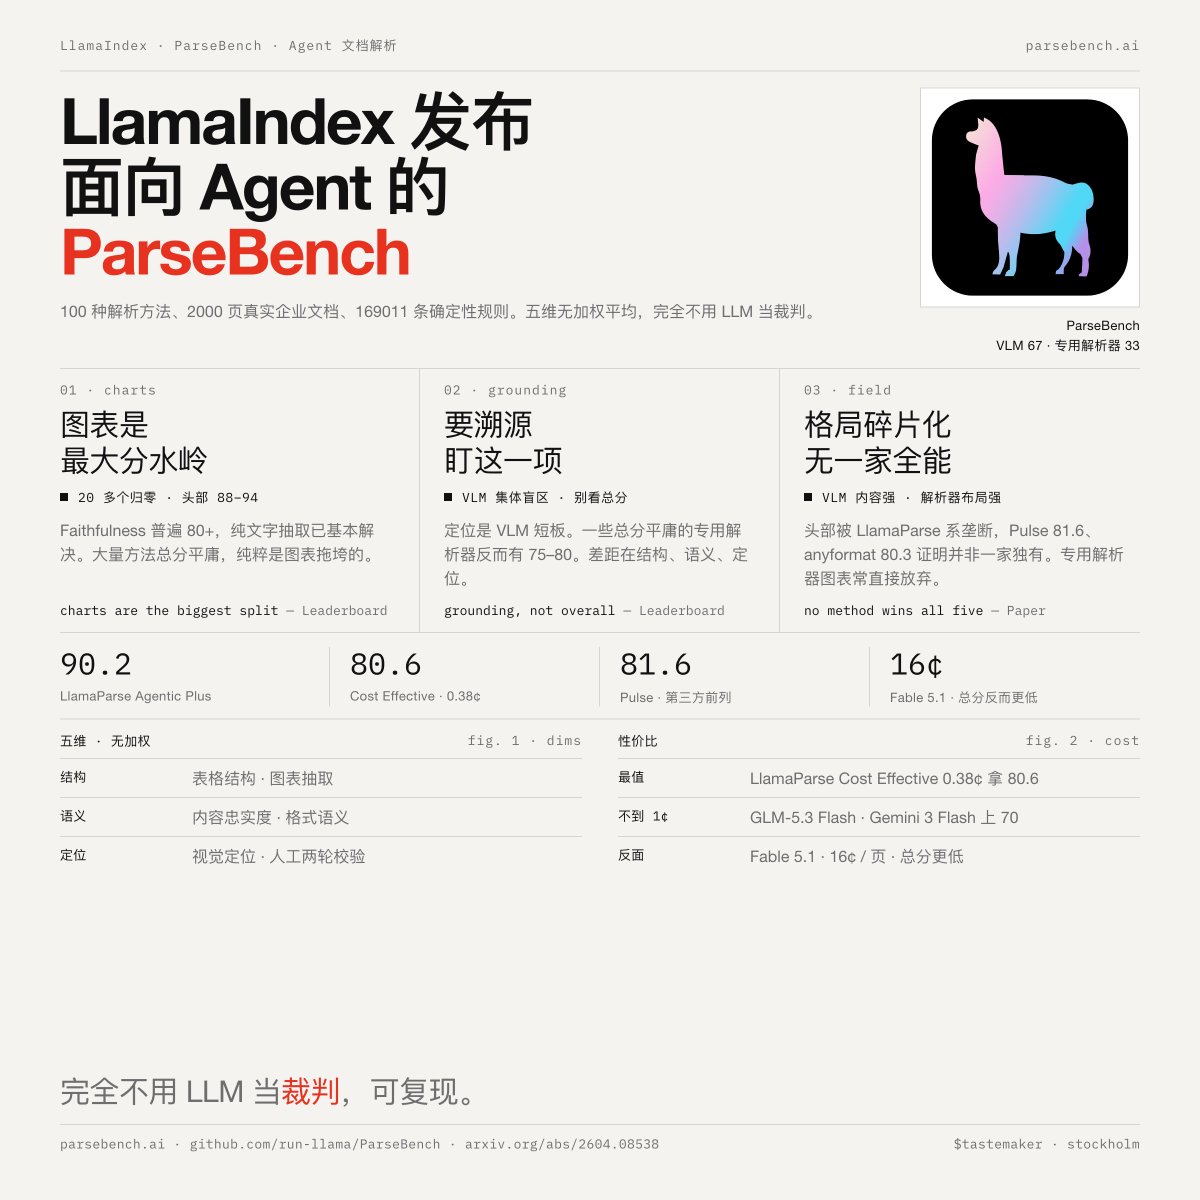
LlamaIndex released ParseBench, a benchmark for AI agent document parsing with 100 methods evaluated on 2,000 pages of real enterprise documents. LlamaParse Agentic Plus leads with 90.2, but the benchmark reveals fragmentation: no single method excels across all five dimensions.
Key insights
ParseBench evaluates 100 parsing methods on 2,000 enterprise pages
The benchmark includes 67 VLMs and 33 specialized parsers, evaluated on 2,000 pages of real enterprise documents with two rounds of human verification. It uses 169,011 deterministic rules and no LLM judge, ensuring reproducibility. Five dimensions are measured: table structure, chart extraction, content faithfulness, format semantics, and visual grounding.
Charts are the biggest differentiator; no method is universally best
Charts are the largest performance divider: over 20 methods score zero, while top methods reach 88-94. Faithfulness is generally high (80+), indicating text extraction is largely solved. Grounding is a blind spot for VLMs, while some specialized parsers score 75-80. No single method excels across all dimensions, showing a fragmented landscape.
Cost-effectiveness varies widely; LlamaParse offers best value
LlamaParse Cost Effective scores 80.6 at $0.38 per page, the best value. GLM-5.3 Flash and Gemini 3 Flash score above 70 for under $0.01 per page. In contrast, Fable 5.1 costs $0.16 per page but scores lower overall. This highlights the importance of considering cost alongside performance.