
LocalLLaMA Post Argues Frontier Model Gains Come More From Harness Systems Than Raw Problem-Solving
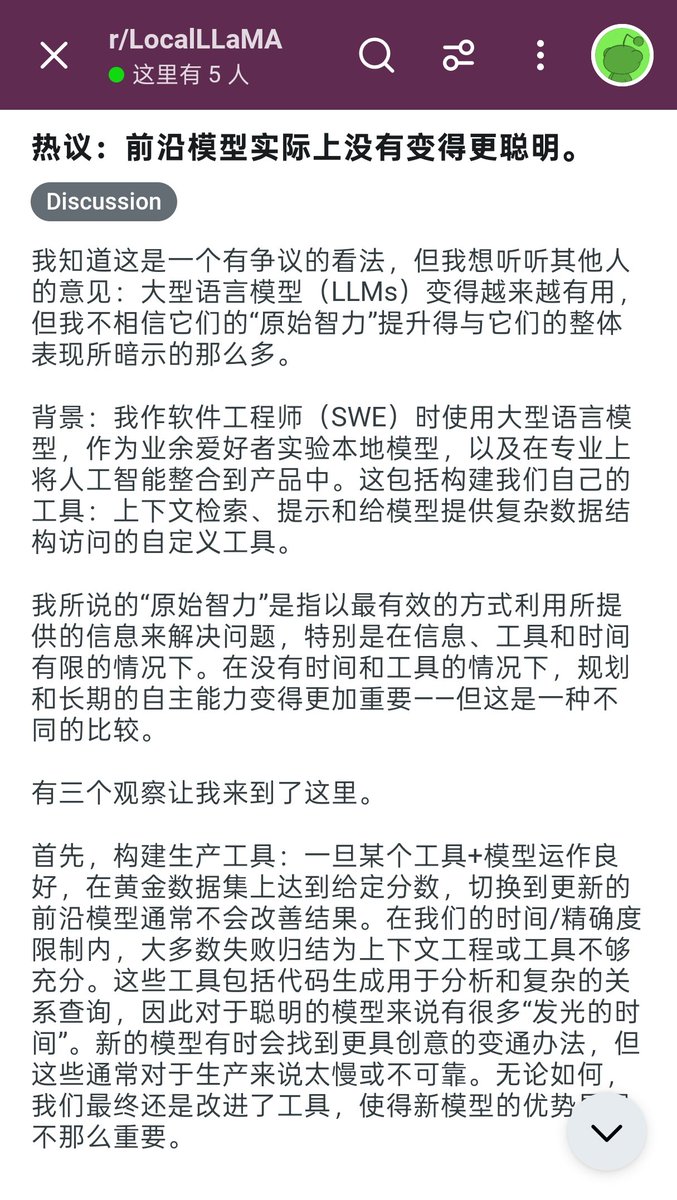
A widely discussed LocalLLaMA post argues that frontier models have become more useful through better tool calling, fewer hallucinations and longer context, but that gains in raw problem-solving ability have been smaller than overall benefits suggest. The author cites production deployments, software engineering and small local models as evidence that harness systems carry much of the improvement, while commenters dispute the claim with reports of sharp recent gains in hypothesis testing and biology error rates.
Event version 1.
Key insights
Definition of efficient problem-solving
The author defines intelligence as efficiently solving problems with limited information, tools and time. Given ample time and tools, planning and long-horizon agent capability are a separate matter that should not be compared together.
Acknowledged concrete improvements
The author acknowledges better tool calling, fewer hallucinations and longer context make models more useful, and does not claim progress has stalled or that efficient problem-solving requires very few parameters.
Three production observations
In production, swapping in newer frontier models rarely adds gains once harness and model hit targets on golden datasets, with failures mostly traced to context design or insufficient tools. Software writing benefits more from new models, but performance varies widely across harnesses. Smaller local models are already competitive, raising doubts about how many parameters efficient problem-solving needs.
Conclusion on progress sources
The author concludes that progress over the past 12 to 24 months came more from cumulative model improvements and better harness systems than from sharp or exponential jumps in problem-solving ability, and suspects media hype and doom narratives are amplified by upcoming AI listings.
Divided comment reaction
Among nearly 300 comments, some agree daily work rarely needs top models and gains come from prompting and tools. Others dispute this, citing a machine learning practitioner's reported jump in hypothesis testing, a biology user's error-rate drop from nearly unusable to usable within a year, and a former frontier evaluator's view that post-training has internalized much harness work.