
Luma Introduces MARBLE Sequence Parallelism for Packed Multimodal Masks
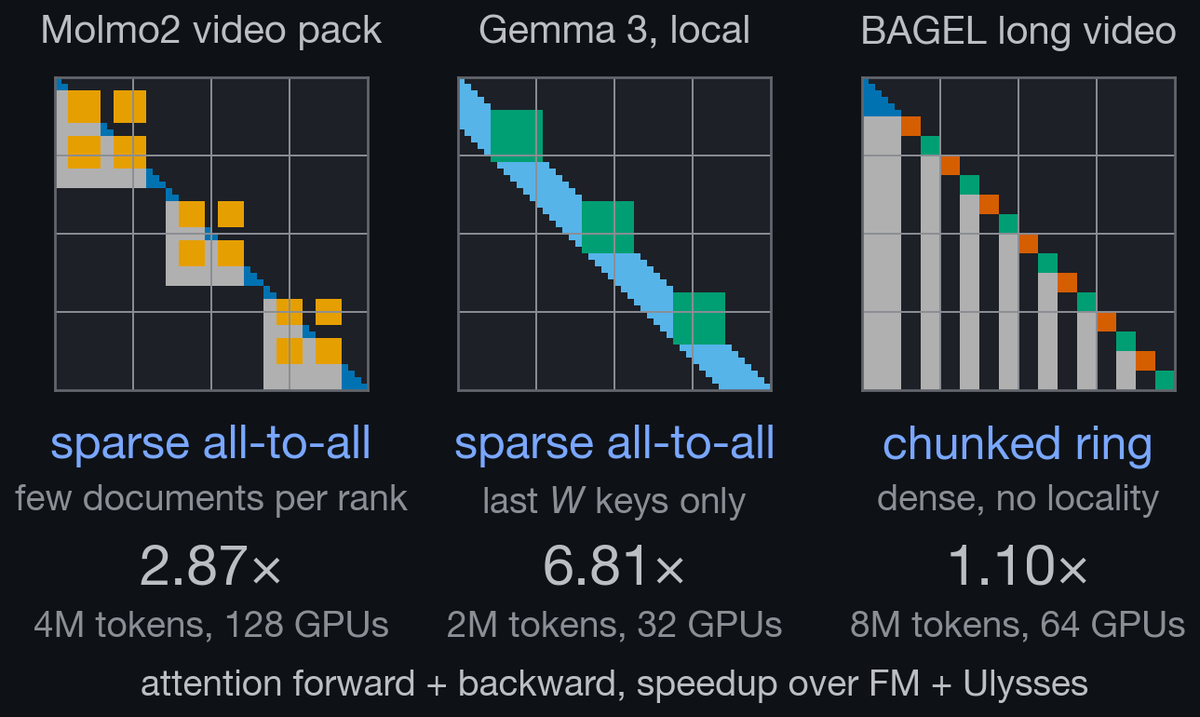
Luma introduced MARBLE, a mask-aware sequence parallelism method for packed multimodal sequences that selects ring attention, sparse all-to-all or Ulysses per layer. MARBLE matches single-GPU numerics and outperforms a FlashMask plus Ulysses hybrid in 47 of 48 cases on up to 128 H100 GPUs.
Event version 1.
Key insights
Per-layer strategy selection
MARBLE chooses ring attention, a sparse all-to-all or Ulysses for each layer based on mask patterns. The approach targets packed multimodal sequences where text is causal and images or video are usually bidirectional.
Exact numerics
MARBLE keeps the softmax state in fp32 across ring steps to avoid rounding errors. Its outputs and gradients match single-GPU results.
Balanced ring attention core
MARBLE uses a block-sparse planning strategy with per-token metadata and processing-time round-robin to balance work evenly across ranks. It also includes a chunked ring attention variant for long generations.
Benchmark results
MARBLE beats a FlashMask plus Ulysses hybrid in 47 of 48 cases. Testing ran on up to 128 H100 GPUs.