
Microsoft Research Open-Sources TokenEconomizer Plugin to Cut AI Coding Agent Costs
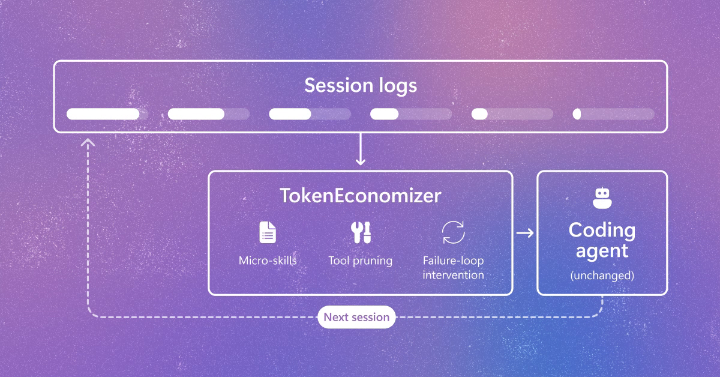
Microsoft Research, UC Berkeley and Microsoft Security released TokenEconomizer, an open-source plugin that learns from an agent's past sessions in a repository to reduce token waste without modifying the agent or its model. Across 277 SWE-Bench bug-fixing tasks, it cut mean costs by 18.4–30.9% across five agent-model combinations, with costs falling in all 30 repository-by-combination cells while Pass@1 rose in four of five.
Event version 1.
Key insights
Cost savings across benchmarks
On 277 SWE-Bench tasks across six repositories and five agent-model combinations, TokenEconomizer reduced mean cost by 18.4% to 30.9% versus a strong default reasoning setting. All 30 repository-by-combination cells became cheaper, and Pass@1 rose in four of five combinations, with Opus 4.8 down about 1.0 percentage point.
Three external control mechanisms
The plugin reads session logs and updates repository state through existing interfaces: injecting micro-skills into starting context, trimming the tool list, and intervening when an agent is stuck. Tool trimming contributed the largest savings, followed by micro-skills and stuck intervention.
Waste from starting from scratch
Profiling Claude Code on 60 SWE-Bench tasks showed about 30% of tool calls repeated earlier tasks once a repository had at least five tasks, versus about 7% across repositories. Each turn loaded 23 tool descriptions, 16 of which were never called, and failed tasks accounted for 17% of tasks but about 32% of spending.
Savings accumulate with experience
Most repositories may be more expensive for the first few tasks, with cumulative cost turning cheaper from the sixth task onward. On Web-Bench, costs fell about 16.0% to 21.2%, and cross-repository security audits fell about 6.4% to 19.6%; micro-skills are disabled when there is no repository continuity.
Prompt token reduction example
In a Django example, tool trimming reduced first-request prompt tokens from roughly 42,000–46,000 to roughly 15,000–16,000. Micro-skills are injected only after confirmation across multiple tasks with non-overlapping changed files and are permanently retired on contradictory evidence.