
MiMo V2.6 and Tokenizer Innovations: Efficient AI Models from Xiaomi and Hugging Face
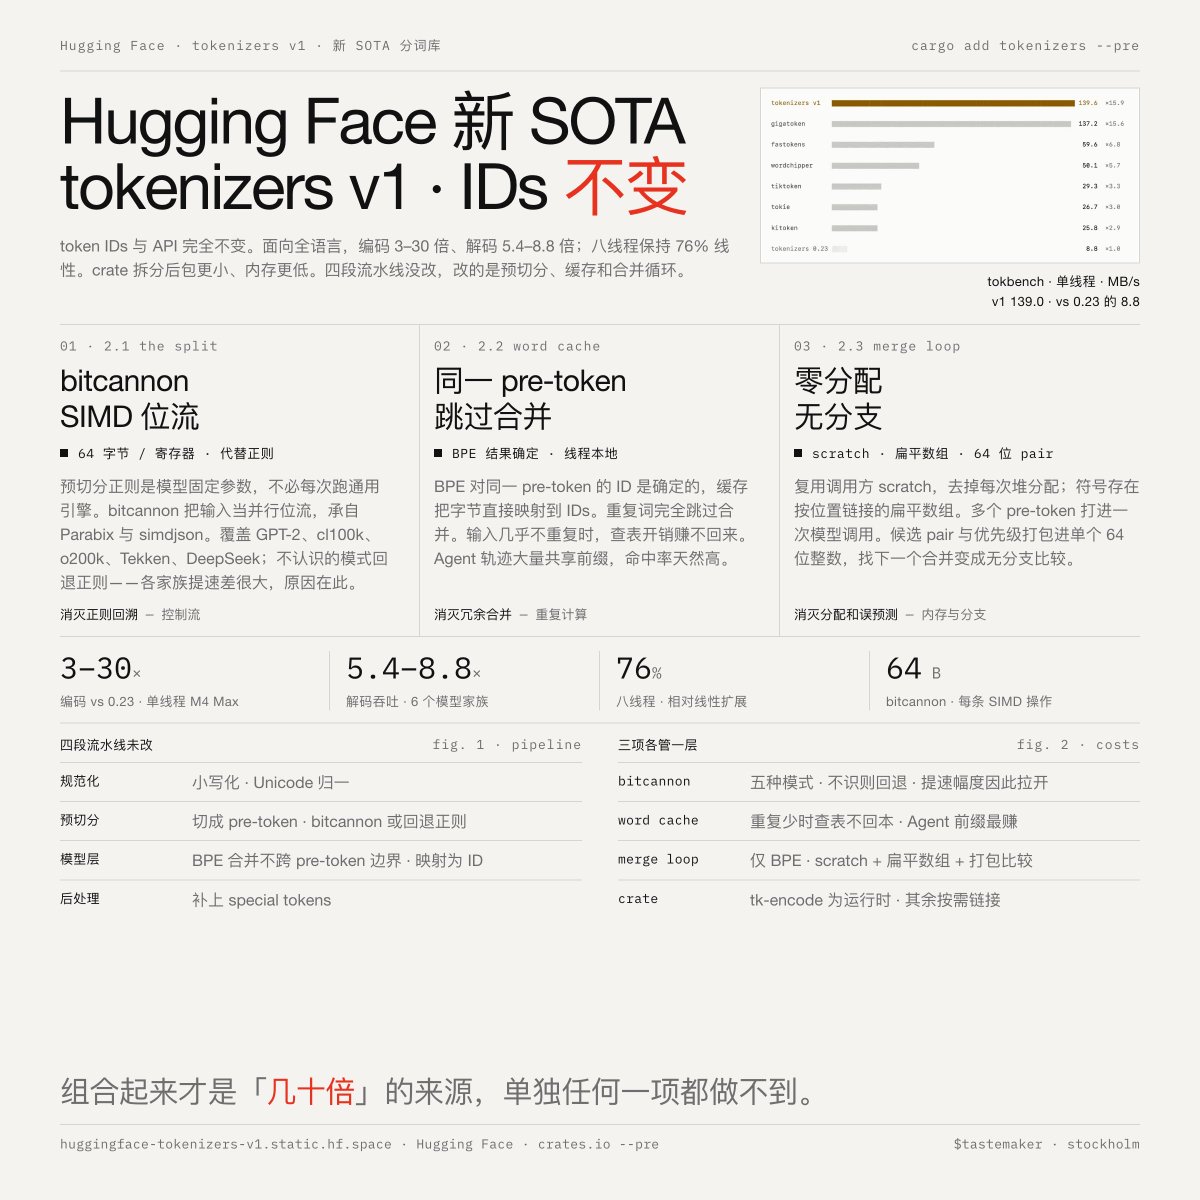
Hugging Face released tokenizers v1, a new SOTA tokenization library that speeds up encoding by 3-30x and decoding by 5.4-8.8x using SIMD bitstreams and word caching. Xiaomi open-sourced MiMo-V2.6 Pro and Flash, multimodal models that score 46 on Artificial Analysis, matching xAI Grok 4.7, with API pricing at $0.435/$0.87 per million tokens.
Key insights
Tokenizers v1: Major Speed Improvements via SIMD and Caching
Hugging Face's tokenizers v1 achieves 3-30x faster encoding and 5.4-8.8x faster decoding using three core techniques: bitcannon (SIMD bitstreams replacing regex), word cache (caching BPE results for repeated pre-tokens), and merge loop (zero-allocation, branch-free merging). It supports GPT-2, cl100k, o200k, Tekken, and DeepSeek split modes, with fallback to regex for unknown patterns.
MiMo-V2.6: Open-Source Multimodal Models with RL Training
Xiaomi released MiMo-V2.6 Pro and Flash, native multimodal models scoring 46 on Artificial Analysis, tying with xAI Grok 4.7. Pro underwent the largest RL training for an open-source model: 30 steps, 750,000 trajectories, costing $2.62 million. The MixRL strategy mixed coding, vision, and cybersecurity tasks. API pricing is $0.435/$0.87 per million tokens for Pro, and $0.14/$0.28 for Flash.
MiMo-V2.6 Open-Source Ecosystem
Xiaomi open-sourced the full RL training framework, over 7,000 RL task environments, and a distilled Qwen-9B model. Both models support 1M token context and text, image, audio, video input under MIT license. Flash is only a few points behind Pro on agent benchmarks, offering better cost-efficiency for batch tasks like code review and document processing.