
NVIDIA: Attention Mechanism Architecture Sets Long-Context Model Serving Speed Ceiling
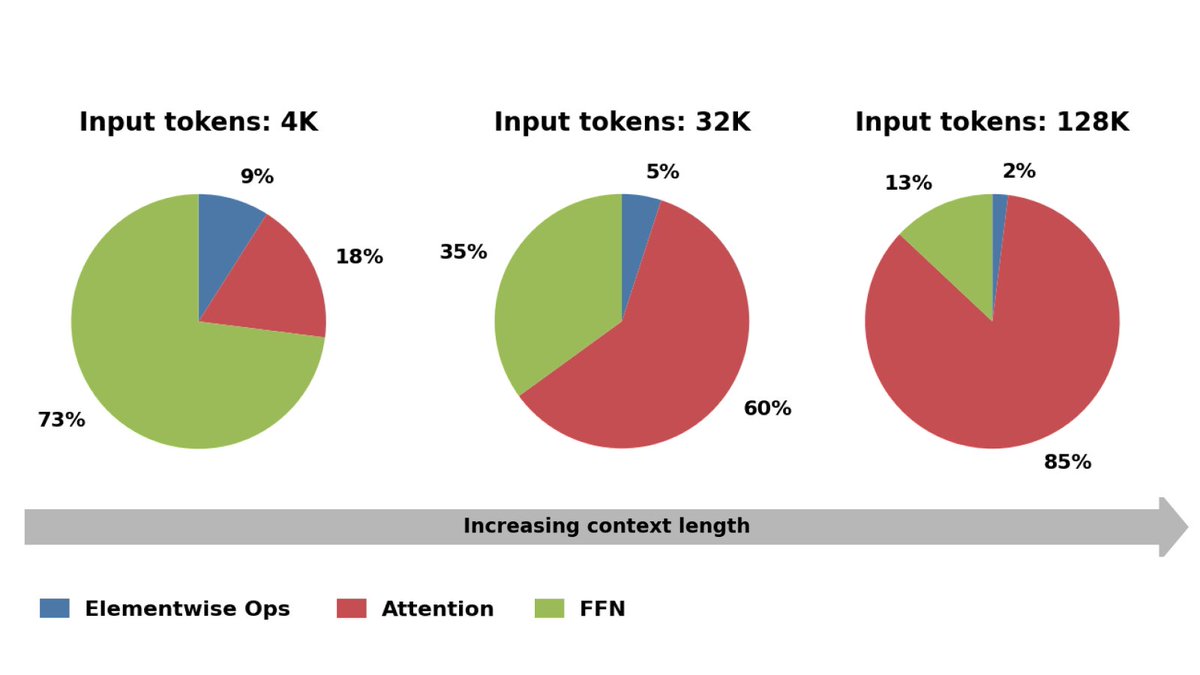
A long-context model's serving speed is largely determined before training begins. While attention used to be a minor part of inference cost, its share grows sharply as context windows expand. Once attention dominates, faster kernels become insufficient, and the attention mechanism's architecture sets the performance ceiling. NVIDIA's AI Model Co-Design series examines four architecture choices that determine this ceiling: group size, head dimension, KV-cache size, and parallelism strategy. The post explains how correct choices improve both system throughput and per-user responsiveness.