
NVIDIA NIM Optimization Delivers 2.78x More Concurrent Users for Nemotron Model
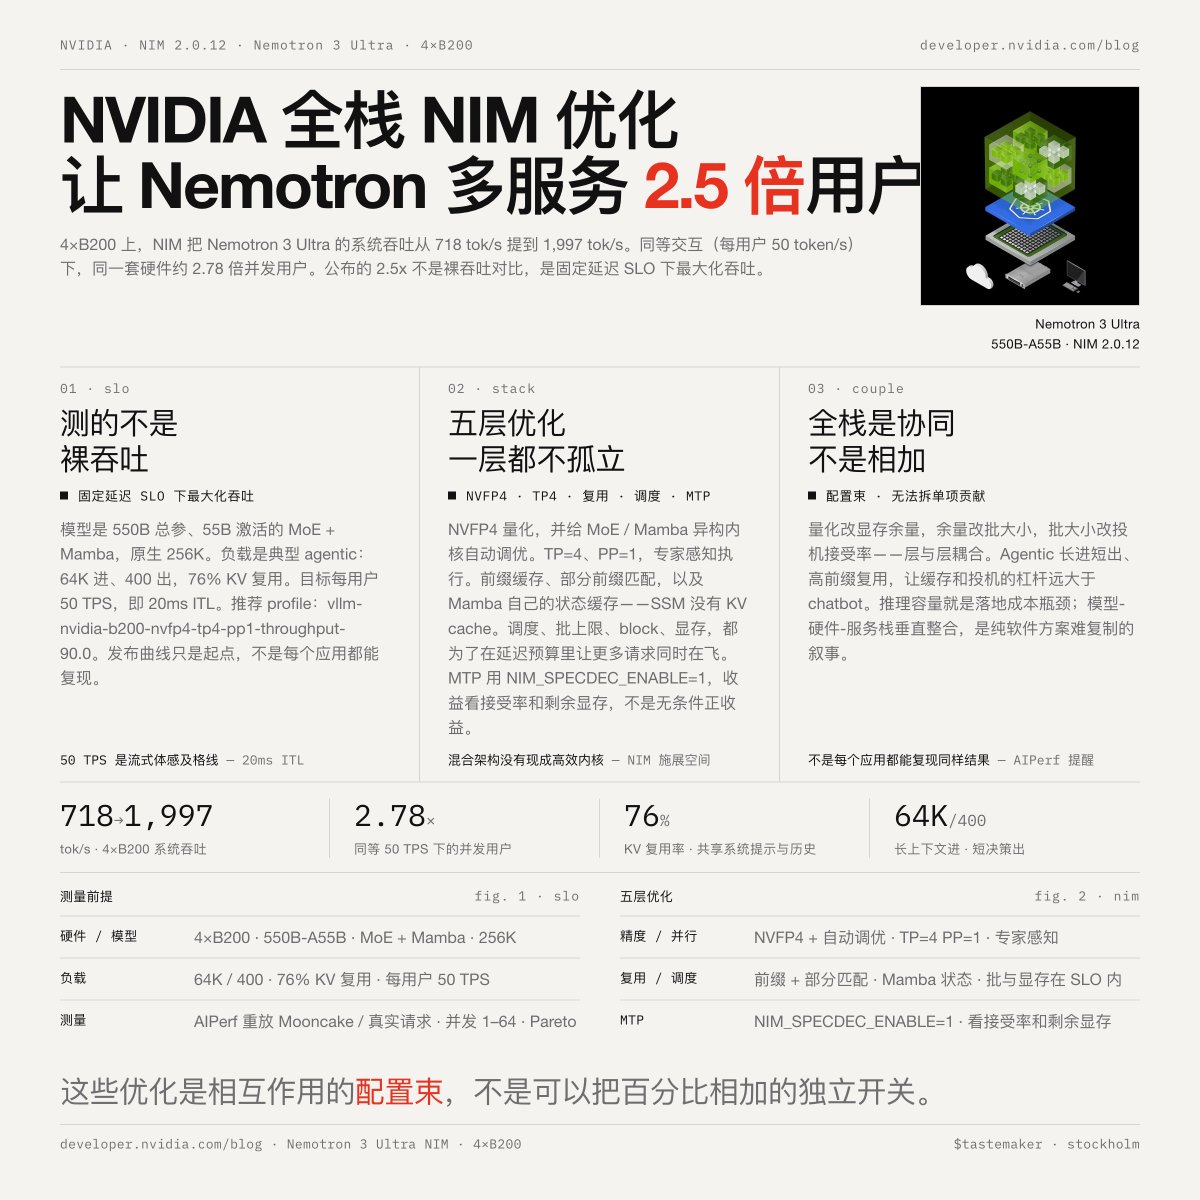
NVIDIA demonstrated how its NIM microservice stack optimized the Nemotron 3 Ultra 550B model on 4x B200 hardware to serve 2.78x more concurrent users while maintaining a latency SLO. The ‘full-stack’ optimization included NVFP4 quantization, MoE/Mamba-aware kernel tuning, prefix caching, and multi-token prediction speculative decoding, with the key insight that these optimizations are interdependent and cannot be applied independently for a cumulative gain.