
NVIDIA NIM Optimizes Nemotron 3 Ultra for 2.78x More Users
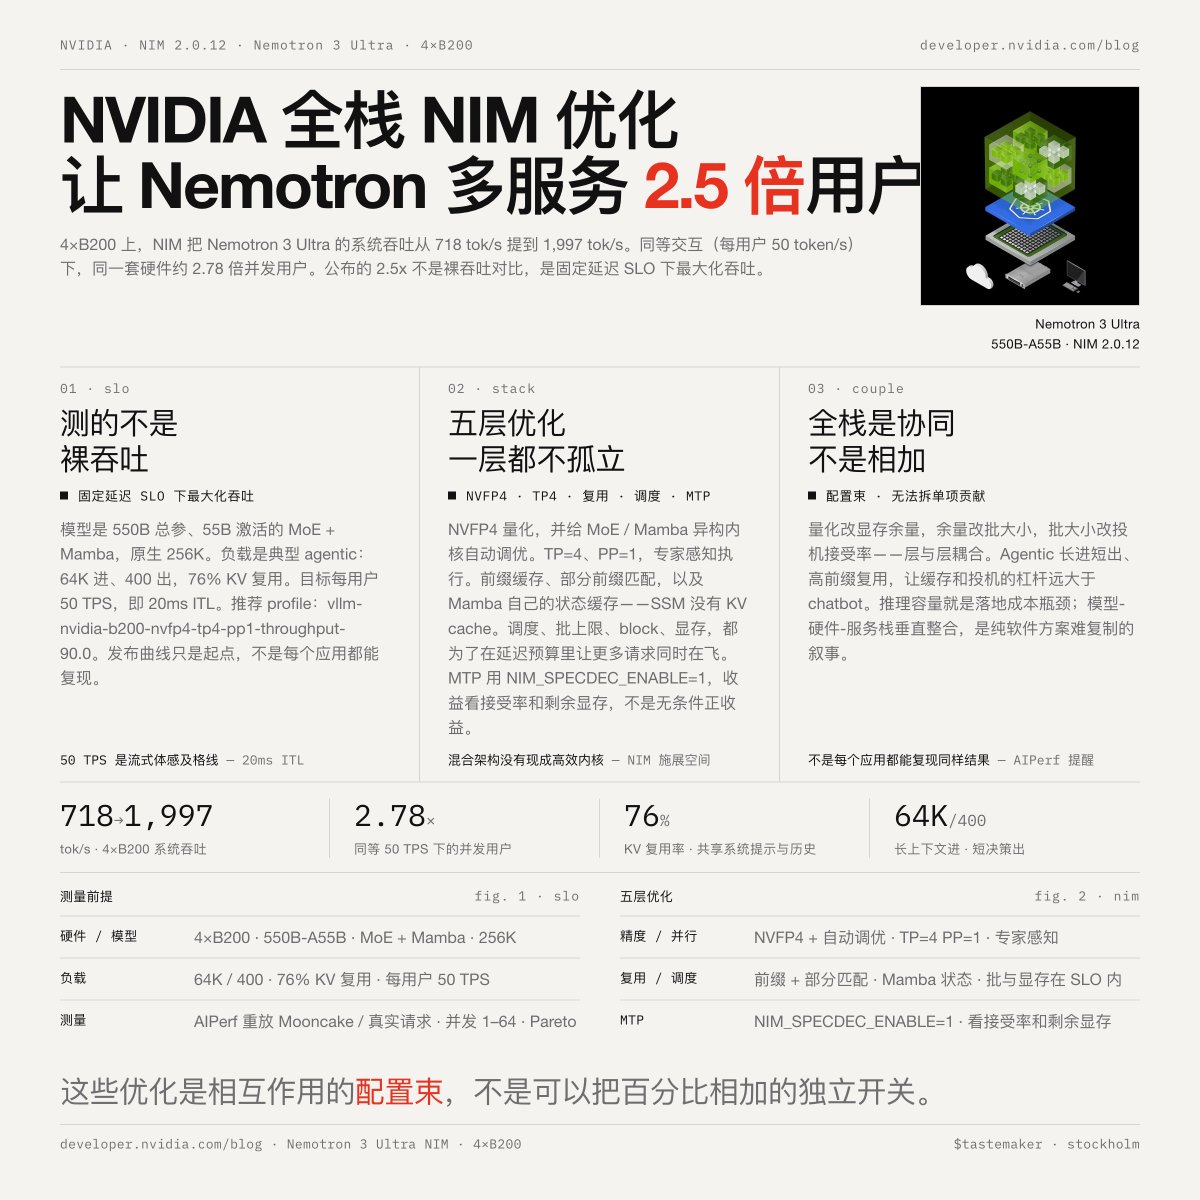
NVIDIA used NIM microservices to optimize the inference stack for Nemotron 3 Ultra on a 4×B200 system, boosting throughput from 718 to 1,997 tok/s. This allows the same hardware to serve 2.78 times more concurrent users at 50 tokens per second per user. The optimization involved five layers including NVFP4 quantization, prefix caching, and speculative decoding.