
NVIDIA Optimizes Nemotron 3 Ultra Inference to Serve 2.5x More Users
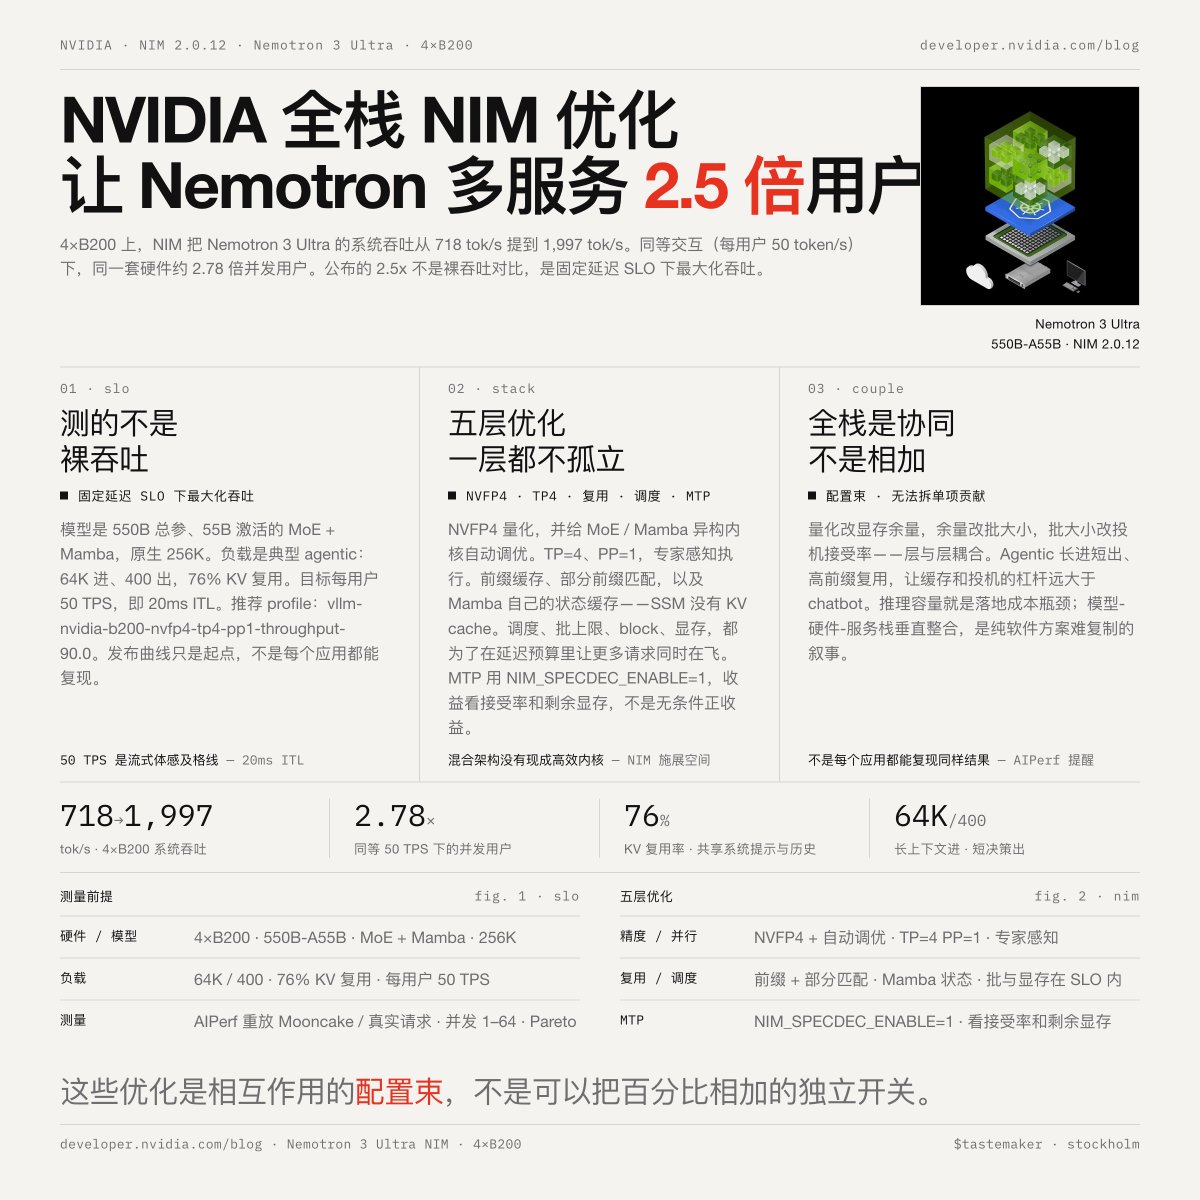
NVIDIA used its NIM microservice stack to optimize Nemotron 3 Ultra inference on 4x B200 systems, increasing throughput from 718 to 1,997 tok/s, enabling 2.78x more concurrent users at the same latency. The optimizations included NVFP4 quantization, prefix caching, and speculative decoding, tailored for agentic workloads with high prefix reuse.