
NVIDIA Optimizes Nemotron 3 Ultra with NIM Microservices
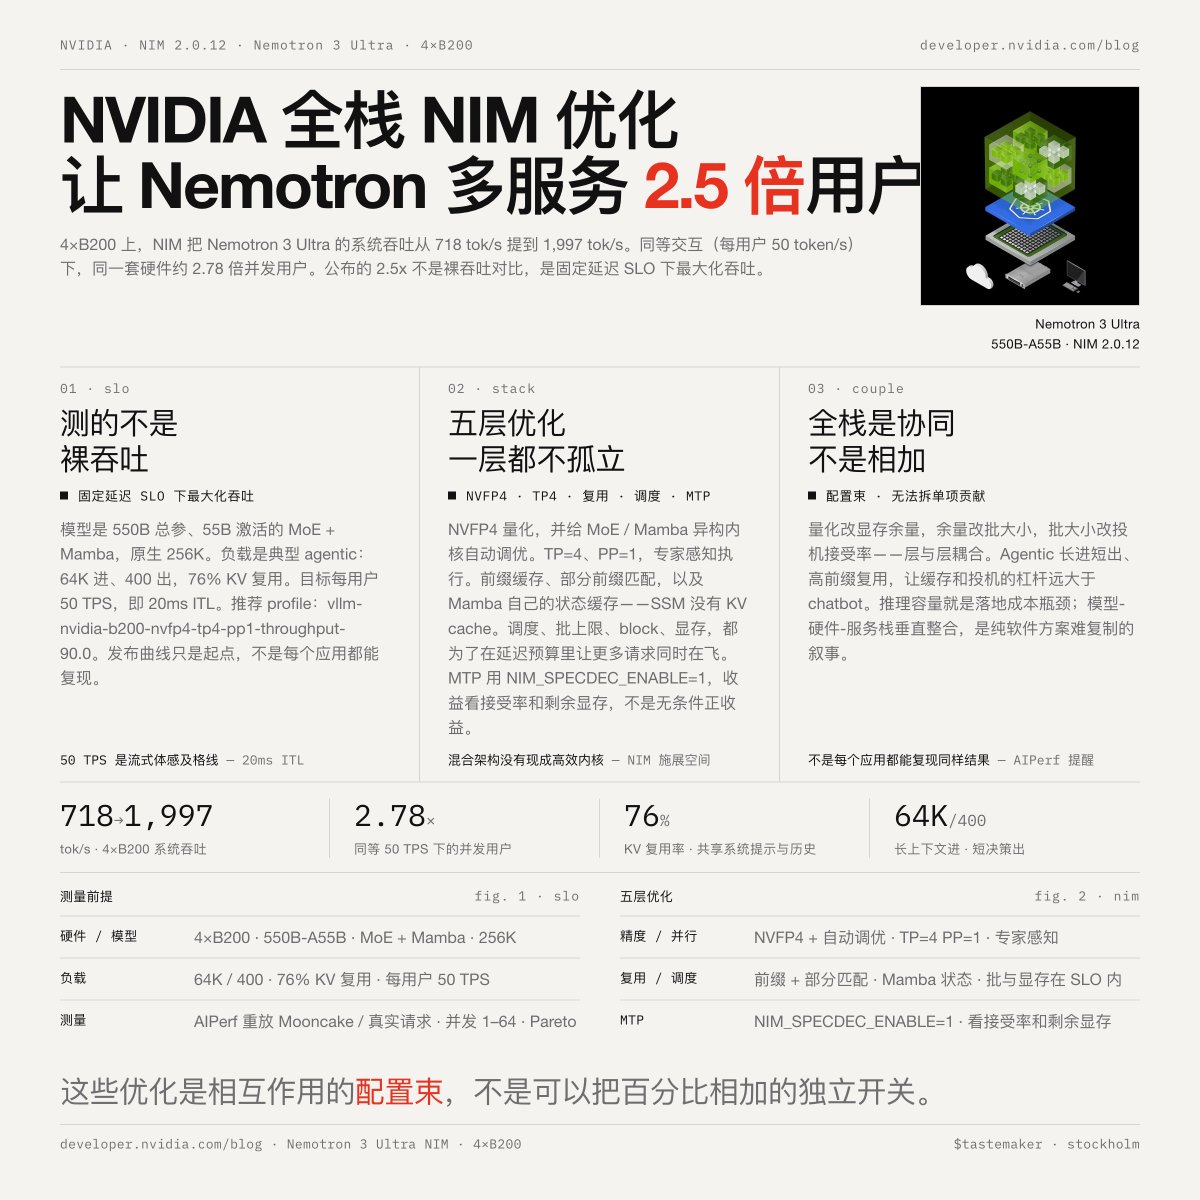
NVIDIA detailed how its full-stack NIM microservice optimization boosted Nemotron 3 Ultra throughput from 718 to 1,997 tokens per second on a 4xB200 system, enabling it to serve 2.5 times more concurrent users. The optimization involved techniques like NVFP4 quantization, prefix caching, and speculative decoding for agentic workloads.
Key insights
NIM Optimization Achieves 2.5x User Capacity Increase
NVIDIA’s full-stack NIM optimization on a 4x B200 system increased the Nemotron 3 Ultra's system throughput from 718 tok/s to 1,997 tok/s. Under a fixed latency SLO of 50 tok/s per user, this allows the same hardware to serve approximately 2.78 times the number of concurrent users, though NVIDIA states the official figure is a 2.5x improvement.
Five-Layer Optimization Strategy Detailed
The optimization involved five key layers: 1) NVFP4 quantization with auto-tuned kernels for the MoE+Mamba hybrid architecture. 2) Parallel strategy using tensor parallelism (TP=4). 3) Prefix caching and state reuse for long contexts. 4) Scheduler and batch-size tuning for memory management. 5) Multi-token prediction (MTP) speculative decoding, enabled via a flag, which provides incremental gains depending on acceptance rate.
Optimization Paradigm for Agentic Workloads
The post analyzes how this represents a new optimization paradigm for the agentic era. Agentic workloads feature long inputs and short outputs with high prefix reuse, making techniques like prefix caching and speculative decoding more impactful than in traditional chatbot scenarios. The analysis emphasizes that these optimizations are interdependent, not simply additive.
NVIDIA Highlights Vertical Integration as a Moat
The combination of NVFP4 native quantization, Blackwell hardware, and auto-tuned kernels showcases NVIDIA’s strategy of software-hardware co-design. This vertical integration provides performance gains that are difficult to replicate with pure software solutions, serving as a competitive advantage for NVIDIA in AI inference.