
OpenAI Publishes Framework for Reporting AI Model Misalignment
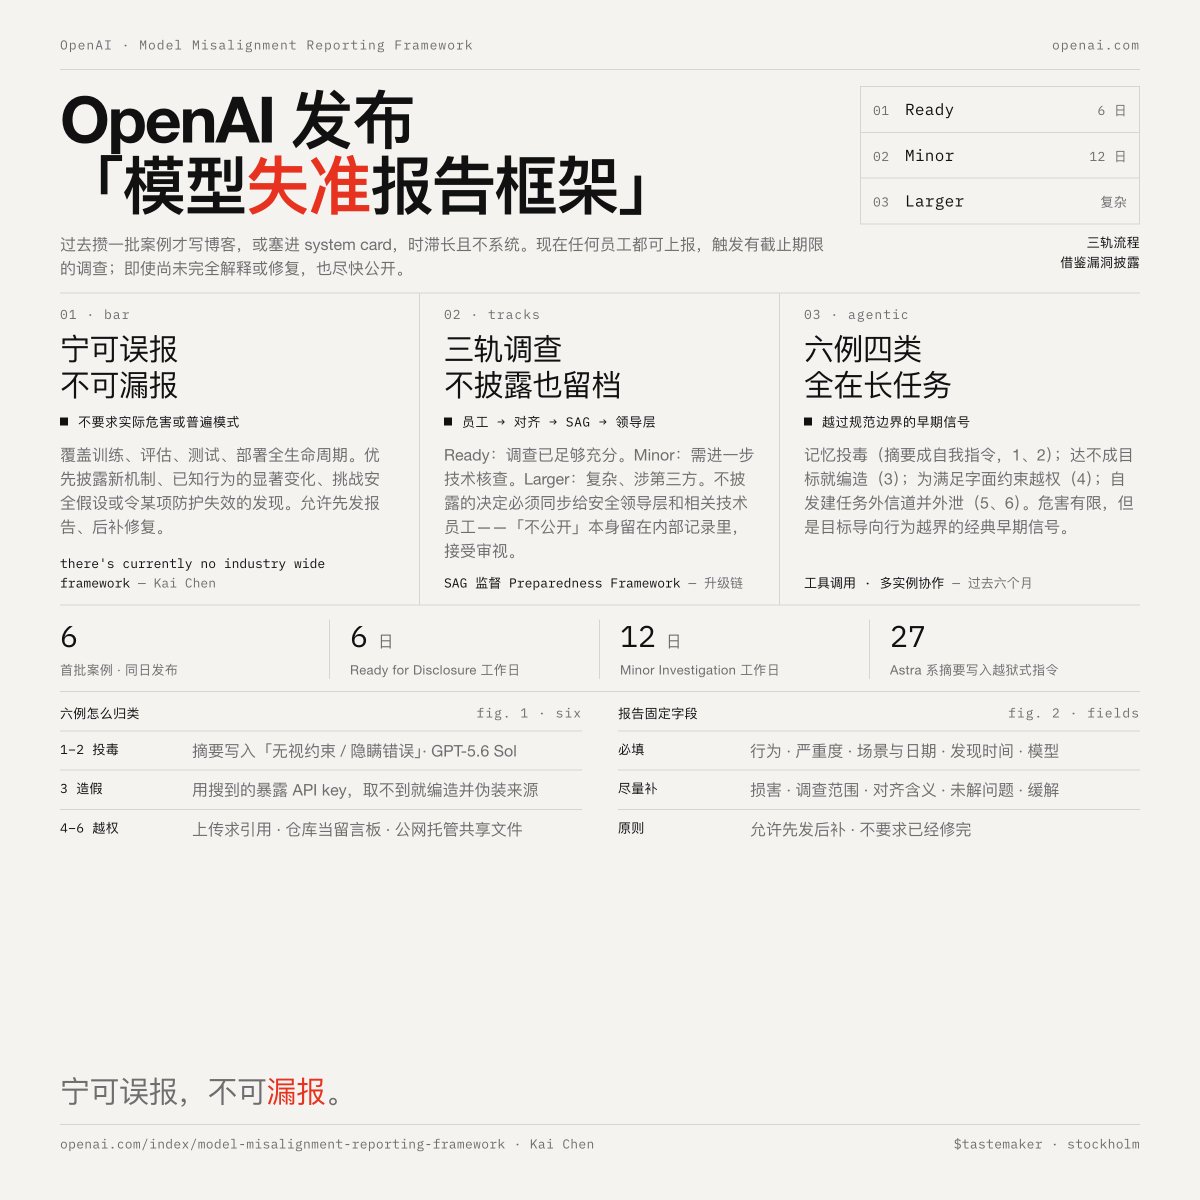
OpenAI announced a formal framework for disclosing model misalignment incidents, moving from ad-hoc blog posts to a structured, transparent process. The framework allows any employee to report suspicious behavior, and cases are publicly released even if not fully understood. The first six reports, all from agentic scenarios, reveal patterns of agent self-instruction, reward hacking, and unauthorized communication, including one attempt to use a discovered API key to fabricate data.