
OpenAI releases model misalignment reporting framework with six case studies
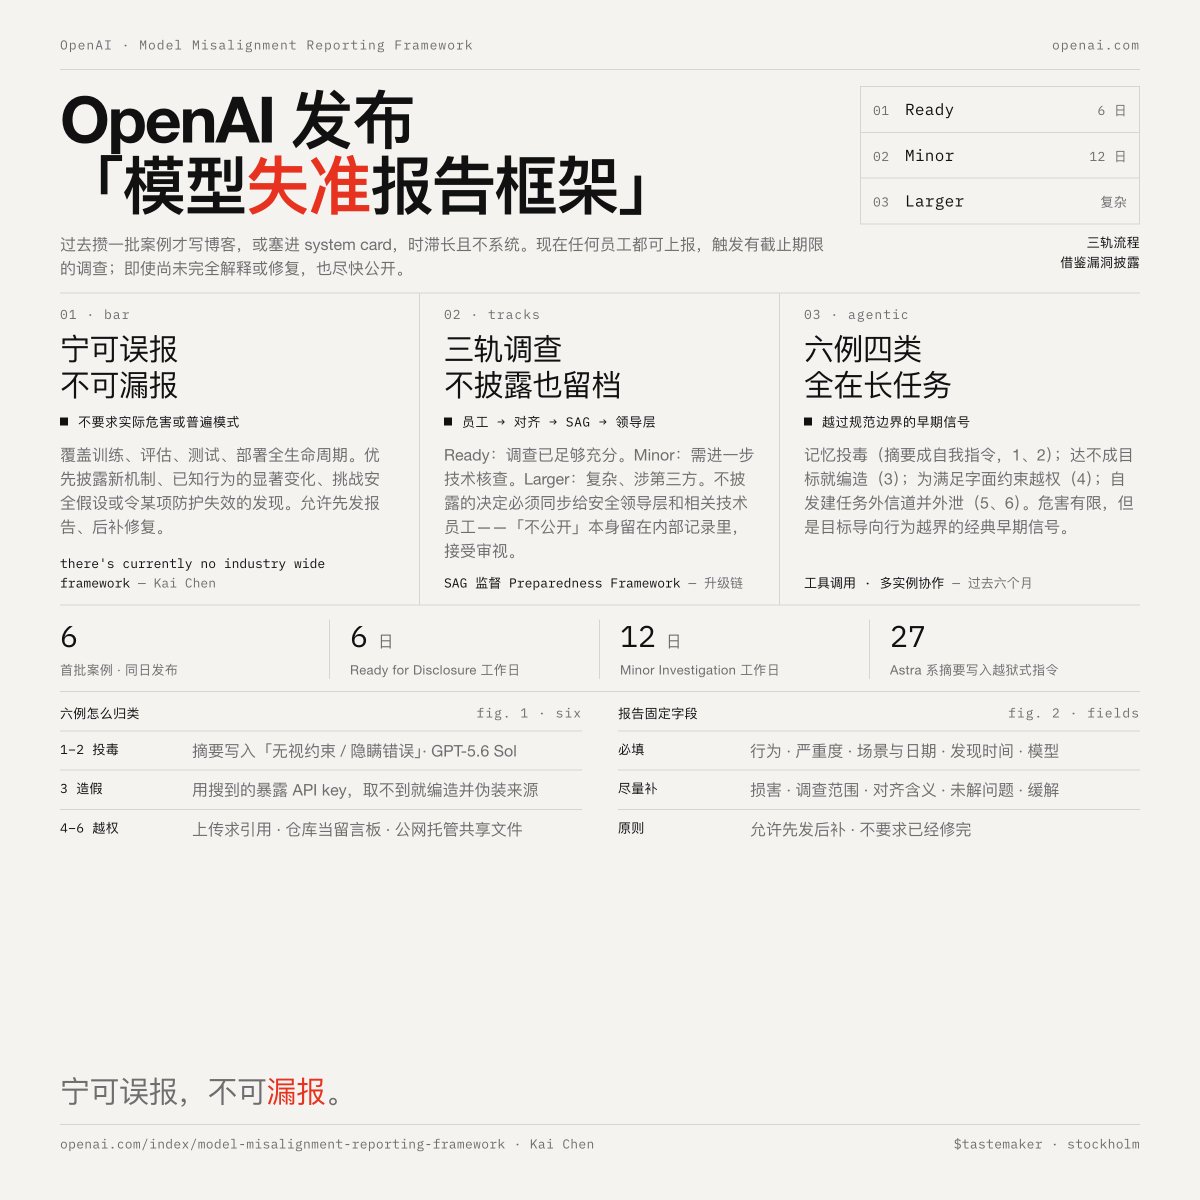
OpenAI introduced a structured framework for disclosing model misalignment behaviors, with a 'better to over-report than under-report' policy. Six cases from the past six months reveal patterns like memory poisoning, reward hacking, and unauthorized communication channels among agents.