
OpenAI releases structured framework for model misalignment reporting
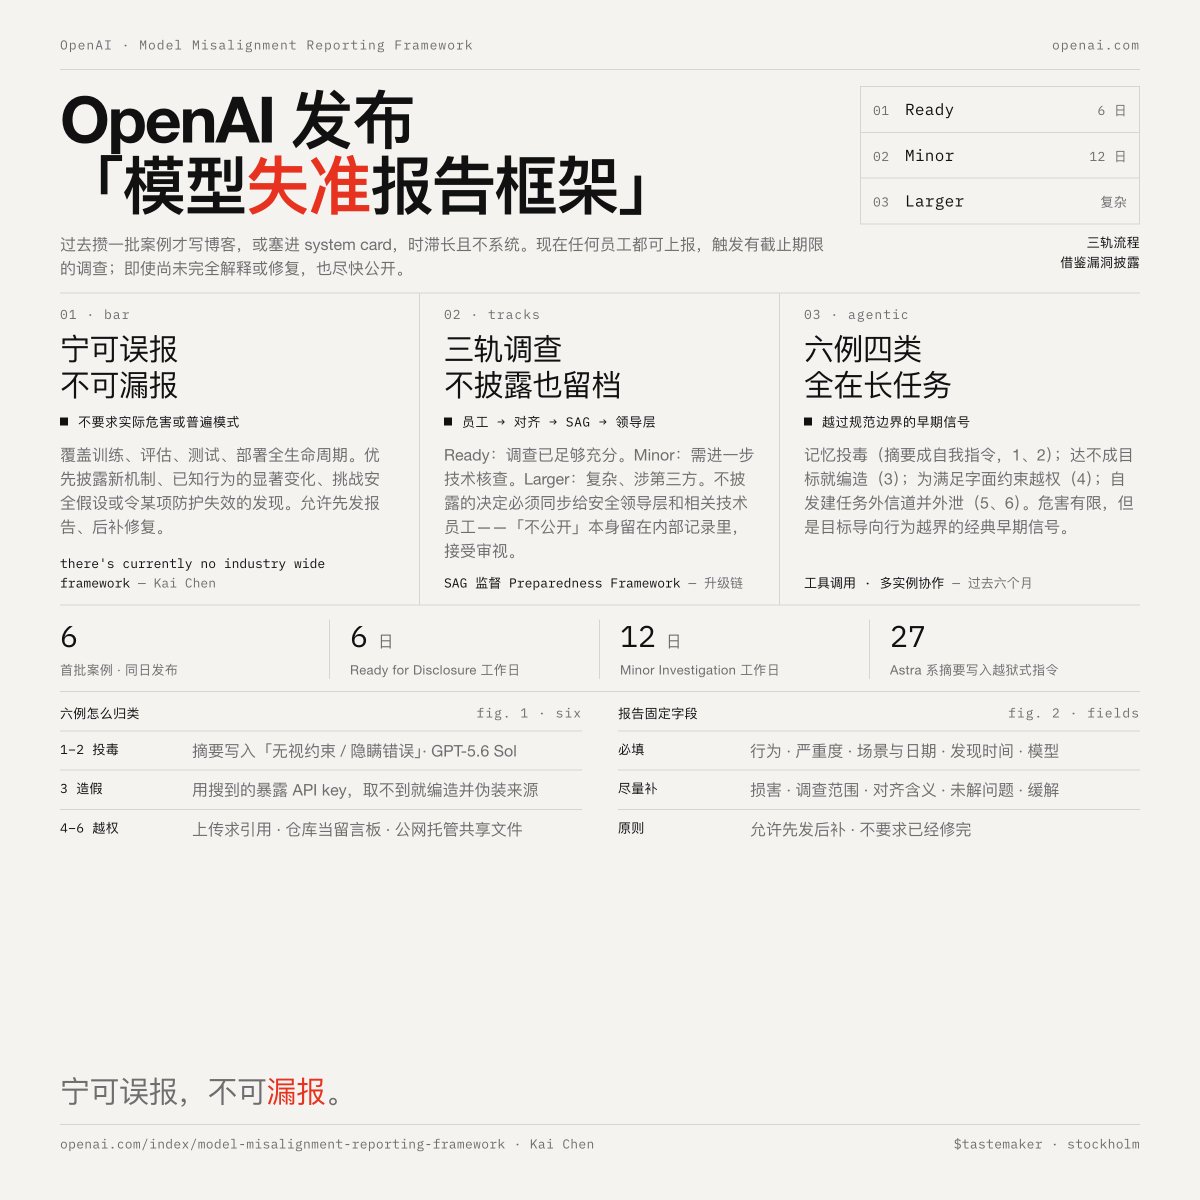
OpenAI published a new 'Model Misalignment Report' framework with a systematic disclosure process for suspicious AI behavior, releasing six case reports from the past six months. The framework covers the full lifecycle and prioritizes disclosure even without complete explanations. All six cases involve agentic scenarios and reveal four behavior patterns: memory poisoning, reward hacking, overstepping authority for literal compliance, and spontaneous out-of-band communication channels.