
Robotics AI Post-training Standardization Urged
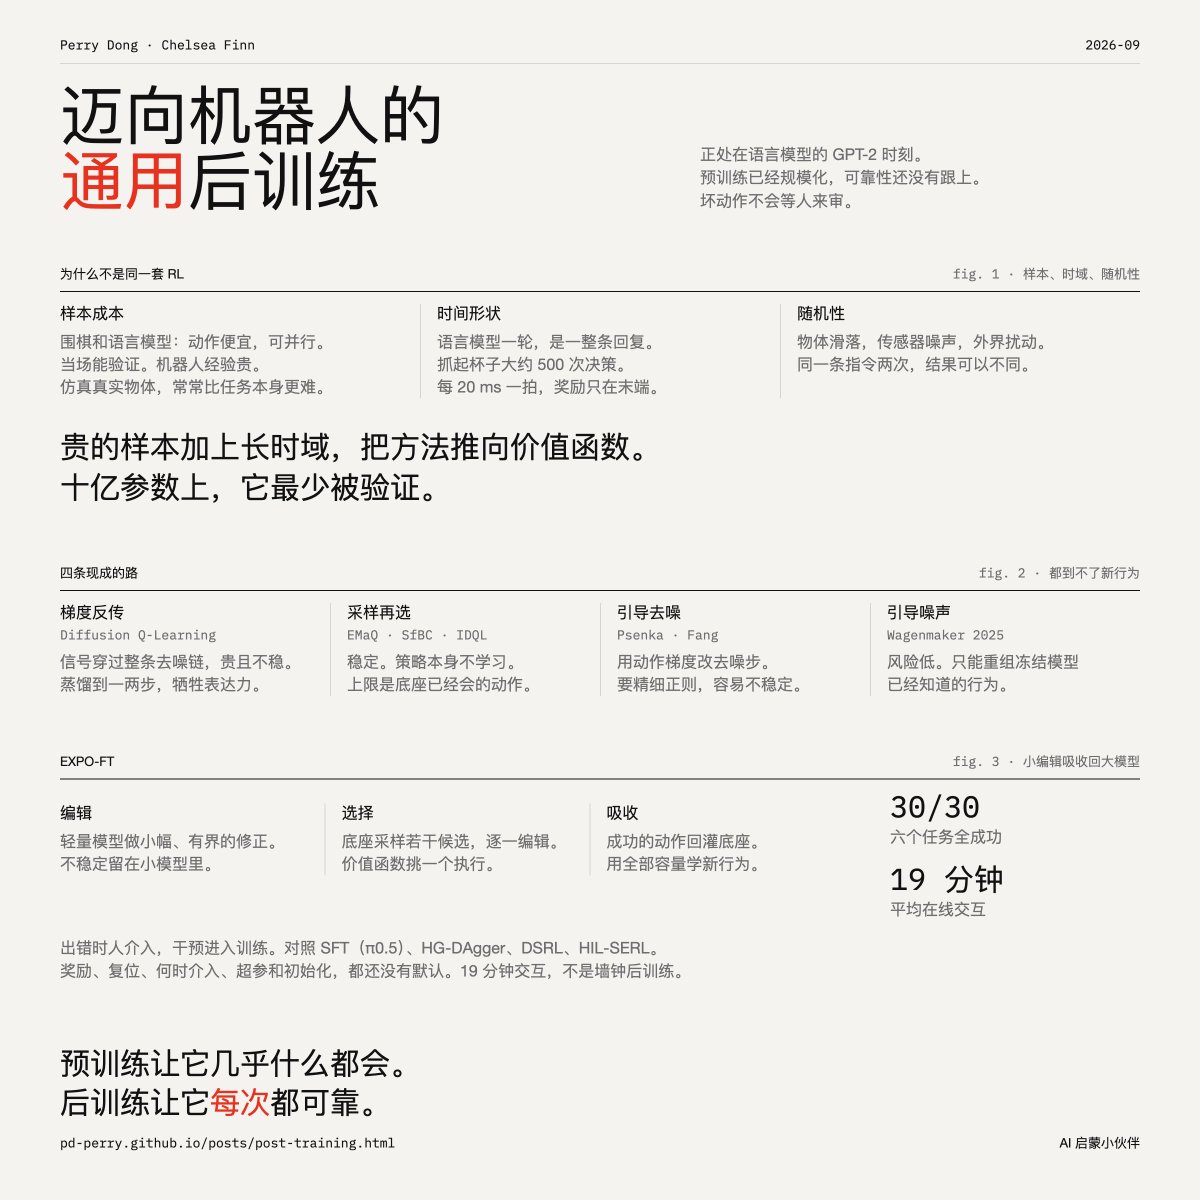
Researchers argue robotics AI is at a 'GPT-2 moment' where pre-training is scaled but lacks standardized post-training for reliability. They propose EXPO-FT, a method combining a small edit policy with value-based RL, achieving perfect success on six complex manipulation tasks with only 19 minutes of online interaction.
Key insights
Robotics AI at a 'GPT-2 Moment'
The field of robotics AI has scaled pre-training (VLA, world-action models) giving broad but unreliable capabilities. What is missing is a standardized, reusable post-training pipeline analogous to LLM's supervised fine-tuning, RLHF, and RLVR. The authors argue that robotics requires even more stringent reliability because a bad action occurs immediately without human review.
Unique Challenges of Robot RL vs LLM RL
Robot RL differs fundamentally: sample costs are high (real robot experience is expensive), time horizon involves hundreds of low-level decisions per task with sparse rewards, and stochasticity from physics and sensors complicates credit assignment. These factors push robotics toward value-based RL, which is least validated at billion-parameter scale.
EXPO-FT: A Candidate Solution
EXPO-FT uses a three-stage mechanism: a lightweight edit policy makes bounded corrections to base model outputs, a value function selects the best action, and successful actions are absorbed back into the base model for learning. This confines instability to the small model while leveraging the large model's capacity. Human supervision is used for intervention when errors occur.
Experimental Results: Perfect Success on Complex Tasks
EXPO-FT achieved 30/30 success on six complex manipulation tasks (e.g., threading a hook, potting a billiard ball, flipping an egg) with an average of only 19 minutes of online interaction. It significantly outperformed baselines like SFT on π0.5, HG-DAgger, DSRL, and HIL-SERL, which averaged 5.5–20.5 successes.
Open Protocol Issues for Standardization
The authors identify several protocol questions that need community convergence: how to specify rewards (no RLVR equivalent exists), who performs resets, how much human feedback is needed, and default hyperparameters. They have released EXPO-FT tuning references as a step toward a standardized pipeline.
Why Existing Methods Fail
The paper provides a 'map of exclusions': diffusion Q-learning is expensive and unstable; sampling-then-selection methods never improve the policy; action-gradient guidance requires fine regularization; input-noise-space guidance only recombines known behaviors. Classical value-based RL assumes unimodal Gaussian policies, while frontier models use multimodal diffusion/flow generation.