
Robotics' 'GPT-2 moment': EXPO-FT universal post-training recipe
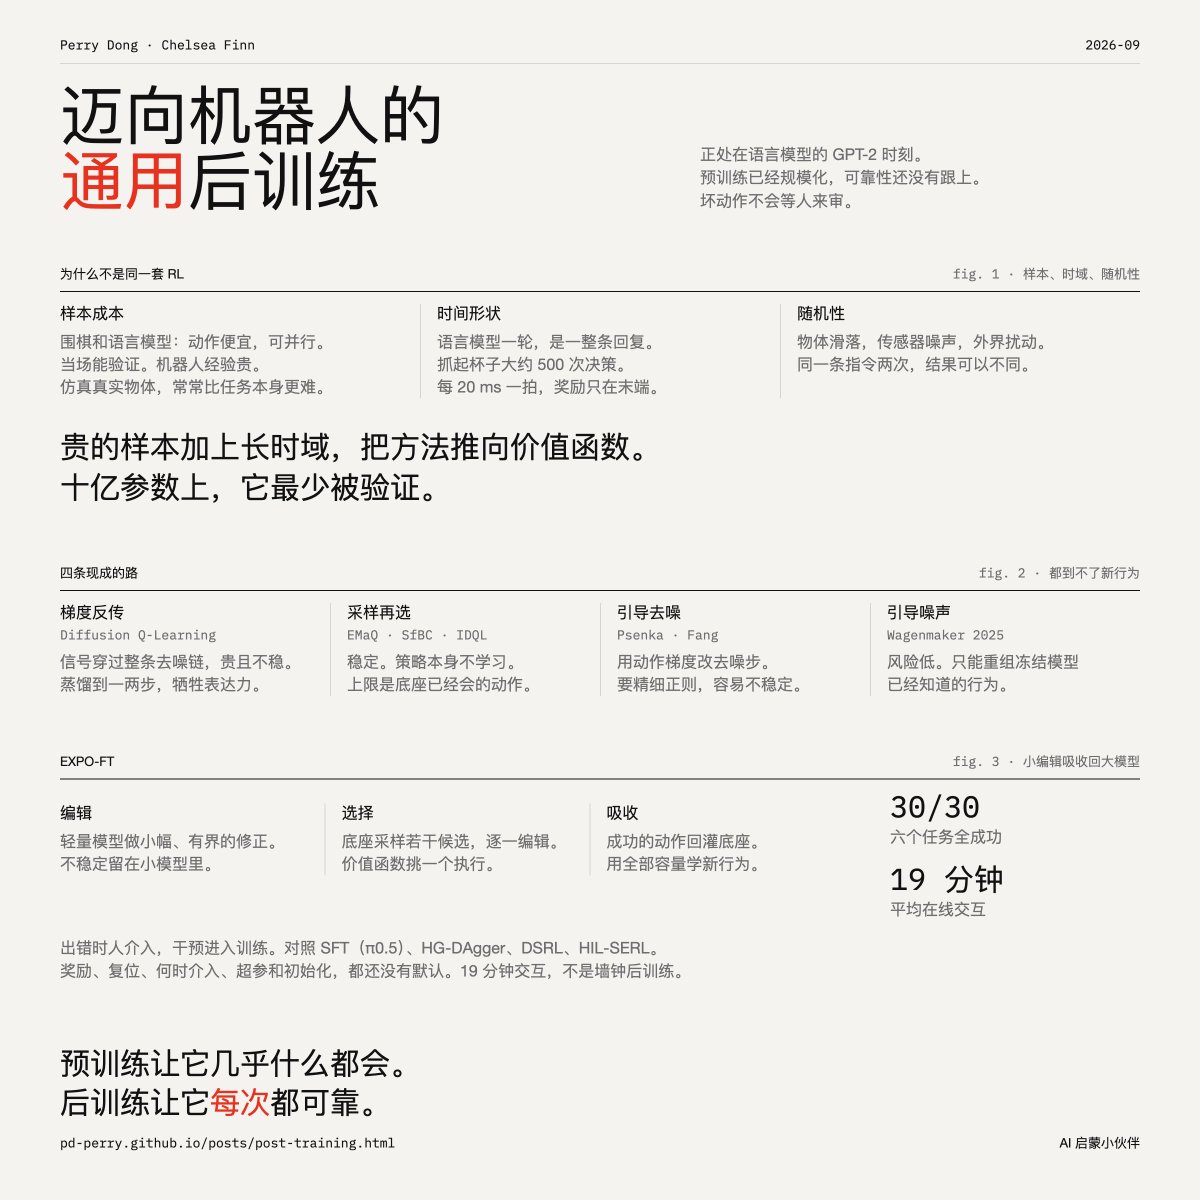
Researchers introduced EXPO-FT, a universal post-training method for robot RL that uses an edit policy, execution selection, and absorption to stabilize large foundation models. On six complex manipulation tasks, it achieved 30/30 success with only 19 minutes of online interaction, outperforming baselines significantly.
Key insights
Robotics at GPT-2 Moment
The robotics field is compared to LLMs' 'GPT-2 moment': pretrained VLA and world-action models are scalable but unreliable. The missing piece is a standardized post-training recipe to convert uncertain capabilities into reliable performance. EXPO-FT aims to provide that recipe, analogous to supervised fine-tuning and RLHF in language models.
Challenges of Robot RL vs LLM RL
Robot RL differs from LLM RL in three ways: sample cost is high as physical experiments are expensive; time horizon requires hundreds of low-level steps with sparse rewards; environment stochasticity (e.g., slipping) pollutes credit assignment. These push robotics toward value-based RL, which is least validated at billion-parameter scale.
EXPO-FT Core Mechanism
EXPO-FT consists of three stages: 1) an edit policy (lightweight model) makes bounded corrections to candidate actions from the base model, shifting them toward higher value within their mode; 2) during execution, several candidate actions are sampled, edited, and the best selected by a value function; 3) successful actions are absorbed back into the pretrained model for training, internalizing improvements.
Human-in-the-Loop Supervision
Humans act as supervisors: when the robot errs, the human intervenes, and intervention data enters the training loop. The authors analogize this to Waymo's remote safety operators for scalability. This keeps the system safe while allowing continuous improvement from real-world corrections.
Experimental Results
EXPO-FT achieved 30/30 success on six complex tasks (e.g., threading a light garland, potting a flower, flipping an egg) with an average of 19 minutes of online interaction. Baseline methods (SFT on π0.5, HG-DAgger, DSRL, HIL-SERL) scored between 5.5 and 20.5 average successes.
Open Protocol Issues
For EXPO-FT to become a universal recipe, the community must converge on reward specification (no RLVR equivalent for robots), reset strategies, human intervention modalities, hyperparameter defaults, and initialization data weighting. The authors have published tuning recommendations as a first step.
Why Existing Methods Fail
The paper systematically rules out alternative approaches: Diffusion Q-Learning is costly and unstable; EMaQ limits policy to base model proposals; action-gradient guidance requires delicate regularization; noise-space guidance only recombines frozen behaviors. Classic value-based RL assumes unimodal policies incompatible with multimodal behaviors of diffusion models.