
Robotics Post-Training Reaches Its 'GPT-2 Moment'
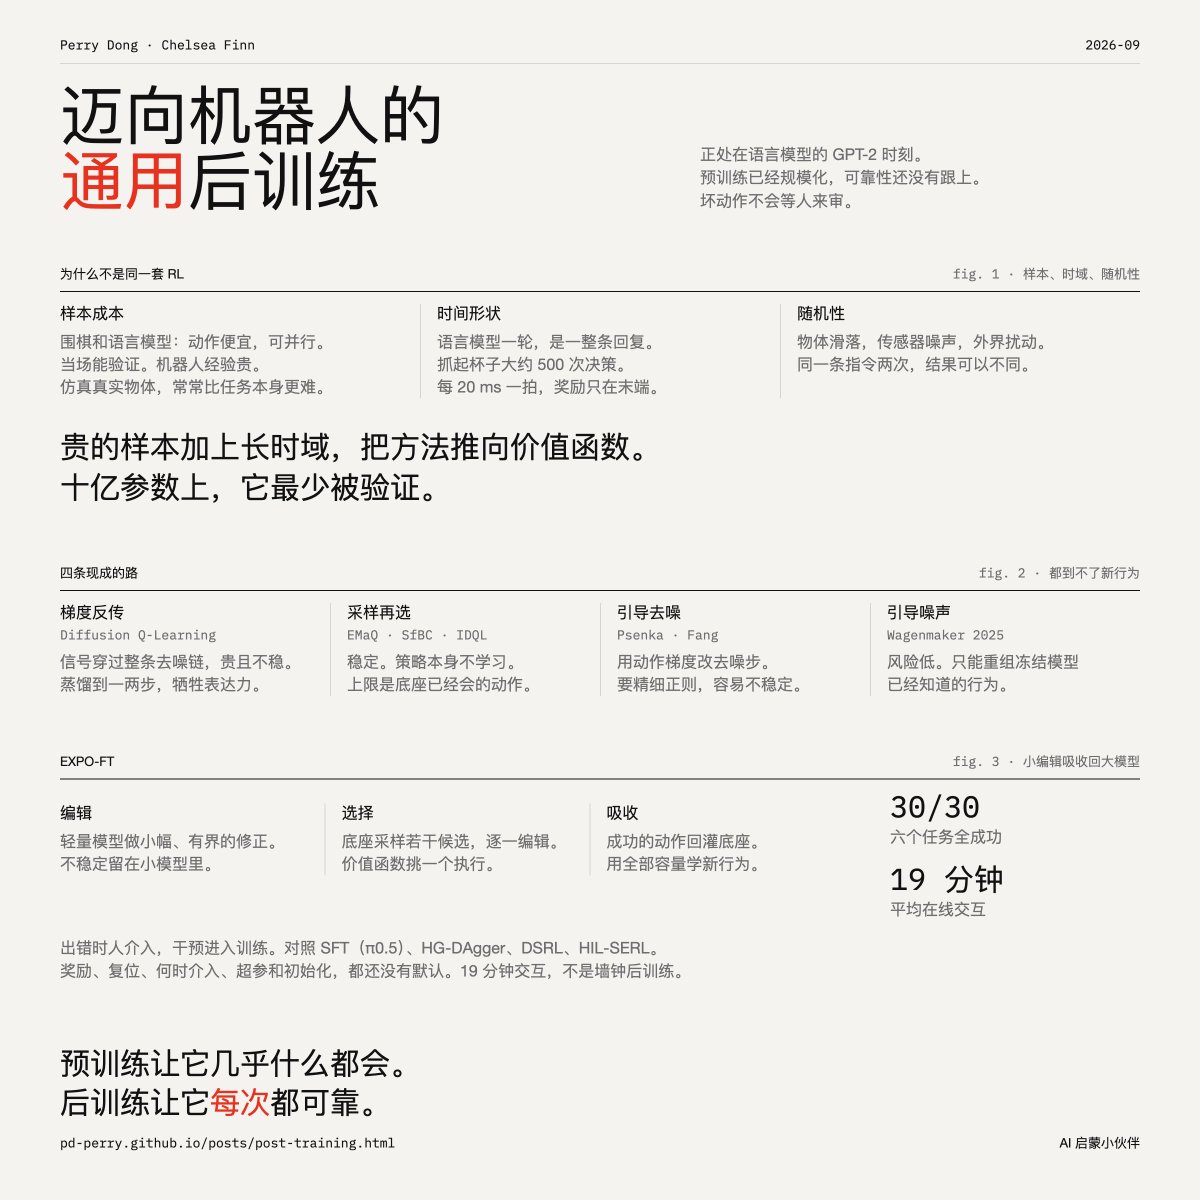
Researchers argue that robotics post-training is at a similar inflection point as LLMs were with GPT-2, needing standardized methods to turn broad capabilities into reliable performance. They propose EXPO-FT, a value-based RL method using a small edit policy to refine actions from a large pretrained model, achieving 30/30 success on complex tasks with minimal online interaction.
Key insights
Analogy to GPT-2 Moment in Robotics
The authors state that robotics post-training is at the 'GPT-2 moment' of LLMs: pretrained VLA and world-action models have broad but unreliable skills. The missing piece is a standardized, reusable post-training pipeline to convert 'can do' into 'reliably does'. LLMs followed a path from supervised fine-tuning to RLHF to RLVR, and robotics needs an equivalent.
Challenges Unique to Robot RL
Robot RL differs from LLM RL in three ways: sample cost (robot experience is expensive, simulation may be harder than the task), time shape (hundreds to thousands of low-level decisions per episode with sparse reward), and stochasticity (object slip, sensor noise). These push robotics toward value-based RL, which is least validated at billion-parameter scale.
Limitations of Existing Methods
The paper maps out why current methods fail: Diffusion Q-learning is expensive and unstable; sampling-based methods (EMaQ, SfBC) are capped by base model; action gradient methods need careful regularization; input noise space guidance only recombines known behaviors. Classic value-based RL assumes Gaussian unimodal policies, while modern models use diffusion/flow for multimodal behavior.
EXPO-FT Mechanism and Design
EXPO-FT uses a three-stage process: (1) a lightweight edit policy makes bounded corrections to candidate actions from the base model, pushing them toward value peaks; (2) the robot samples multiple candidates, edits them, and selects the best via value function; (3) successful actions are absorbed back into the pretrained model via continued training. RL instability is confined to the small edit policy.
Experimental Results and Human-in-Loop
EXPO-FT achieved 30/30 success on six complex manipulation tasks (e.g., threading a hook, potting a ball, flipping an egg) with an average of 19 minutes of online interaction. It outperformed baselines like SFT, HG-DAgger, DSRL, and HIL-SERL. Human role is as remote safety monitor, intervening on errors, with data used for training, analogous to Waymo's remote safety operators.
Open Protocol Issues for Standardization
The paper identifies open problems that need community convergence: reward specification (no RLVR equivalent for robotics), reset strategies, human intervention timing, hyperparameter defaults, and initialization data weighting. The authors released EXPO-FT tuning references as a step toward a standardized pipeline.