
Robotics Post-training with EXPO-FT: Universal RL Method
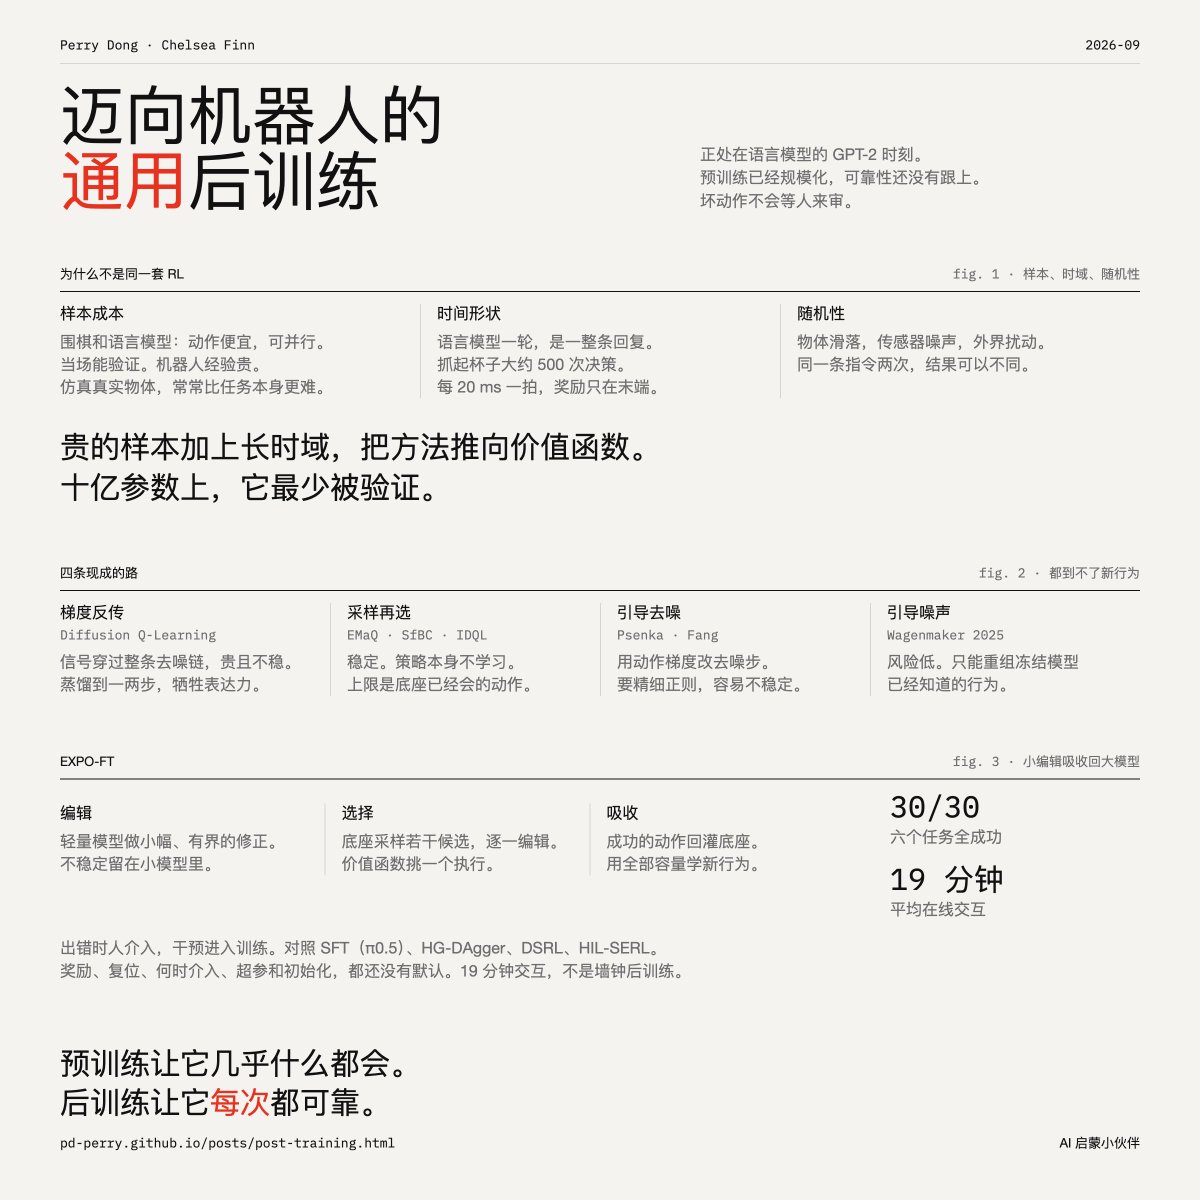
Researchers proposed EXPO-FT, a value-based RL method for post-training large robot models. It uses a small edit policy to refine actions and achieves 30/30 success on six complex tasks with only 19 minutes of online interaction. The method addresses the core challenge of credit assignment in long-horizon robotic tasks.
Key insights
The robotics 'GPT-2 moment' and need for post-training
The robotics field is at a 'GPT-2 moment': pre-training (VLA, world-action models) has scaled, giving models broad but unreliable capabilities. What's missing is a standardized, reusable post-training pipeline to turn 'can do' into 'reliably does every time'. The authors argue robotics needs an equivalent to the LLM pipeline of supervised fine-tuning, RLHF, and RLVR, but with stricter reliability requirements because a single bad action in robotics cannot be reviewed before it happens.
Key differences between robot RL and LLM RL
Robot RL differs from LLM RL in three ways: sample cost (robot experience is expensive, simulation of real objects can be harder than the task itself), temporal shape (robots involve hundreds to thousands of low-level decisions per episode with reward only at the end, making credit assignment extremely difficult), and stochasticity (object slip, sensor noise, external disturbances pollute credit assignment). These factors push robotics toward value-based RL, which is the least validated family at billion-parameter scale.
Why existing methods fail
The paper systematically evaluates existing approaches: Diffusion Q-Learning suffers from long denoising chains; sampling-then-selection methods (EMaQ, SfBC, IDQL) never learn a policy, capped by the base model's proposals; action gradient guidance requires careful regularization; input noise space guidance can only reorganize known behaviors. Classical value-based RL (DDPG/TD3/SAC) assumes Gaussian unimodal policies, while frontier models use diffusion/flow generation for multimodal behavior, and bootstrapping errors amplify instability at billion-parameter scale.
EXPO-FT mechanism: small model edit + absorption
EXPO-FT uses a three-stage design: (1) an edit policy (lightweight small model) makes bounded corrections to candidate actions from the base model, pushing them toward value peaks within their modality; (2) during execution, the robot samples multiple candidates, edits them, and selects the best via value function; (3) absorption: successful actions are fed back to the pre-trained large model, allowing the small edit policy's improvements to be internalized. RL instability is confined to the small model, preventing dangerous actions from the large model.
Experimental results and human-in-the-loop
EXPO-FT was tested on six complex manipulation tasks (e.g., threading a wire through a hook and plugging it, potting a billiard ball, flipping an egg). It achieved 30/30 full success with an average of 19 minutes of online interaction, significantly outperforming baselines like SFT on π0.5, HG-DAgger, DSRL, and HIL-SERL (which averaged 5.5–20.5 successes). Humans act as supervisors: when the robot makes an error, human intervention data enters training, analogous to Waymo's remote safety operators.
Open protocol questions for universal adoption
The paper identifies several issues that must be resolved for community convergence: how to specify rewards (robotics lacks an RLVR equivalent; learned success classifiers or reward models are promising), who performs resets (learned reset strategies, reversible task design), how much human intervention is needed and when, default hyperparameters (learning rate, UTD ratio, stopping criteria, control frequency), and how to weight initialization data. The authors released EXPO-FT's tuning reference as a step toward standardization.