
Search and memory primitives for LLMs
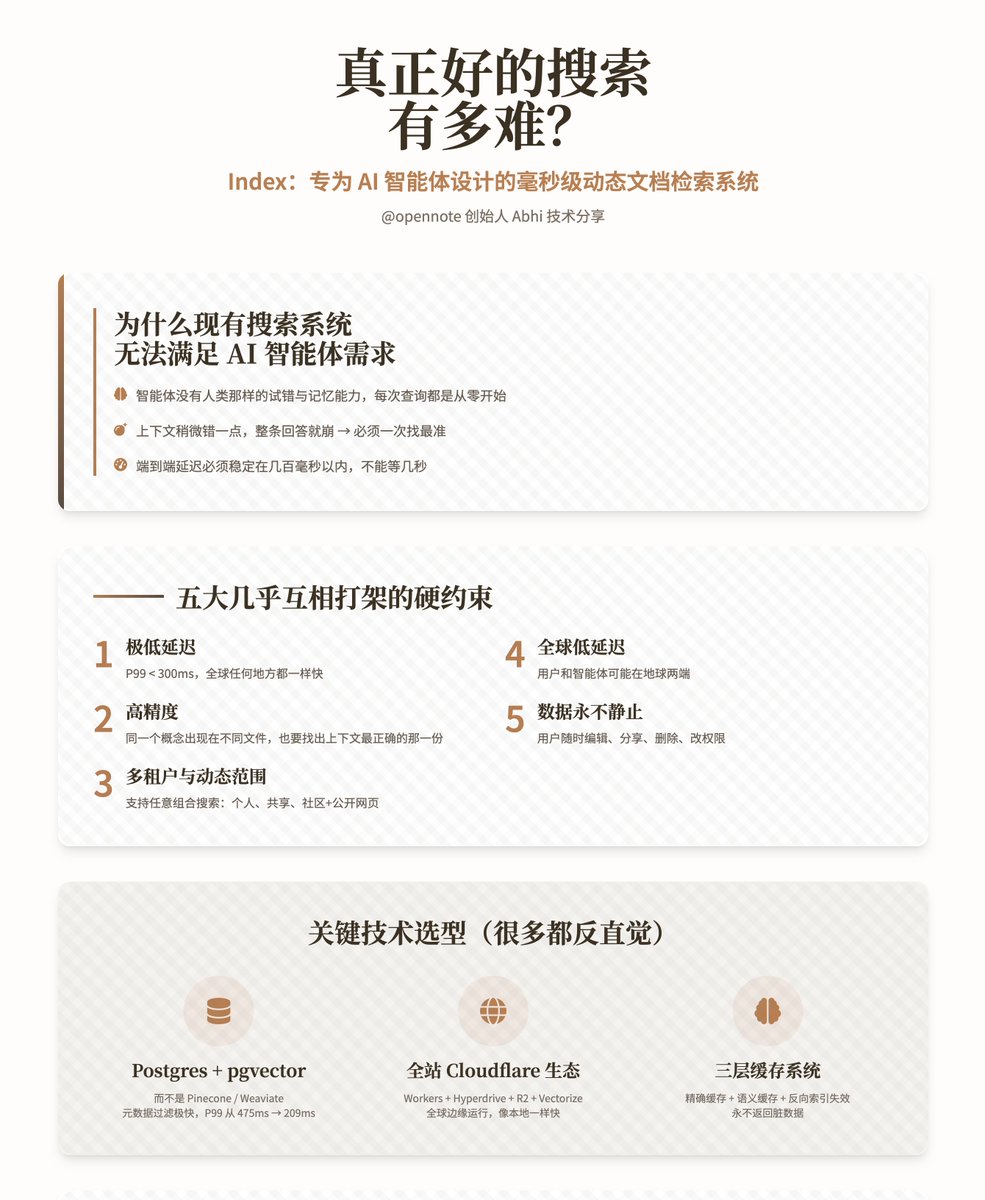
New retrieval and memory systems target millisecond-level, high‑precision agent retrieval and persistent LLM memory.
Key insights
Opennote Index targets millisecond dynamic retrieval for agents
Opennote described Index, a retrieval system optimized for AI agents with P99 <300ms latency. Index uses Postgres (pgvector/pg_trgm/tsvector) over dedicated vector DBs to enable efficient metadata prefiltering, mixed keyword/vector search, multi‑tenant dynamic filters, and an edge‑distributed runtime via Cloudflare Workers. The ingestion pipeline hashes chunks to only recompute changed embeddings and integrates a three‑tier cache plus precise invalidation to guarantee freshness.
Memori provides SQL‑native, open memory primitives for LLMs and agents
Memori is an open memory engine that integrates with standard SQL databases to provide persistent, queryable memories for LLMs. It intercepts LLM calls to inject short‑term memories, extracts entities and facts post‑response, runs periodic 'consciousness' jobs to distill long‑term memories, and supports conscious/auto/combined memory modes with one‑line integration.
Hybrid designs favor SQL for metadata, vector fusion and operational control
Both systems favor SQL primitives for metadata filtering, operational semantics (UPSERT/DELETE), multi‑tenant isolation, and exact cache invalidation, arguing that these traits deliver better latency, consistency, and dynamic filtering than many vector stores.