
Thinking Machine releases Inkling multimodal model
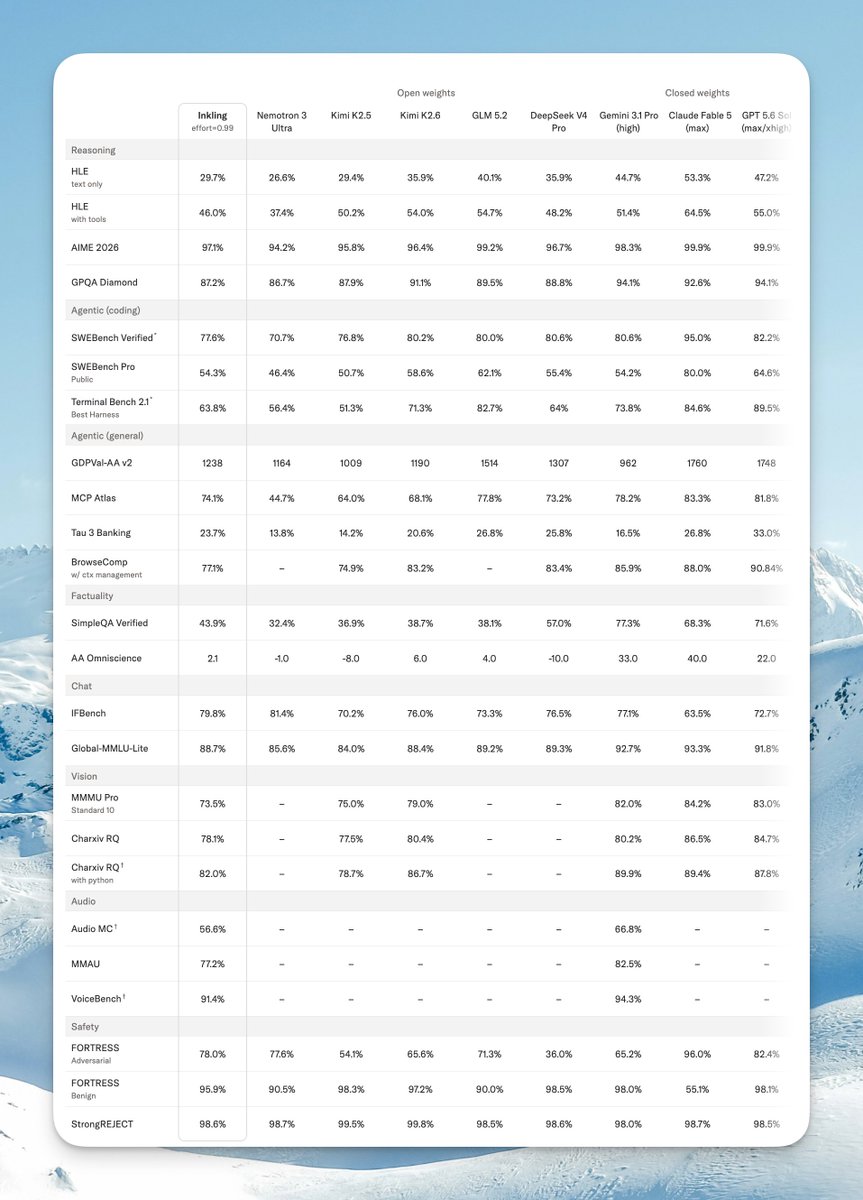
Thinking Machine launched Inkling, a multimodal MoE model, open-sourced with large scale. - Inkling released as open-source MoE model - Total parameters: 975B; activation params: 41B - Context window: 1,000,000 tokens - Native support for text, image, and audio - Small preview model available with 12B activation params - Trained on 45 trillion tokens of data - Post-training data distilled from open-source models (e.g., Kimi 2.5) - Benchmarks: stronger than Nemotron 3 Ultra and Kimi K2.5 on several tests - Mixed results vs Kimi K2.6 / DeepSeek V4 Pro across IFBench, FORTRESS, SWEBench, HLE, SimpleQA, Terminal Bench - Overall trailing GLM 5.2 on multiple benchmarks - Trailing closed models (Claude Fable 5, GPT 5.6 Sol) on agentic coding and integrated reasoning
Key insights
Inkling released as open-source multimodal MoE
Thinking Machine announced Inkling, a mixture-of-experts (MoE) multimodal model that is open-source. The model’s total parameter count was stated as 975 billion with an activation parameter count of 41 billion and a 1,000,000-token context window. Inkling natively supports text, image, and audio understanding. A smaller preview 'Small' model with 12 billion activation parameters was also released. The team stated that post-training data was distilled from a set of open-source models.
Training data scale and distillation sources
Inkling was reported to be trained on 45 trillion tokens of data. The post indicates the model’s post-training data was distilled from other open-source models, explicitly naming Kimi 2.5 as an example of source models used in distillation.
Comparative benchmarks versus open and closed models
Comparative reporting positioned Inkling as stronger than Nemotron 3 Ultra and Kimi K2.5 on several benchmarks. Against Kimi K2.6 and DeepSeek V4 Pro, Inkling showed mixed results—slightly ahead on IFBench, FORTRESS, and SWEBench Verified but behind on HLE, SimpleQA, and Terminal Bench. Overall, Inkling trailed GLM 5.2 on multiple benchmarks and lagged closed models like Claude Fable 5 and GPT 5.6 Sol on agentic coding, integrated reasoning, and factual metrics. Inkling outperformed some closed models on instruction following and refusal balance in specified benchmarks (IFBench, FORTRESS Benign).