
Transformer gating research and fine-tuning tooling
Research shows attention gating boosts performance and Hugging Face launched fine‑tuning tooling.
Key insights
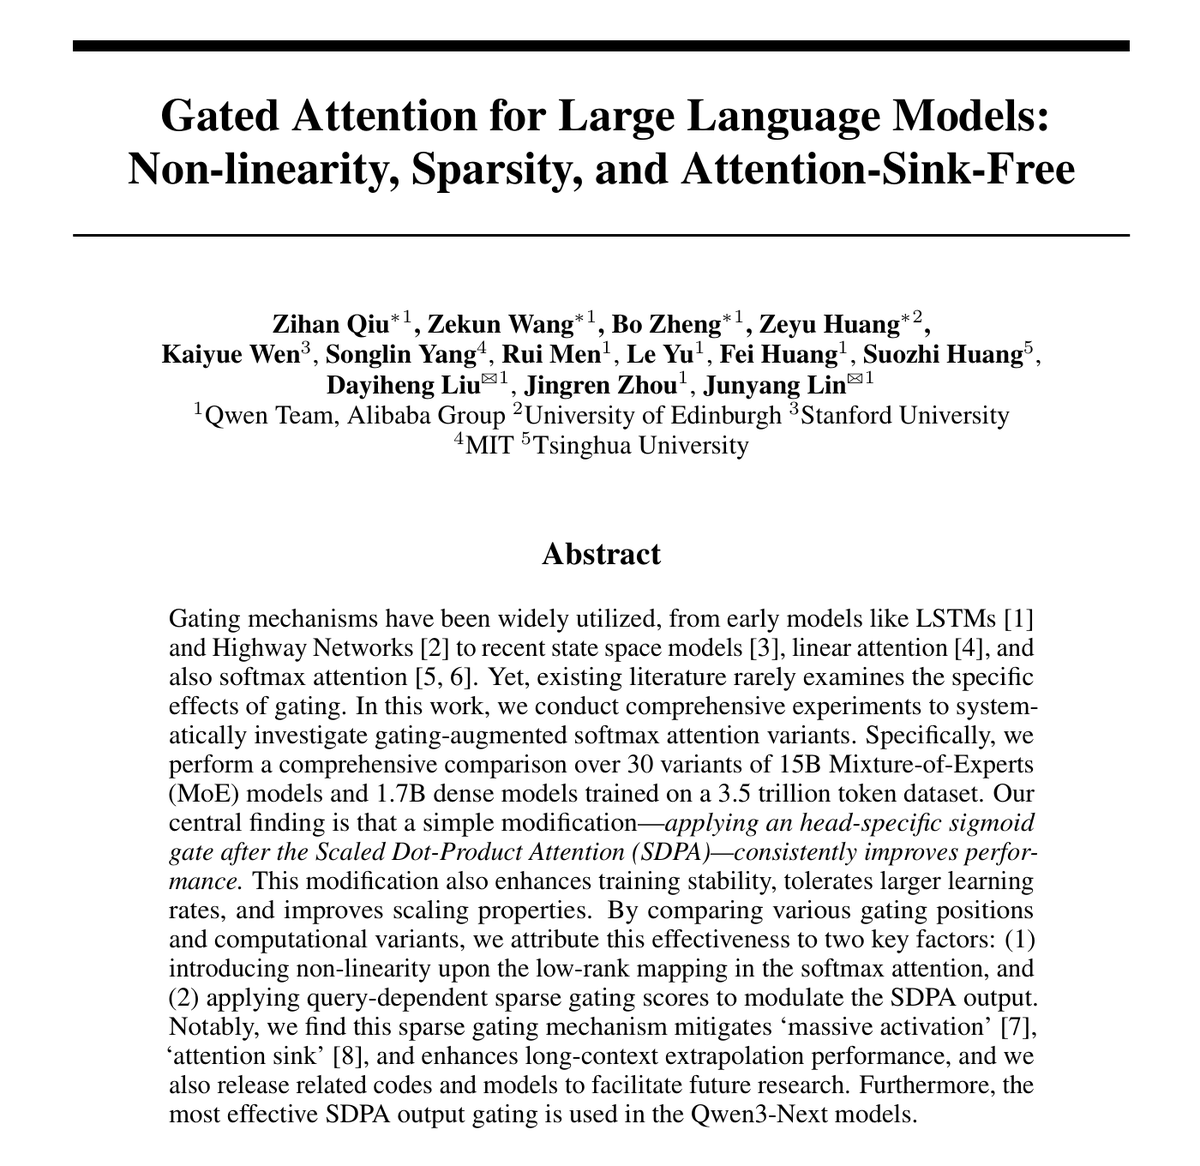
NeurIPS best paper: attention gating benefits
A NeurIPS 2025 best paper evaluated over 30 gating variants and found the best approach multiplies each attention head's output by a learned gate derived from the current token representation (per‑element gating). Reported benefits include more stable training with higher learning rates, reduction of 'attention sinks' on early tokens, and improvements on long‑text benchmarks when context windows are extended.
Hugging Face releases 'hf skills' fine‑tuning plugin
Hugging Face introduced a plugin ('hf skills') enabling fine‑tuning with SFT, DPO, and GRPO methods, automated hardware selection on HF, and a validate‑then‑produce flow with export options to GGUF for local deployment. The tool supports direct code fine‑tuning pipelines.