
TypeSafe AI launches Jev, a decision-only fast AI model
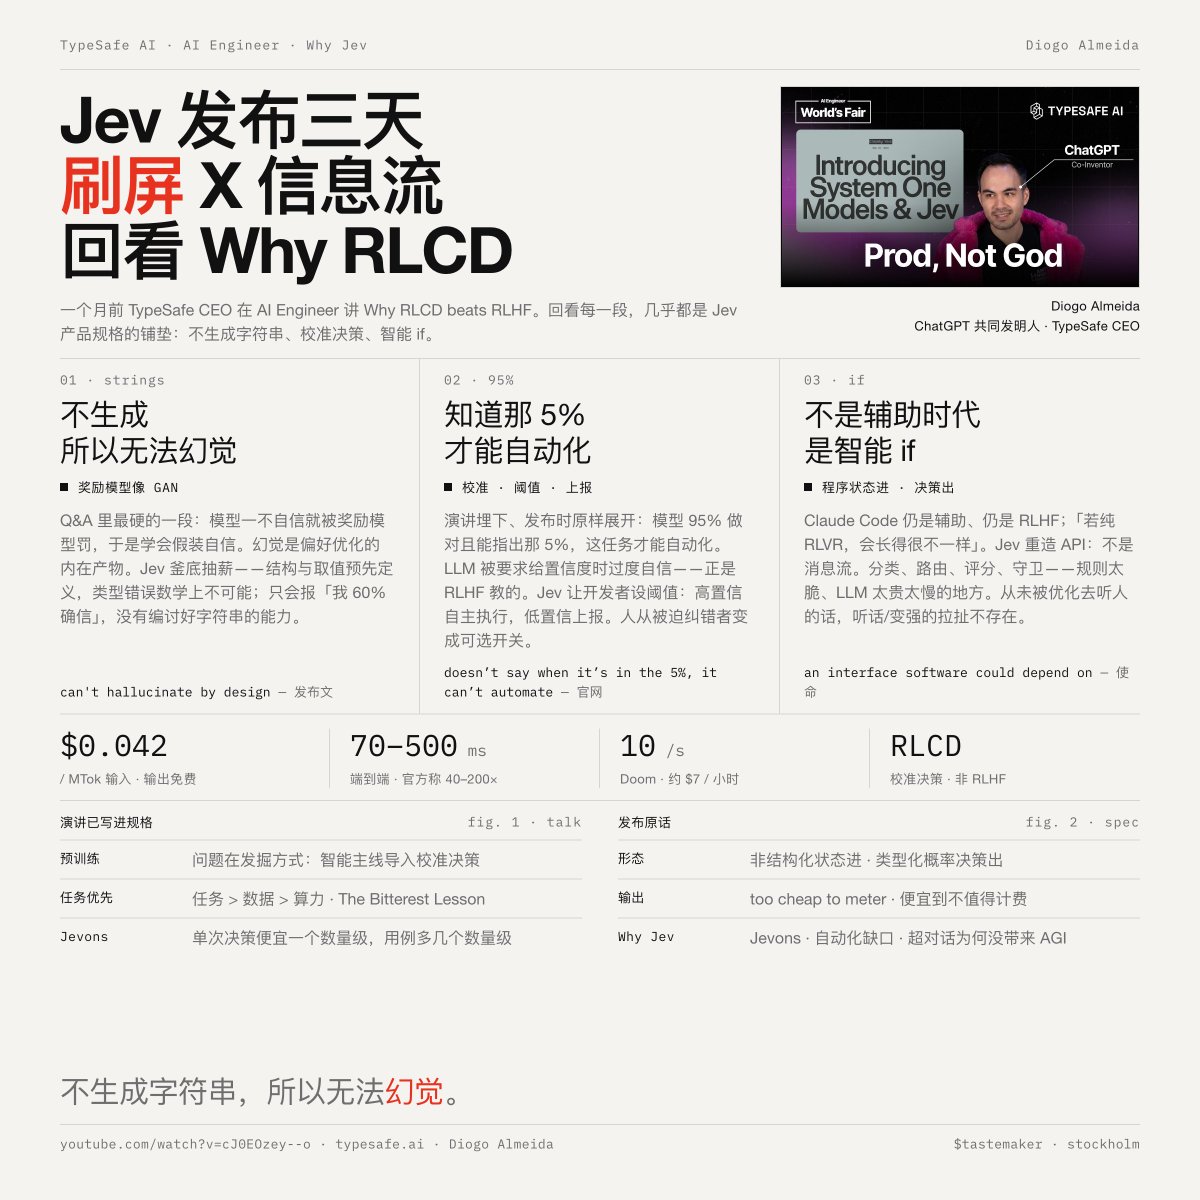
TypeSafe AI, co-founded by ChatGPT co-inventor Diogo Almeida, launched Jev, a new AI model category called System One model. Jev outputs only structured decisions with calibrated probabilities, no text generation. It achieves 70-500ms response time, input token price of $0.042 per million, and free output tokens. Designed for 'smart if-else' functions in software pipelines, it is demonstrated controlling DOOM bots and playing Wikipedia racing.
Key insights
No text generation eliminates hallucinations by design
Jev never generates free-form text, only structured decision outputs with predefined types and values. This makes type errors mathematically impossible and elimininates hallucinations. Each output comes with an epistemically honest confidence score. Diogo Almeida argued that RLHF trains models to please humans, leading to overconfidence and fabricated answers. Jev's training uses a new method called RLCD (Reinforcement Learning for Calibrated Decisions), which avoids the asymmetry of reward models that GAN-like dynamics cause.
Performance and cost advantages over traditional LLMs
Jev responds in 70-500 milliseconds compared to 3-329 seconds for leading LLMs. Input token price is $0.042 per million tokens (about $42 per billion tokens), and output tokens are free. Official claims are 20-200x faster and 40-400x cheaper at equivalent intelligence levels, based on their Workflow Evals using GPT-6 Astra and Fable 5.1 as reference. The extreme multiples represent best-case scenarios. The speed comes from parallel sampling: all outputs are computed at once, unlike autoregressive generation.
Use cases: smart if-else for software pipelines
Jev is positioned for scenarios where a smart judgment is needed without text output: intelligent branching in customer service (triage, urgency, sentiment), massive data processing (classify, tag, extract fields from millions of records), real-time applications (recommendation, dynamic pricing, game AI), and guardrails for LLM outputs (safety, format, jailbreak detection). The DOOM demo runs at ~10 queries per second costing ~$7/hour. Wikipedia racing shows pathfinding step efficiency.
Pricing philosophy: cheap enough to be invisible
TypeSafe's pricing strategy is based on the Jevons paradox: as the cost per decision drops, total consumption explodes. Output tokens are free because they are 'too cheap to meter'. The company claims to be profitable already and plans to lower prices further. They bet not on a price war per unit intelligence but on expanding the task space where same intelligence can be reused at near-zero marginal cost.
Limitations: no general reasoning or conversation
Jev is not a replacement for ChatGPT or Claude. It cannot generate text, answer questions, or hold conversations. Its output is strictly structured with predefined fields and values. The model is designed for quick, automated decisions inside code flows, not for user-facing chat. Developers must define the output schema in advance.