
Web Scraping & Automation Solutions
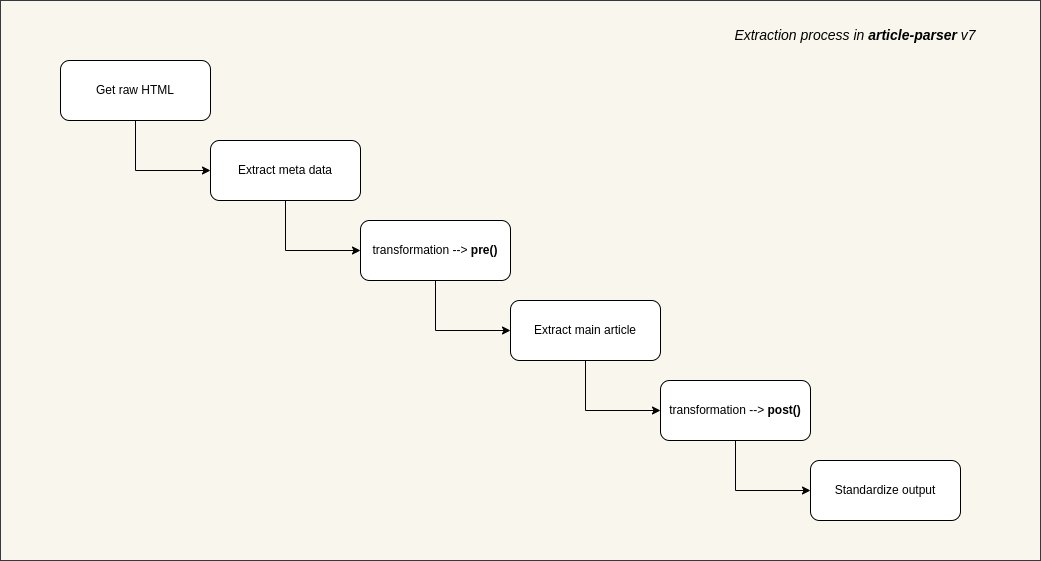
Tools and approaches for extracting article content and automating dynamic web scraping.
Key insights
article-extractor for clean article extraction
One post highlights the open-source article-extractor library designed to extract core article data from cluttered web pages, removing ads, sidebars, and navigation. It returns structured fields like title, body, cover image, author, and read time, supports custom transformations per domain, and is compatible with Node.js, Bun, and browsers, with proxy and header configuration for anti-scraping strategies.
Doubao automates dynamic mobile web scraping via device control
A reposted note reports that Doubao solved dynamic-loading issues for Xiaohongshu and Douyin by controlling Android devices: simulating swipes, performing OCR on screen captures to extract cover text, and automating interaction flows. The post contrasts Doubao's approach with prior tools (comet, dia, manus) that failed for these dynamically loaded pages.
Aggregation business models handle anti-bot hurdles
One post observes that simple aggregation and distribution remain viable strategies; it gives an example where operators route captcha challenges to backends and subcontract tasks to human workers, illustrating pragmatic solutions to scraping and automation challenges.