
EXPO-FT: A Universal Post-Training Recipe for Robotics
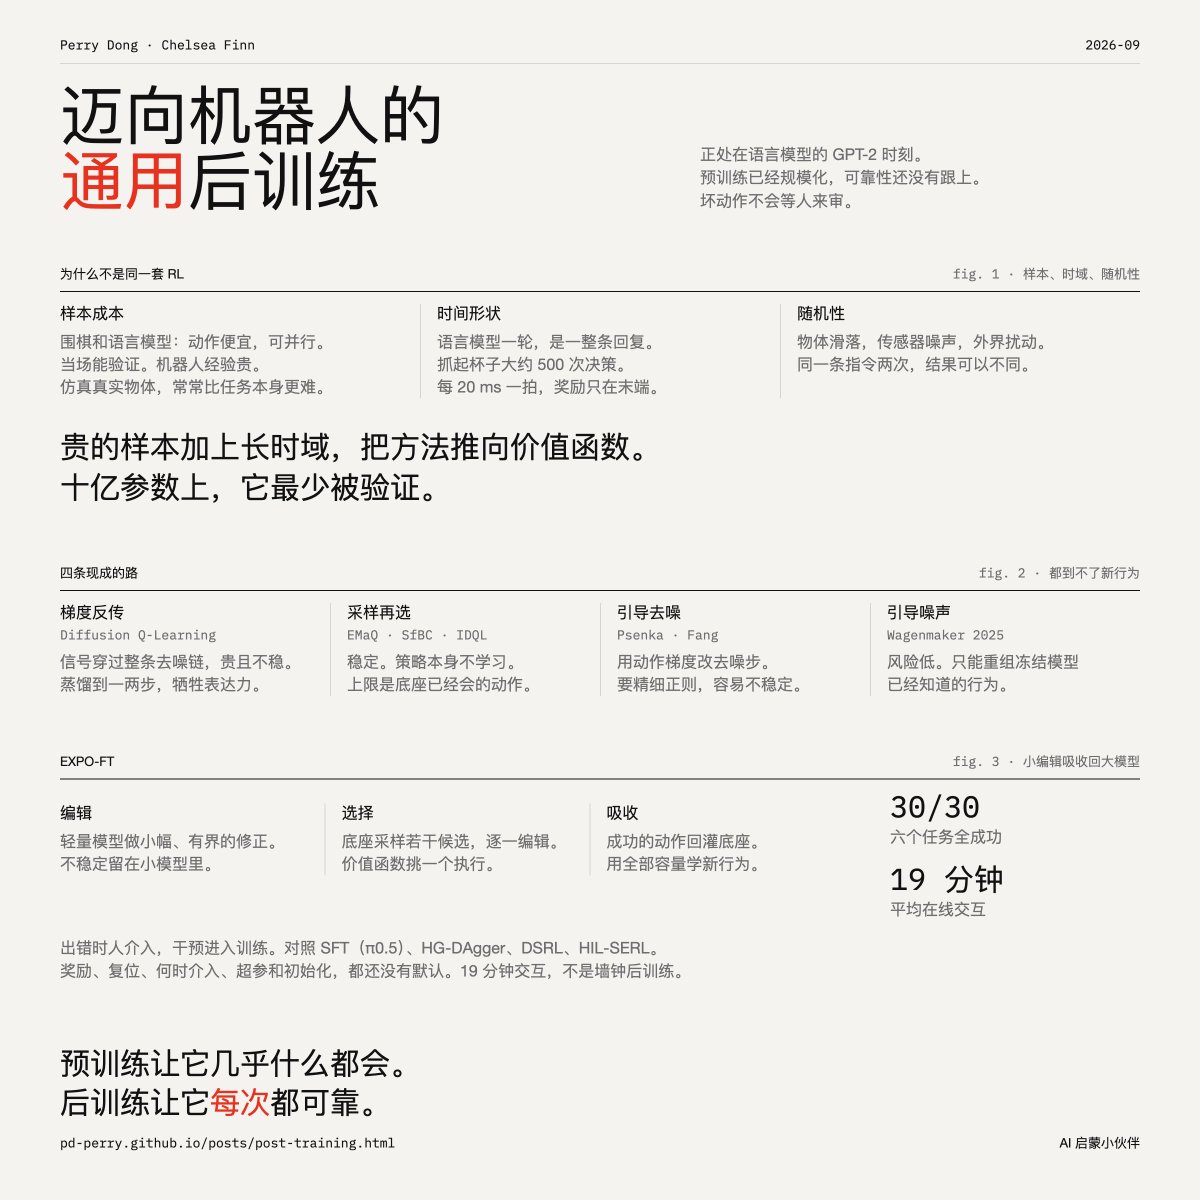
A paper proposes EXPO-FT, a post-training recipe to give robotics what RLHF and RLVR gave language models, turning broadly capable pretrained VLA robots reliable. Across six manipulation tasks it reached 30/30 success with about 19 minutes of online interaction, beating SFT on pi0.5 and HIL-SERL baselines.
Key insights
Robotics Is at Its GPT-2 Moment, Missing a Post-Training Recipe
The authors argue robotics mirrors language models before RLHF: pretraining of VLA and world-action models has scaled, giving broad but unstable capabilities, while the field lacks a standardized, reusable post-training method to turn can do into reliably does every time. Language models converged on a shared pipeline — supervised instruction tuning, RLHF, then RL with verifiable rewards — anchored by reference models with reward-hacking monitoring. Robotics needs an equivalent with stricter reliability requirements, because a robot's bad action happens immediately without waiting for human review. The recipe requires an algorithm stable on billion-parameter models learning from very little real experience, and a protocol defining success, scene resets, and human feedback, which remain manual work in robotics.
Robot RL Differs from LLM RL in Three Structural Ways
Sample cost forces off-policy reuse of historical data, since robot experience is expensive and simulating real objects can be harder than the task itself, unlike cheap, parallel, verifiable actions in Go and LLMs. Time shape makes credit assignment hard: a robot makes hundreds to thousands of chained low-level decisions, such as 20ms control steps and roughly 500 decisions to grasp a cup, with reward appearing only at the chain's end. Stochasticity from dropped objects, sensor noise, and external disturbances further corrupts credit assignment. Together these push robotics toward value-based RL, precisely the method family least validated at billion-parameter scale.
An Exclusion Map Shows Why Existing Methods Fall Short
Gradient backpropagation through diffusion denoising, the Diffusion Q-Learning family, is expensive and unstable, and distilling to 1-2 steps sacrifices expressiveness. Sample-then-select methods like EMaQ, SfBC, and IDQL are stable but the policy itself never learns, capping performance at the base model's proposal ability. Guiding denoising steps with action gradients needs delicate regularization, and guiding in input-noise space only recombines frozen model behaviors, with the skill ceiling set by pretraining. Deeper issues: classic value-based RL assumes Gaussian unimodal policies while frontier models express multimodal behavior via diffusion or flow, and bootstrapping — learning from its own future predictions treated as ground truth — amplifies into instability at billion-parameter scale.
EXPO-FT Splits Labor Between a Small Editor and the Base Model
The recipe has three stages. A lightweight edit policy makes bounded small corrections to base-model candidate actions, pushing them toward value peaks within a mode, which confines RL instability to the small model so the large model never produces dangerous actions. At execution, the robot samples several candidates from the base model, edits each, and a value function selects the best one. Absorption then writes selected successful actions back into the base model's training, so improvements found by the small editor are absorbed by the base model's full capacity as genuinely learned behavior rather than noise-space recombination. Humans act as supervisors, intervening on errors with intervention data entering training, analogous to Waymo's remote safety operators.
30 of 30 Successes in Six Manipulation Tasks
Across six complex manipulation tasks — routing and plugging in fairy lights around a hook, billiard pocketing, placing a flower in a vase, flipping an egg, and balancing a ball — EXPO-FT achieved 30 out of 30 successes with an average of only 19 minutes of online interaction. This substantially exceeded baselines including SFT on pi0.5, HG-DAgger, DSRL, and HIL-SERL, whose average success counts ranged roughly between 5.5 and 20.5.
Universal Remains Open Until Protocols Converge
The authors list questions the community must settle before the recipe becomes plug-and-play: how to specify rewards, since robotics lacks an RLVR equivalent and learned success classifiers or reward models are promising directions; who performs resets, with learned reset policies and reversible task design as options; how much and when humans intervene and how their input is used; default hyperparameters such as learning rate, UTD ratio, stopping criteria, horizon, and control frequency; and how to weight initialization data. They released an EXPO-FT tuning reference as a first step toward this convergence.